90% of US working hours are spent on tasks not covered well by AI benchmarks
Mercor has published a Benchmark Map that measures how well 29 selected AI benchmarks cover tasks across the US labor force. The map uses the Department of Labor’s O*NET taxonomy, which divides the workforce into 923 occupations, 22 job families, and 18,797 tasks. A task is counted as covered when an LLM judge maps at least five benchmark prompts to it; one prompt can map to multiple tasks. Only 208 of 923 occupations have at least one task meeting that threshold, while six of 22 job families have none. Mercor estimates that 90% of US working hours are spent on tasks with little or no coverage in its initial benchmark set, making economy-wide assessments of AI capability difficult. The organization says benchmark coverage disproportionately favors AI-exposed tasks, with O*NET tasks rated exposed to AI about six times more likely to appear than unexposed tasks. Tasks in occupations with larger wage bills and tasks rated most important are also overrepresented. Mercor found that reweighting APEX benchmark scores so each O*NET task counts equally changed model results little for investment banking, law, accounting, and software engineering. Less than one-third of relevant tasks in those four occupations had sufficient APEX coverage. Mercor characterizes its estimates as provisional because its benchmark list is incomplete, selection criteria involve judgment, and excluding saturated benchmarks can understate coverage.
mercor.com
9 min
8h ago
Anthropic: Introducing The Conceptual Reasoning Index
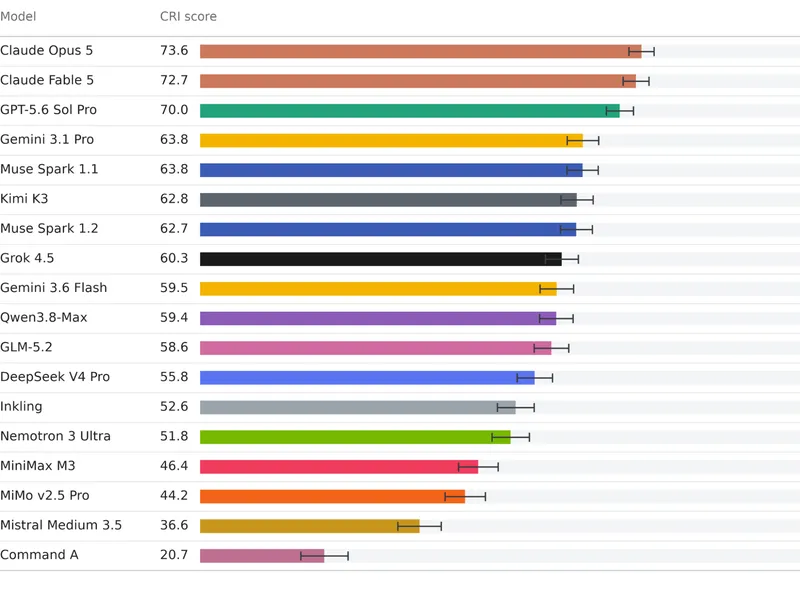
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
DeepSeek V4 Flash 0731
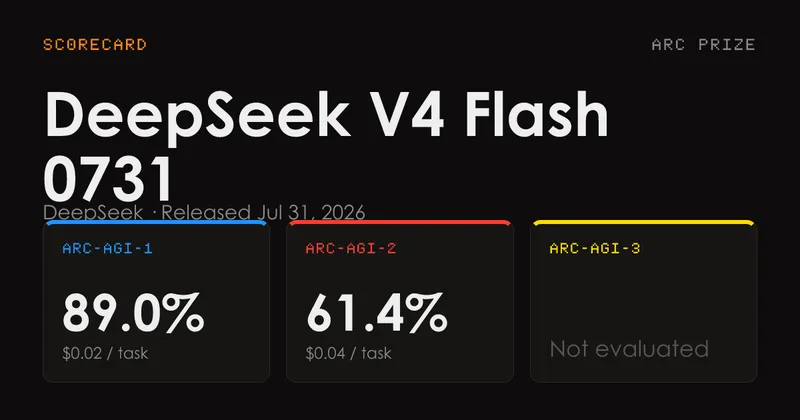
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026

Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026
90% of US working hours are spent on tasks not covered well by AI benchmarks
Mercor has published a Benchmark Map that measures how well 29 selected AI benchmarks cover tasks across the US labor force. The map uses the Department of Labor’s O*NET taxonomy, which divides the workforce into 923 occupations, 22 job families, and 18,797 tasks. A task is counted as covered when an LLM judge maps at least five benchmark prompts to it; one prompt can map to multiple tasks. Only 208 of 923 occupations have at least one task meeting that threshold, while six of 22 job families have none. Mercor estimates that 90% of US working hours are spent on tasks with little or no coverage in its initial benchmark set, making economy-wide assessments of AI capability difficult. The organization says benchmark coverage disproportionately favors AI-exposed tasks, with O*NET tasks rated exposed to AI about six times more likely to appear than unexposed tasks. Tasks in occupations with larger wage bills and tasks rated most important are also overrepresented. Mercor found that reweighting APEX benchmark scores so each O*NET task counts equally changed model results little for investment banking, law, accounting, and software engineering. Less than one-third of relevant tasks in those four occupations had sufficient APEX coverage. Mercor characterizes its estimates as provisional because its benchmark list is incomplete, selection criteria involve judgment, and excluding saturated benchmarks can understate coverage.
mercor.com
9 min
8h ago
DeepSeek V4 Flash 0731
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026
Anthropic: Introducing The Conceptual Reasoning Index
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026
90% of US working hours are spent on tasks not covered well by AI benchmarks
Mercor has published a Benchmark Map that measures how well 29 selected AI benchmarks cover tasks across the US labor force. The map uses the Department of Labor’s O*NET taxonomy, which divides the workforce into 923 occupations, 22 job families, and 18,797 tasks. A task is counted as covered when an LLM judge maps at least five benchmark prompts to it; one prompt can map to multiple tasks. Only 208 of 923 occupations have at least one task meeting that threshold, while six of 22 job families have none. Mercor estimates that 90% of US working hours are spent on tasks with little or no coverage in its initial benchmark set, making economy-wide assessments of AI capability difficult. The organization says benchmark coverage disproportionately favors AI-exposed tasks, with O*NET tasks rated exposed to AI about six times more likely to appear than unexposed tasks. Tasks in occupations with larger wage bills and tasks rated most important are also overrepresented. Mercor found that reweighting APEX benchmark scores so each O*NET task counts equally changed model results little for investment banking, law, accounting, and software engineering. Less than one-third of relevant tasks in those four occupations had sufficient APEX coverage. Mercor characterizes its estimates as provisional because its benchmark list is incomplete, selection criteria involve judgment, and excluding saturated benchmarks can understate coverage.
mercor.com
9 min
8h ago
When AI Benchmarks Plateau: A Systematic Study of Benchmark Saturation
AI benchmarks are essential for assessing model performance and informing deployment choices. However, they often reach saturation, reducing their effectiveness in distinguishing between models and limiting their long-term utility.
arxiv.org
2 min
8/4/2026
Are AI Labs Pelicanmaxxing?
Simon Willison has tested major LLM releases using the prompt “Generate an SVG of a pelican riding a bicycle,” creating an informal benchmark in AI. The results often receive significant engagement on platforms like Hacker News, sparking discussions about the benchmark's usefulness.
dylancastillo.co
11 min
7/22/2026
Anthropic: Introducing The Conceptual Reasoning Index
The Conceptual Reasoning Index introduces a suite of three benchmarks to evaluate AI capabilities in understanding situations, planning for the future, and developing risk mitigations. Access to the primary conceptual dataset, LMCA, is available upon request.
alignment.anthropic.com
6 min
8/13/2026
What's the largest software project AI can complete on its own?
MirrorCode is a benchmark designed to evaluate AI models on long-horizon coding tasks by requiring them to reimplement entire programs end-to-end without access to the original source code. Solutions generated by AI must match the output of the original program to be considered successful.
epoch.ai
4 min
8/3/2026
DeepSeek V4 Flash 0731
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
arcprize.org
21 min
8/7/2026
Any text-to-SQL benchmark should address difficulties of real-world data stores
Text-to-SQL benchmarks must consider the complexities and challenges posed by real-world data stores. Effective evaluation should include factors like data variability, schema complexity, and query performance.
cacm.acm.org
1 min
7/22/2026
No more articles to load