Launch HN: Discovered Materials (YC P26) – AI agents to discover new materials
The Material Discovery Bench evaluates models on their ability to propose novel, BEOL-compatible crystalline materials that meet specific targets for thermal conductivity ($kappa), static dielectric constant ($epsilon), Young's modulus, and shear modulus. The benchmark utilizes a harness, tools, and graders to measure model performance based on these criteria.
discoveredmaterials.com
8 min
8/12/2026
Handbook.md shows that long policy documents do not reliably govern agents
HANDBOOK.md introduces a benchmark specifically designed to evaluate long-context agentic instruction following in language-model agents. This benchmark assesses how well agents adhere to a system prompt, policy file, or skills document during their operations.
arxiv.org
2 min
7/29/2026
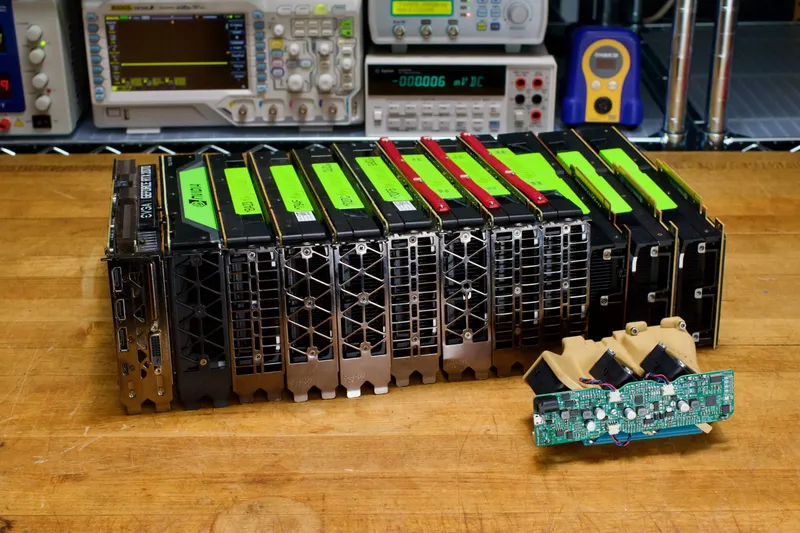
Benchmarking 15 "E-Waste" GPUs with Modern Workloads
Decommissioned NVIDIA enterprise GPUs, such as the K80, P100, and V100, are available at prices ranging from $60 to under $200. A project has been initiated to benchmark these Tesla GPUs to assess their usability in modern applications.
esologic.com
11 min
7/13/2026
MTG Bench: Testing how well LLMs can play Magic
Fable 5 successfully plays a scry land and examines the top card of the deck, while Gemini 3.5 performs a complex turn involving scry, discover, and tutor effects. The benchmark tests the capability of LLMs to play Magic: The Gathering without relying on a rules engine, suggesting that high-performing LLMs should not require one.
mtgautodeck.com
5 min
6/11/2026
MacBook M5 Pro and Qwen3.5 = Local AI Security System
Qwen3.5-9B achieves a score of 93.8%, closely trailing GPT-5.4, while operating entirely on a MacBook Pro M5 at 25 tok/s and 765ms TTFT, using 13.8 GB of unified memory. The benchmark evaluates 96 tests across 15 suites focusing on tool use, security classification, and event deduplication, with zero API costs and full data privacy.
sharpai.org
3 min
3/20/2026
Launch HN: Discovered Materials (YC P26) – AI agents to discover new materials
The Material Discovery Bench evaluates models on their ability to propose novel, BEOL-compatible crystalline materials that meet specific targets for thermal conductivity ($kappa), static dielectric constant ($epsilon), Young's modulus, and shear modulus. The benchmark utilizes a harness, tools, and graders to measure model performance based on these criteria.
discoveredmaterials.com
8 min
8/12/2026
Benchmarking 15 "E-Waste" GPUs with Modern Workloads
Decommissioned NVIDIA enterprise GPUs, such as the K80, P100, and V100, are available at prices ranging from $60 to under $200. A project has been initiated to benchmark these Tesla GPUs to assess their usability in modern applications.
esologic.com
11 min
7/13/2026
Handbook.md shows that long policy documents do not reliably govern agents
HANDBOOK.md introduces a benchmark specifically designed to evaluate long-context agentic instruction following in language-model agents. This benchmark assesses how well agents adhere to a system prompt, policy file, or skills document during their operations.
arxiv.org
2 min
7/29/2026
MTG Bench: Testing how well LLMs can play Magic
Fable 5 successfully plays a scry land and examines the top card of the deck, while Gemini 3.5 performs a complex turn involving scry, discover, and tutor effects. The benchmark tests the capability of LLMs to play Magic: The Gathering without relying on a rules engine, suggesting that high-performing LLMs should not require one.
mtgautodeck.com
5 min
6/11/2026
MacBook M5 Pro and Qwen3.5 = Local AI Security System
Qwen3.5-9B achieves a score of 93.8%, closely trailing GPT-5.4, while operating entirely on a MacBook Pro M5 at 25 tok/s and 765ms TTFT, using 13.8 GB of unified memory. The benchmark evaluates 96 tests across 15 suites focusing on tool use, security classification, and event deduplication, with zero API costs and full data privacy.
sharpai.org
3 min
3/20/2026
Launch HN: Discovered Materials (YC P26) – AI agents to discover new materials
The Material Discovery Bench evaluates models on their ability to propose novel, BEOL-compatible crystalline materials that meet specific targets for thermal conductivity ($kappa), static dielectric constant ($epsilon), Young's modulus, and shear modulus. The benchmark utilizes a harness, tools, and graders to measure model performance based on these criteria.
discoveredmaterials.com
8 min
8/12/2026
MTG Bench: Testing how well LLMs can play Magic
Fable 5 successfully plays a scry land and examines the top card of the deck, while Gemini 3.5 performs a complex turn involving scry, discover, and tutor effects. The benchmark tests the capability of LLMs to play Magic: The Gathering without relying on a rules engine, suggesting that high-performing LLMs should not require one.
mtgautodeck.com
5 min
6/11/2026
Handbook.md shows that long policy documents do not reliably govern agents
HANDBOOK.md introduces a benchmark specifically designed to evaluate long-context agentic instruction following in language-model agents. This benchmark assesses how well agents adhere to a system prompt, policy file, or skills document during their operations.
arxiv.org
2 min
7/29/2026
Benchmarking 15 "E-Waste" GPUs with Modern Workloads
Decommissioned NVIDIA enterprise GPUs, such as the K80, P100, and V100, are available at prices ranging from $60 to under $200. A project has been initiated to benchmark these Tesla GPUs to assess their usability in modern applications.
esologic.com
11 min
7/13/2026
MacBook M5 Pro and Qwen3.5 = Local AI Security System
Qwen3.5-9B achieves a score of 93.8%, closely trailing GPT-5.4, while operating entirely on a MacBook Pro M5 at 25 tok/s and 765ms TTFT, using 13.8 GB of unified memory. The benchmark evaluates 96 tests across 15 suites focusing on tool use, security classification, and event deduplication, with zero API costs and full data privacy.
sharpai.org
3 min
3/20/2026
No more articles to load