GitLost: We Tricked GitHub's AI Agent into Leaking Private Repos
Noma Labs identified a prompt injection vulnerability in GitHub's Agentic Workflows, allowing unauthenticated attackers to access private repository data by posting a crafted GitHub Issue in a public repository within the same organization. This vulnerability has been named GitLost.
noma.security
5 min
7/8/2026
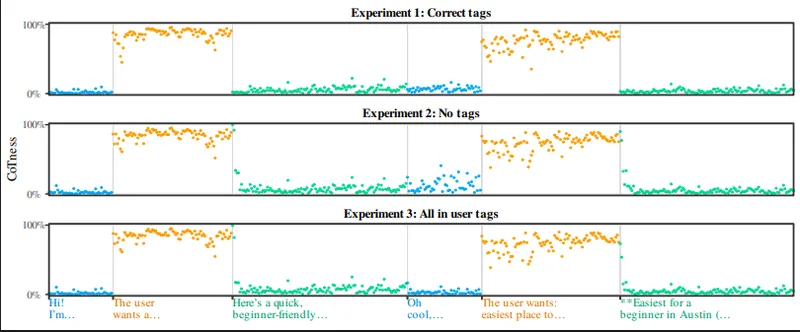
Prompt Injection as Role Confusion
Prompt injection exploits a flaw in how large language models (LLMs) perceive roles, leading to new attack vectors and insights into model behavior. Understanding roles is crucial for predicting the success of these attacks and developing a research framework around them.
role-confusion.github.io
26 min
6/22/2026
Google Translate apparently vulnerable to prompt injection
Prompt injection in Google Translate can reveal the underlying instruction-following language model. Responses indicate that the model lacks strong boundaries between processing content and following instructions.
lesswrong.com
5 min
2/7/2026
GitLost: We Tricked GitHub's AI Agent into Leaking Private Repos
Noma Labs identified a prompt injection vulnerability in GitHub's Agentic Workflows, allowing unauthenticated attackers to access private repository data by posting a crafted GitHub Issue in a public repository within the same organization. This vulnerability has been named GitLost.
noma.security
5 min
7/8/2026
Google Translate apparently vulnerable to prompt injection
Prompt injection in Google Translate can reveal the underlying instruction-following language model. Responses indicate that the model lacks strong boundaries between processing content and following instructions.
lesswrong.com
5 min
2/7/2026
Prompt Injection as Role Confusion
Prompt injection exploits a flaw in how large language models (LLMs) perceive roles, leading to new attack vectors and insights into model behavior. Understanding roles is crucial for predicting the success of these attacks and developing a research framework around them.
role-confusion.github.io
26 min
6/22/2026
GitLost: We Tricked GitHub's AI Agent into Leaking Private Repos
Noma Labs identified a prompt injection vulnerability in GitHub's Agentic Workflows, allowing unauthenticated attackers to access private repository data by posting a crafted GitHub Issue in a public repository within the same organization. This vulnerability has been named GitLost.
noma.security
5 min
7/8/2026
Prompt Injection as Role Confusion
Prompt injection exploits a flaw in how large language models (LLMs) perceive roles, leading to new attack vectors and insights into model behavior. Understanding roles is crucial for predicting the success of these attacks and developing a research framework around them.
role-confusion.github.io
26 min
6/22/2026
Google Translate apparently vulnerable to prompt injection
Prompt injection in Google Translate can reveal the underlying instruction-following language model. Responses indicate that the model lacks strong boundaries between processing content and following instructions.
lesswrong.com
5 min
2/7/2026
No more articles to load