Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026

Mesh LLM: distributed AI computing on iroh
Mesh LLM enables distributed AI computing on the iroh platform, allowing teams to run large language models without relying on centralized data centers. This setup provides greater control over model updates, data privacy, and operational costs.
iroh.computer
5 min
7/11/2026
OpenAI and Broadcom unveil LLM-optimized inference chip
OpenAI and Broadcom have unveiled a first-generation LLM-optimized inference chip designed to deliver significantly better performance per watt than current state-of-the-art options. The chip, developed in nine months, is built for current and future large language models and will be deployed at gigawatt scale with data center partners.
openai.com
5 min
6/24/2026

Erin Brockovich made a map to track data centers around the country
Erin Brockovich has created a tool to map data centers across the United States and provides a form for community members to report on these centers and their local impacts. The initiative aims to address the varying reception of data centers in different towns, where some are welcomed while others face delays or opposition.
niemanlab.org
1 min
5/27/2026

Tiny Corp's Exabox
exabox preorder is live. we considered raising a round to buy a datacenter, but with exaboxes we don't have to and can build out at our own pace. exaboxes just require a concrete slab and a big plug. ポスト 会話 Xを使ってみよう 今すぐ登録して、タイムラインをカスタマイズしましょう。 Google で登録Google で登録。新しいタブで開きます アカウントを作成
twitter.com
1 min
4/6/2026
Arm AGI CPU
Arm has announced the Arm AGI CPU, a new class of production-ready silicon built on the Arm Neoverse platform, aimed at enhancing AI infrastructure. This marks Arm's first foray into delivering its own silicon products, expanding the options for customers deploying Arm compute.
newsroom.arm.com
8 min
3/24/2026
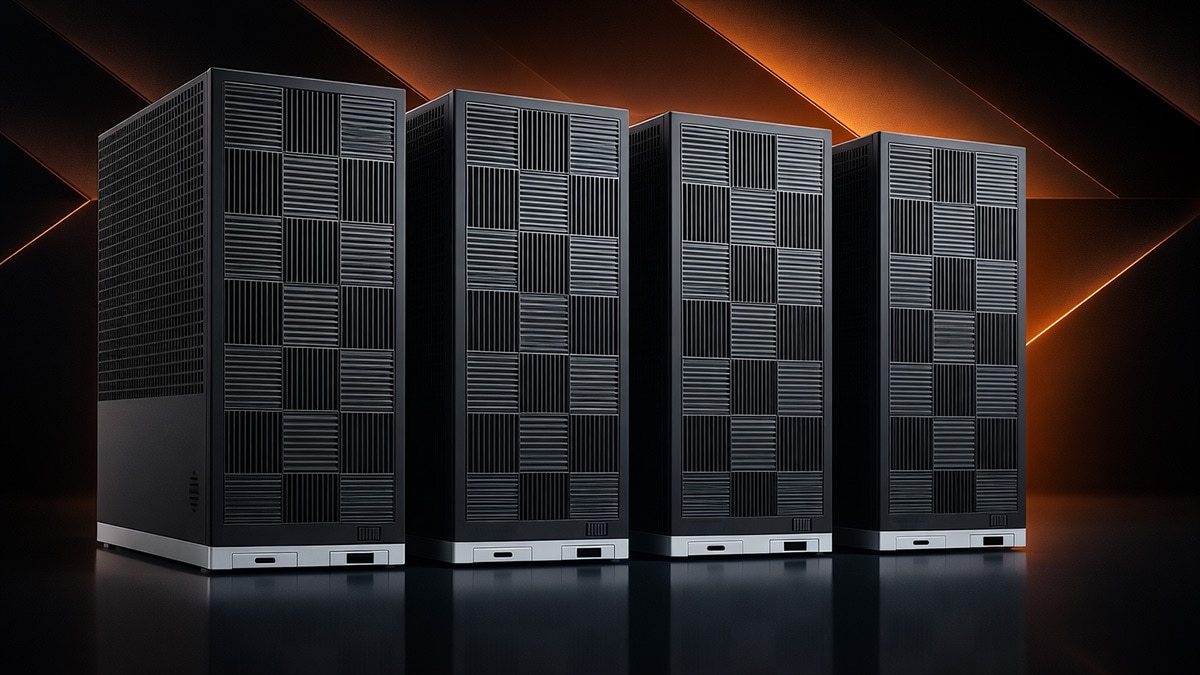
Running a One Trillion-Parameter LLM Locally on AMD Ryzen AI Max+ Cluster
A small-scale distributed inference cluster can be built using AMD’s Ryzen™ AI Max+ AI PC platform to run a one trillion-parameter Large Language Model. A four-node cluster of Framework Desktop systems demonstrates the local inference of the Kimi K2.5 open-source model.
amd.com
14 min
3/1/2026
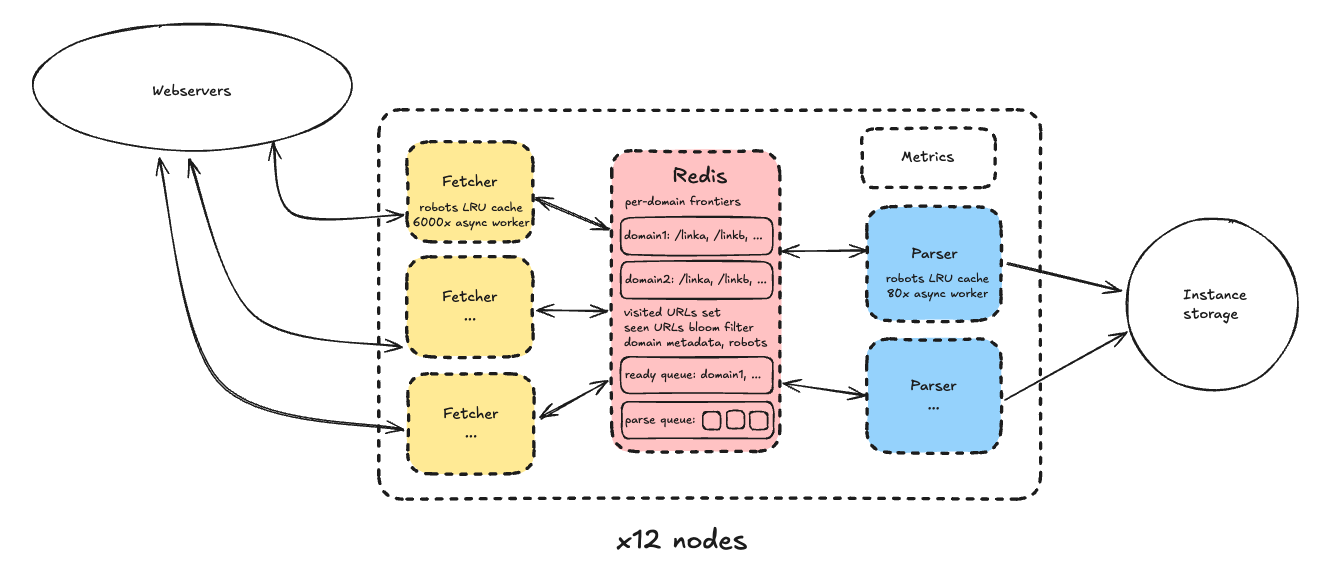
Crawling a billion web pages in just over 24 hours, in 2025
Crawling 1.005 billion web pages took just over 25.5 hours and cost $462. Advances in technology, such as multi-core CPUs and NVMe solid-state drives, have significantly improved web crawling efficiency since 2012.
andrewkchan.dev
15 min
2/23/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
OpenAI and Broadcom unveil LLM-optimized inference chip
OpenAI and Broadcom have unveiled a first-generation LLM-optimized inference chip designed to deliver significantly better performance per watt than current state-of-the-art options. The chip, developed in nine months, is built for current and future large language models and will be deployed at gigawatt scale with data center partners.
openai.com
5 min
6/24/2026
The eighth-generation TPU: An architecture deep dive
TPU 8t is designed for frontier-model training, while TPU 8i focuses on large-scale inference and reinforcement learning. Both are engineered with system-level co-design to enhance the AI lifecycle.
cloud.google.com
1 min
4/22/2026
Arm AGI CPU
Arm has announced the Arm AGI CPU, a new class of production-ready silicon built on the Arm Neoverse platform, aimed at enhancing AI infrastructure. This marks Arm's first foray into delivering its own silicon products, expanding the options for customers deploying Arm compute.
newsroom.arm.com
8 min
3/24/2026
Crawling a billion web pages in just over 24 hours, in 2025
Crawling 1.005 billion web pages took just over 25.5 hours and cost $462. Advances in technology, such as multi-core CPUs and NVMe solid-state drives, have significantly improved web crawling efficiency since 2012.
andrewkchan.dev
15 min
2/23/2026
Mesh LLM: distributed AI computing on iroh
Mesh LLM enables distributed AI computing on the iroh platform, allowing teams to run large language models without relying on centralized data centers. This setup provides greater control over model updates, data privacy, and operational costs.
iroh.computer
5 min
7/11/2026
Erin Brockovich made a map to track data centers around the country
Erin Brockovich has created a tool to map data centers across the United States and provides a form for community members to report on these centers and their local impacts. The initiative aims to address the varying reception of data centers in different towns, where some are welcomed while others face delays or opposition.
niemanlab.org
1 min
5/27/2026
Tiny Corp's Exabox
exabox preorder is live. we considered raising a round to buy a datacenter, but with exaboxes we don't have to and can build out at our own pace. exaboxes just require a concrete slab and a big plug. ポスト 会話 Xを使ってみよう 今すぐ登録して、タイムラインをカスタマイズしましょう。 Google で登録Google で登録。新しいタブで開きます アカウントを作成
twitter.com
1 min
4/6/2026
Running a One Trillion-Parameter LLM Locally on AMD Ryzen AI Max+ Cluster
A small-scale distributed inference cluster can be built using AMD’s Ryzen™ AI Max+ AI PC platform to run a one trillion-parameter Large Language Model. A four-node cluster of Framework Desktop systems demonstrates the local inference of the Kimi K2.5 open-source model.
amd.com
14 min
3/1/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
Erin Brockovich made a map to track data centers around the country
Erin Brockovich has created a tool to map data centers across the United States and provides a form for community members to report on these centers and their local impacts. The initiative aims to address the varying reception of data centers in different towns, where some are welcomed while others face delays or opposition.
niemanlab.org
1 min
5/27/2026
Arm AGI CPU
Arm has announced the Arm AGI CPU, a new class of production-ready silicon built on the Arm Neoverse platform, aimed at enhancing AI infrastructure. This marks Arm's first foray into delivering its own silicon products, expanding the options for customers deploying Arm compute.
newsroom.arm.com
8 min
3/24/2026
Mesh LLM: distributed AI computing on iroh
Mesh LLM enables distributed AI computing on the iroh platform, allowing teams to run large language models without relying on centralized data centers. This setup provides greater control over model updates, data privacy, and operational costs.
iroh.computer
5 min
7/11/2026
The eighth-generation TPU: An architecture deep dive
TPU 8t is designed for frontier-model training, while TPU 8i focuses on large-scale inference and reinforcement learning. Both are engineered with system-level co-design to enhance the AI lifecycle.
cloud.google.com
1 min
4/22/2026
Running a One Trillion-Parameter LLM Locally on AMD Ryzen AI Max+ Cluster
A small-scale distributed inference cluster can be built using AMD’s Ryzen™ AI Max+ AI PC platform to run a one trillion-parameter Large Language Model. A four-node cluster of Framework Desktop systems demonstrates the local inference of the Kimi K2.5 open-source model.
amd.com
14 min
3/1/2026
OpenAI and Broadcom unveil LLM-optimized inference chip
OpenAI and Broadcom have unveiled a first-generation LLM-optimized inference chip designed to deliver significantly better performance per watt than current state-of-the-art options. The chip, developed in nine months, is built for current and future large language models and will be deployed at gigawatt scale with data center partners.
openai.com
5 min
6/24/2026
Tiny Corp's Exabox
exabox preorder is live. we considered raising a round to buy a datacenter, but with exaboxes we don't have to and can build out at our own pace. exaboxes just require a concrete slab and a big plug. ポスト 会話 Xを使ってみよう 今すぐ登録して、タイムラインをカスタマイズしましょう。 Google で登録Google で登録。新しいタブで開きます アカウントを作成
twitter.com
1 min
4/6/2026
Crawling a billion web pages in just over 24 hours, in 2025
Crawling 1.005 billion web pages took just over 25.5 hours and cost $462. Advances in technology, such as multi-core CPUs and NVMe solid-state drives, have significantly improved web crawling efficiency since 2012.
andrewkchan.dev
15 min
2/23/2026
No more articles to load