FLUX 3 Image Klein
Black Forest Labs has released FLUX 3 Image Klein, a 5.6-billion-parameter open-weights model for text-to-image generation, image editing, and multi-reference generation using up to 10 reference images. The model supports native 4K output, bounding-box controls for element placement or constrained edits, and pixel-perfect editing. Base and step-distilled versions are available under the FLUX Kommunity License, alongside FP8, INT8, and NVFP4 builds developed with NVIDIA support. Black Forest Labs says its internal evaluations rank Klein first among compared open-weight models for text-to-image generation, multi-reference generation, and image editing, ahead of larger models including Qwen-Image 2.1 and Krea 2. The company also says Klein scored above Ideogram V4.5 and FLUX.2 [pro] in its comparisons. INT8 weights let the model run through ComfyUI or Diffusers on NVIDIA GeForce RTX GPUs with 8GB of VRAM; the company reports roughly four seconds per 1-megapixel image on an RTX 5090 and under nine seconds on an RTX 4070. The distilled API model, flux-3-image-klein, starts at $0.009 per 1K image. Free commercial use applies to individuals and companies with under $5 million in annual revenue, while larger organizations require self-hosted licensing or API access.
bfl.ai
5 min
6h ago
GLM-5.3-Flash
Z.ai published a post titled “GLM-5.3-Flash.” The available source text provides no details about the model’s capabilities, release date, technical specifications, pricing, benchmarks, availability, or intended use. The post was submitted by Philpax and had received 529 points and 239 comments at the time represented by the source text.
z.ai
1 min
8/26/2026
GPT 5.6 Sol 20% price reduction
OpenAI’s GPT-5.6 Sol is a frontier model for complex professional work and the top tier of the GPT-5.6 family. The gpt-5.6 alias routes requests to GPT-5.6 Sol, which roughly corresponds to the unsuffixed model tier in earlier GPT-5 families. It accepts text and image inputs and produces text output, with a 1,050,000-token context window, a maximum output of 128,000 tokens, and a February 16, 2026 knowledge cutoff. The model supports reasoning-effort settings of none, low, medium, high, xhigh, and max; medium is the default. It supports streaming, function calling, structured outputs, and a range of Responses API tools, including web search, file search, image generation, code interpreter, hosted shell, computer use, MCP, and tool search. Fine-tuning is not supported. GPT-5.6 Sol costs $4 per million input tokens, $0.40 per million cached-input tokens, and $20 per million output tokens. OpenAI says these rates represent 20% lower input pricing and 33% lower output pricing, with promotional pricing available at least through November 21, 2026. Requests containing more than 272,000 input tokens are billed at twice the input rate and 1.5 times the output rate for the entire request.
developers.openai.com
2 min
8/22/2026
Unsloth Dynamic 3.0 GGUFs
Unsloth released Dynamic v3.0 GGUF quantizations for Qwen3.8-27B, a post-training quantization format designed to reduce model storage requirements while preserving behavior close to the bfloat16 model. The new GGUF files work with inference engines including llama.cpp and Unsloth Desktop. Unsloth claims its v3.0 quants provide more than 10% higher top-1% accuracy at equivalent size than other providers’ versions, with improved results on KL Divergence and its Divergence-300 @32 evaluation. Dynamic v3.0 uses a higher-quality imatrix calibration dataset refined for agentic coding, chat, and multilingual use, along with revised layer selection and additional quantization techniques. Unsloth says it does not train on the calibration data or use quantization-aware training or quantization-aware distillation; it publishes its imatrix file for community testing and reuse. Its 300-prompt Divergence-300 benchmark uses held-out samples from Terminal-Bench 2.1, DeepSWE, Harbor, MathArena 2025-26, and non-Latin and long-document prompts, comparing 32-token greedy decoding trajectories against BF16. For smaller variants, Unsloth removed the MTP module from UD-Q2_K_XL quants of 8.37GB or less, saving roughly 500MB; a separate Q4_0 MTP module remains available. The 6.2GB UD-IQ1_S quant, without MTP, retains about 72% top-1% accuracy while being 89% smaller, according to Unsloth.
unsloth.ai
11 min
8/19/2026
Roboflow Playground: Try and Compare 30 Computer Vision Models
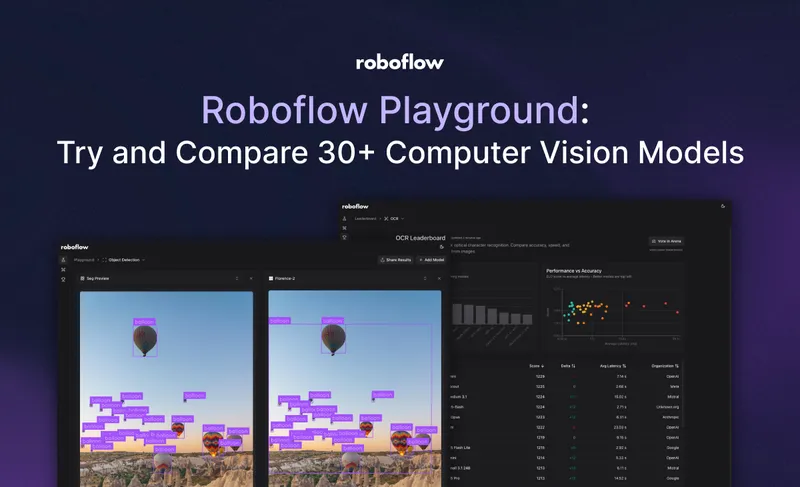
Roboflow launched Roboflow Playground on September 30, 2025, a browser-based tool for testing and comparing more than 30 computer-vision models. Users can submit the same image and prompt to as many as five compatible zero-shot models simultaneously, including models from Anthropic, OpenAI, Meta, Google, Mistral, and open-weight providers such as Florence-2, Qwen3.8 27B, Muse Glimmer 30B, and Llama-series releases. Playground supports object detection, image classification, optical character recognition, captioning, and open-prompt visual question answering. Available models vary by task: Gemini 3.6 Flash and SAM 3 can be selected for object detection, while SAM 3 cannot be used for visual question answering. The service lets users upload images, enter prompts, and inspect output side by side without separately provisioning cloud APIs or infrastructure for open-weight models. For object detection, Playground draws bounding boxes returned by each model. In a Roboflow example using prompts for a book and coffee, Florence-2 and YOLO World identified both objects with accurate boxes, while Claude 3.5 Sonnet located them generally but did not produce precise boxes. In an open-prompt example, Claude 4 Sonnet and GPT-4.1 identified a coffee cup on a table and described the surrounding scene. Roboflow says Playground is available free to try and that it plans to add models as they become available.
blog.roboflow.com
4 min
8/17/2026
Choosing an AI model: one prompt, 11 models, different results
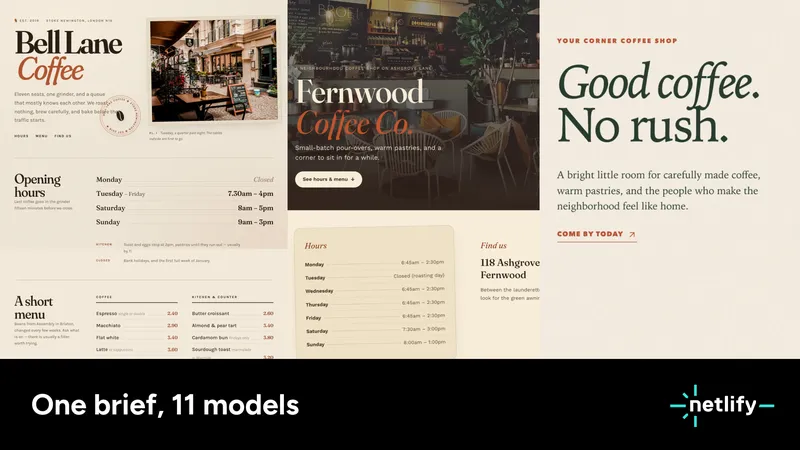
A partnership with OpenRouter allows access to a wider selection of AI models through an AI Gateway, enabling web apps to utilize various models for AI inference-based features. Additionally, the selection of frontier coding models is being expanded for use via Agent Runners within Netlify.
netlify.com
15 min
8/13/2026
MiniMax H3 Day-0 Support in ComfyUI: Open Weights, Native Audio, and 2K Video
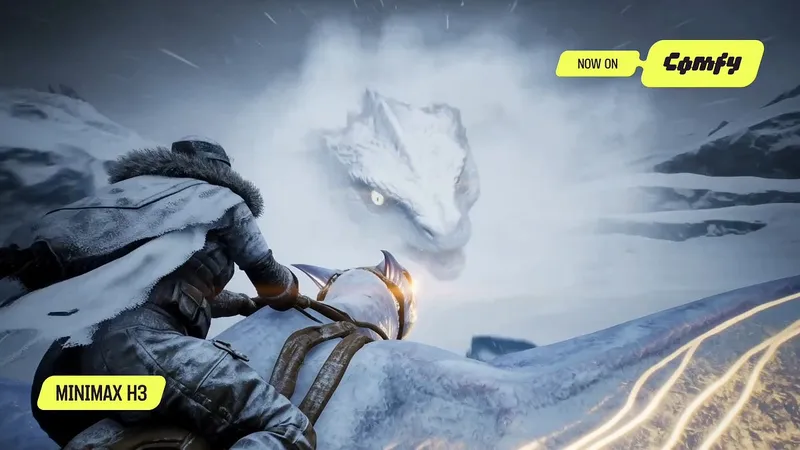
MiniMax H3 is an open-weights omni-modal video model that supports real stereo sound and 2K output. It is optimized for ComfyUI and can run locally on a 3060 GPU, allowing users to generate video from text, images, video, or audio inputs.
blog.comfy.org
8 min
8/3/2026

Inflect-Micro-v2: complete voice in 9.36M parameters
Inflect-Micro-v2 is a text-to-speech synthesis model with under 10 million parameters, offering fixed-voice English TTS, deterministic seeds, long-text handling, and support for CPU or CUDA inference. The developer aims to expand the project to include additional languages, voices, and stability improvements if it gains traction.
huggingface.co
11 min
7/26/2026
"Drawing" the Mona Lisa with GPT-5.6, Claude, Gemini, and Grok
Four AI models, GPT-5.6, Claude, Gemini, and Grok, were tasked with drawing the Mona Lisa on a blank canvas using colored pencils. Each model executed strokes, blended colors, erased, and evaluated its work to refine the drawing.
tryai.dev
10 min
7/21/2026
FLUX 3 Image Klein
Black Forest Labs has released FLUX 3 Image Klein, a 5.6-billion-parameter open-weights model for text-to-image generation, image editing, and multi-reference generation using up to 10 reference images. The model supports native 4K output, bounding-box controls for element placement or constrained edits, and pixel-perfect editing. Base and step-distilled versions are available under the FLUX Kommunity License, alongside FP8, INT8, and NVFP4 builds developed with NVIDIA support. Black Forest Labs says its internal evaluations rank Klein first among compared open-weight models for text-to-image generation, multi-reference generation, and image editing, ahead of larger models including Qwen-Image 2.1 and Krea 2. The company also says Klein scored above Ideogram V4.5 and FLUX.2 [pro] in its comparisons. INT8 weights let the model run through ComfyUI or Diffusers on NVIDIA GeForce RTX GPUs with 8GB of VRAM; the company reports roughly four seconds per 1-megapixel image on an RTX 5090 and under nine seconds on an RTX 4070. The distilled API model, flux-3-image-klein, starts at $0.009 per 1K image. Free commercial use applies to individuals and companies with under $5 million in annual revenue, while larger organizations require self-hosted licensing or API access.
bfl.ai
5 min
6h ago
GPT 5.6 Sol 20% price reduction
OpenAI’s GPT-5.6 Sol is a frontier model for complex professional work and the top tier of the GPT-5.6 family. The gpt-5.6 alias routes requests to GPT-5.6 Sol, which roughly corresponds to the unsuffixed model tier in earlier GPT-5 families. It accepts text and image inputs and produces text output, with a 1,050,000-token context window, a maximum output of 128,000 tokens, and a February 16, 2026 knowledge cutoff. The model supports reasoning-effort settings of none, low, medium, high, xhigh, and max; medium is the default. It supports streaming, function calling, structured outputs, and a range of Responses API tools, including web search, file search, image generation, code interpreter, hosted shell, computer use, MCP, and tool search. Fine-tuning is not supported. GPT-5.6 Sol costs $4 per million input tokens, $0.40 per million cached-input tokens, and $20 per million output tokens. OpenAI says these rates represent 20% lower input pricing and 33% lower output pricing, with promotional pricing available at least through November 21, 2026. Requests containing more than 272,000 input tokens are billed at twice the input rate and 1.5 times the output rate for the entire request.
developers.openai.com
2 min
8/22/2026
Roboflow Playground: Try and Compare 30 Computer Vision Models
Roboflow launched Roboflow Playground on September 30, 2025, a browser-based tool for testing and comparing more than 30 computer-vision models. Users can submit the same image and prompt to as many as five compatible zero-shot models simultaneously, including models from Anthropic, OpenAI, Meta, Google, Mistral, and open-weight providers such as Florence-2, Qwen3.8 27B, Muse Glimmer 30B, and Llama-series releases. Playground supports object detection, image classification, optical character recognition, captioning, and open-prompt visual question answering. Available models vary by task: Gemini 3.6 Flash and SAM 3 can be selected for object detection, while SAM 3 cannot be used for visual question answering. The service lets users upload images, enter prompts, and inspect output side by side without separately provisioning cloud APIs or infrastructure for open-weight models. For object detection, Playground draws bounding boxes returned by each model. In a Roboflow example using prompts for a book and coffee, Florence-2 and YOLO World identified both objects with accurate boxes, while Claude 3.5 Sonnet located them generally but did not produce precise boxes. In an open-prompt example, Claude 4 Sonnet and GPT-4.1 identified a coffee cup on a table and described the surrounding scene. Roboflow says Playground is available free to try and that it plans to add models as they become available.
blog.roboflow.com
4 min
8/17/2026
Choosing an AI model: one prompt, 11 models, different results
A partnership with OpenRouter allows access to a wider selection of AI models through an AI Gateway, enabling web apps to utilize various models for AI inference-based features. Additionally, the selection of frontier coding models is being expanded for use via Agent Runners within Netlify.
netlify.com
15 min
8/13/2026
Inflect-Micro-v2: complete voice in 9.36M parameters
Inflect-Micro-v2 is a text-to-speech synthesis model with under 10 million parameters, offering fixed-voice English TTS, deterministic seeds, long-text handling, and support for CPU or CUDA inference. The developer aims to expand the project to include additional languages, voices, and stability improvements if it gains traction.
huggingface.co
11 min
7/26/2026
GLM-5.3-Flash
Z.ai published a post titled “GLM-5.3-Flash.” The available source text provides no details about the model’s capabilities, release date, technical specifications, pricing, benchmarks, availability, or intended use. The post was submitted by Philpax and had received 529 points and 239 comments at the time represented by the source text.
z.ai
1 min
8/26/2026
Unsloth Dynamic 3.0 GGUFs
Unsloth released Dynamic v3.0 GGUF quantizations for Qwen3.8-27B, a post-training quantization format designed to reduce model storage requirements while preserving behavior close to the bfloat16 model. The new GGUF files work with inference engines including llama.cpp and Unsloth Desktop. Unsloth claims its v3.0 quants provide more than 10% higher top-1% accuracy at equivalent size than other providers’ versions, with improved results on KL Divergence and its Divergence-300 @32 evaluation. Dynamic v3.0 uses a higher-quality imatrix calibration dataset refined for agentic coding, chat, and multilingual use, along with revised layer selection and additional quantization techniques. Unsloth says it does not train on the calibration data or use quantization-aware training or quantization-aware distillation; it publishes its imatrix file for community testing and reuse. Its 300-prompt Divergence-300 benchmark uses held-out samples from Terminal-Bench 2.1, DeepSWE, Harbor, MathArena 2025-26, and non-Latin and long-document prompts, comparing 32-token greedy decoding trajectories against BF16. For smaller variants, Unsloth removed the MTP module from UD-Q2_K_XL quants of 8.37GB or less, saving roughly 500MB; a separate Q4_0 MTP module remains available. The 6.2GB UD-IQ1_S quant, without MTP, retains about 72% top-1% accuracy while being 89% smaller, according to Unsloth.
unsloth.ai
11 min
8/19/2026
Gemini 3.7 Flash
Gemini 3.7 Flash is a new model in the Gemini API, designed to enhance AI capabilities for developers. The model emphasizes ease of use and improved problem-solving features.
ai.google.dev
1 min
8/13/2026
MiniMax H3 Day-0 Support in ComfyUI: Open Weights, Native Audio, and 2K Video
MiniMax H3 is an open-weights omni-modal video model that supports real stereo sound and 2K output. It is optimized for ComfyUI and can run locally on a 3060 GPU, allowing users to generate video from text, images, video, or audio inputs.
blog.comfy.org
8 min
8/3/2026
"Drawing" the Mona Lisa with GPT-5.6, Claude, Gemini, and Grok
Four AI models, GPT-5.6, Claude, Gemini, and Grok, were tasked with drawing the Mona Lisa on a blank canvas using colored pencils. Each model executed strokes, blended colors, erased, and evaluated its work to refine the drawing.
tryai.dev
10 min
7/21/2026
FLUX 3 Image Klein
Black Forest Labs has released FLUX 3 Image Klein, a 5.6-billion-parameter open-weights model for text-to-image generation, image editing, and multi-reference generation using up to 10 reference images. The model supports native 4K output, bounding-box controls for element placement or constrained edits, and pixel-perfect editing. Base and step-distilled versions are available under the FLUX Kommunity License, alongside FP8, INT8, and NVFP4 builds developed with NVIDIA support. Black Forest Labs says its internal evaluations rank Klein first among compared open-weight models for text-to-image generation, multi-reference generation, and image editing, ahead of larger models including Qwen-Image 2.1 and Krea 2. The company also says Klein scored above Ideogram V4.5 and FLUX.2 [pro] in its comparisons. INT8 weights let the model run through ComfyUI or Diffusers on NVIDIA GeForce RTX GPUs with 8GB of VRAM; the company reports roughly four seconds per 1-megapixel image on an RTX 5090 and under nine seconds on an RTX 4070. The distilled API model, flux-3-image-klein, starts at $0.009 per 1K image. Free commercial use applies to individuals and companies with under $5 million in annual revenue, while larger organizations require self-hosted licensing or API access.
bfl.ai
5 min
6h ago
Unsloth Dynamic 3.0 GGUFs
Unsloth released Dynamic v3.0 GGUF quantizations for Qwen3.8-27B, a post-training quantization format designed to reduce model storage requirements while preserving behavior close to the bfloat16 model. The new GGUF files work with inference engines including llama.cpp and Unsloth Desktop. Unsloth claims its v3.0 quants provide more than 10% higher top-1% accuracy at equivalent size than other providers’ versions, with improved results on KL Divergence and its Divergence-300 @32 evaluation. Dynamic v3.0 uses a higher-quality imatrix calibration dataset refined for agentic coding, chat, and multilingual use, along with revised layer selection and additional quantization techniques. Unsloth says it does not train on the calibration data or use quantization-aware training or quantization-aware distillation; it publishes its imatrix file for community testing and reuse. Its 300-prompt Divergence-300 benchmark uses held-out samples from Terminal-Bench 2.1, DeepSWE, Harbor, MathArena 2025-26, and non-Latin and long-document prompts, comparing 32-token greedy decoding trajectories against BF16. For smaller variants, Unsloth removed the MTP module from UD-Q2_K_XL quants of 8.37GB or less, saving roughly 500MB; a separate Q4_0 MTP module remains available. The 6.2GB UD-IQ1_S quant, without MTP, retains about 72% top-1% accuracy while being 89% smaller, according to Unsloth.
unsloth.ai
11 min
8/19/2026
Choosing an AI model: one prompt, 11 models, different results
A partnership with OpenRouter allows access to a wider selection of AI models through an AI Gateway, enabling web apps to utilize various models for AI inference-based features. Additionally, the selection of frontier coding models is being expanded for use via Agent Runners within Netlify.
netlify.com
15 min
8/13/2026
"Drawing" the Mona Lisa with GPT-5.6, Claude, Gemini, and Grok
Four AI models, GPT-5.6, Claude, Gemini, and Grok, were tasked with drawing the Mona Lisa on a blank canvas using colored pencils. Each model executed strokes, blended colors, erased, and evaluated its work to refine the drawing.
tryai.dev
10 min
7/21/2026
GLM-5.3-Flash
Z.ai published a post titled “GLM-5.3-Flash.” The available source text provides no details about the model’s capabilities, release date, technical specifications, pricing, benchmarks, availability, or intended use. The post was submitted by Philpax and had received 529 points and 239 comments at the time represented by the source text.
z.ai
1 min
8/26/2026
Roboflow Playground: Try and Compare 30 Computer Vision Models
Roboflow launched Roboflow Playground on September 30, 2025, a browser-based tool for testing and comparing more than 30 computer-vision models. Users can submit the same image and prompt to as many as five compatible zero-shot models simultaneously, including models from Anthropic, OpenAI, Meta, Google, Mistral, and open-weight providers such as Florence-2, Qwen3.8 27B, Muse Glimmer 30B, and Llama-series releases. Playground supports object detection, image classification, optical character recognition, captioning, and open-prompt visual question answering. Available models vary by task: Gemini 3.6 Flash and SAM 3 can be selected for object detection, while SAM 3 cannot be used for visual question answering. The service lets users upload images, enter prompts, and inspect output side by side without separately provisioning cloud APIs or infrastructure for open-weight models. For object detection, Playground draws bounding boxes returned by each model. In a Roboflow example using prompts for a book and coffee, Florence-2 and YOLO World identified both objects with accurate boxes, while Claude 3.5 Sonnet located them generally but did not produce precise boxes. In an open-prompt example, Claude 4 Sonnet and GPT-4.1 identified a coffee cup on a table and described the surrounding scene. Roboflow says Playground is available free to try and that it plans to add models as they become available.
blog.roboflow.com
4 min
8/17/2026
MiniMax H3 Day-0 Support in ComfyUI: Open Weights, Native Audio, and 2K Video
MiniMax H3 is an open-weights omni-modal video model that supports real stereo sound and 2K output. It is optimized for ComfyUI and can run locally on a 3060 GPU, allowing users to generate video from text, images, video, or audio inputs.
blog.comfy.org
8 min
8/3/2026
GPT 5.6 Sol 20% price reduction
OpenAI’s GPT-5.6 Sol is a frontier model for complex professional work and the top tier of the GPT-5.6 family. The gpt-5.6 alias routes requests to GPT-5.6 Sol, which roughly corresponds to the unsuffixed model tier in earlier GPT-5 families. It accepts text and image inputs and produces text output, with a 1,050,000-token context window, a maximum output of 128,000 tokens, and a February 16, 2026 knowledge cutoff. The model supports reasoning-effort settings of none, low, medium, high, xhigh, and max; medium is the default. It supports streaming, function calling, structured outputs, and a range of Responses API tools, including web search, file search, image generation, code interpreter, hosted shell, computer use, MCP, and tool search. Fine-tuning is not supported. GPT-5.6 Sol costs $4 per million input tokens, $0.40 per million cached-input tokens, and $20 per million output tokens. OpenAI says these rates represent 20% lower input pricing and 33% lower output pricing, with promotional pricing available at least through November 21, 2026. Requests containing more than 272,000 input tokens are billed at twice the input rate and 1.5 times the output rate for the entire request.
developers.openai.com
2 min
8/22/2026
Gemini 3.7 Flash
Gemini 3.7 Flash is a new model in the Gemini API, designed to enhance AI capabilities for developers. The model emphasizes ease of use and improved problem-solving features.
ai.google.dev
1 min
8/13/2026
Inflect-Micro-v2: complete voice in 9.36M parameters
Inflect-Micro-v2 is a text-to-speech synthesis model with under 10 million parameters, offering fixed-voice English TTS, deterministic seeds, long-text handling, and support for CPU or CUDA inference. The developer aims to expand the project to include additional languages, voices, and stability improvements if it gains traction.
huggingface.co
11 min
7/26/2026