Introducing Toast 1
Toast 1 is a specialized search agent that matches or outperforms Claude Opus 5 and GPT-5.6 Sol while being up to 10× cheaper and 12× faster. It excels with Mixedbread Search but is compatible with any search backend and is capable of performing real knowledge work, including reasoning and analyzing complex document collections.
mixedbread.com
5 min
8/14/2026
Accelerating GPT-5.6 Sol Ultrafast
Cerebras and OpenAI have introduced Ultrafast Mode, a new service tier in the OpenAI API that accelerates GPT-5.6 Sol. This mode delivers up to 750 output tokens per second without compromising quality, targeting time-sensitive and mission-critical tasks.
cerebras.ai
4 min
8/13/2026
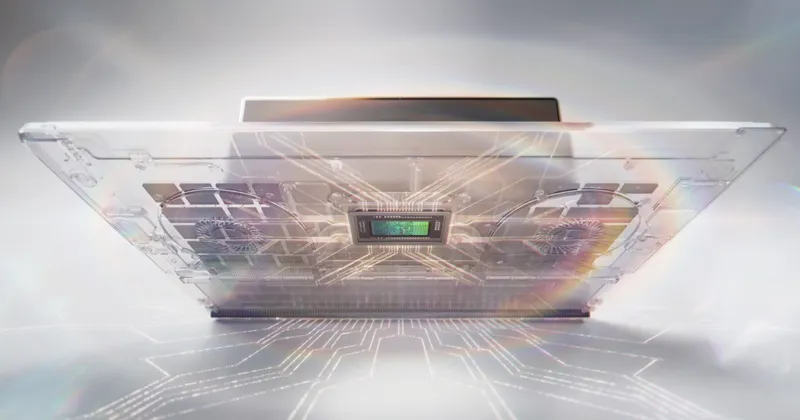
Nvidia RTX Spark
NVIDIA RTX Spark features the Blackwell RTX GPU and an ultra-efficient CPU, delivering up to FP4 AI performance and unified memory. The chip is designed for slim laptops and small desktops, enabling creative applications and gaming with advanced ray-tracing technology.
nvidia.com
1 min
6/1/2026
Lambda Calculus Benchmark for AI
LamBench is a benchmarking tool designed to evaluate the performance of language models across various dimensions such as intelligence, speed, and elegance. It provides a structured framework for identifying and addressing performance issues in AI models.
victortaelin.github.io
1 min
4/25/2026
Unsloth Dynamic 2.0 GGUFs
Unsloth Dynamic v2.0 quantization significantly enhances performance over previous methods, achieving new benchmarks for Aider Polglot, 5-shot MMLU, and KL Divergence. The 2.0 GGUFs allow for running and fine-tuning quantized LLMs with minimal accuracy loss on various inference engines, including llama.cpp and LM Studio.
unsloth.ai
8 min
2/28/2026
Introducing Toast 1
Toast 1 is a specialized search agent that matches or outperforms Claude Opus 5 and GPT-5.6 Sol while being up to 10× cheaper and 12× faster. It excels with Mixedbread Search but is compatible with any search backend and is capable of performing real knowledge work, including reasoning and analyzing complex document collections.
mixedbread.com
5 min
8/14/2026
Automatic1111 for Apple metal, 40% speed up sd1.5
Automatic1111 runs slower on Apple hardware compared to expectations, prompting a search for performance improvements. A five-step DPM++ SDE method on an M3 Pro reduces processing time from 8-10 seconds to 3-7 seconds.
therad.ninja
13 min
8/12/2026
Lambda Calculus Benchmark for AI
LamBench is a benchmarking tool designed to evaluate the performance of language models across various dimensions such as intelligence, speed, and elegance. It provides a structured framework for identifying and addressing performance issues in AI models.
victortaelin.github.io
1 min
4/25/2026
Unsloth Dynamic 2.0 GGUFs
Unsloth Dynamic v2.0 quantization significantly enhances performance over previous methods, achieving new benchmarks for Aider Polglot, 5-shot MMLU, and KL Divergence. The 2.0 GGUFs allow for running and fine-tuning quantized LLMs with minimal accuracy loss on various inference engines, including llama.cpp and LM Studio.
unsloth.ai
8 min
2/28/2026
Accelerating GPT-5.6 Sol Ultrafast
Cerebras and OpenAI have introduced Ultrafast Mode, a new service tier in the OpenAI API that accelerates GPT-5.6 Sol. This mode delivers up to 750 output tokens per second without compromising quality, targeting time-sensitive and mission-critical tasks.
cerebras.ai
4 min
8/13/2026
Nvidia RTX Spark
NVIDIA RTX Spark features the Blackwell RTX GPU and an ultra-efficient CPU, delivering up to FP4 AI performance and unified memory. The chip is designed for slim laptops and small desktops, enabling creative applications and gaming with advanced ray-tracing technology.
nvidia.com
1 min
6/1/2026
Introducing Toast 1
Toast 1 is a specialized search agent that matches or outperforms Claude Opus 5 and GPT-5.6 Sol while being up to 10× cheaper and 12× faster. It excels with Mixedbread Search but is compatible with any search backend and is capable of performing real knowledge work, including reasoning and analyzing complex document collections.
mixedbread.com
5 min
8/14/2026
Nvidia RTX Spark
NVIDIA RTX Spark features the Blackwell RTX GPU and an ultra-efficient CPU, delivering up to FP4 AI performance and unified memory. The chip is designed for slim laptops and small desktops, enabling creative applications and gaming with advanced ray-tracing technology.
nvidia.com
1 min
6/1/2026
Unsloth Dynamic 2.0 GGUFs
Unsloth Dynamic v2.0 quantization significantly enhances performance over previous methods, achieving new benchmarks for Aider Polglot, 5-shot MMLU, and KL Divergence. The 2.0 GGUFs allow for running and fine-tuning quantized LLMs with minimal accuracy loss on various inference engines, including llama.cpp and LM Studio.
unsloth.ai
8 min
2/28/2026
Accelerating GPT-5.6 Sol Ultrafast
Cerebras and OpenAI have introduced Ultrafast Mode, a new service tier in the OpenAI API that accelerates GPT-5.6 Sol. This mode delivers up to 750 output tokens per second without compromising quality, targeting time-sensitive and mission-critical tasks.
cerebras.ai
4 min
8/13/2026
Lambda Calculus Benchmark for AI
LamBench is a benchmarking tool designed to evaluate the performance of language models across various dimensions such as intelligence, speed, and elegance. It provides a structured framework for identifying and addressing performance issues in AI models.
victortaelin.github.io
1 min
4/25/2026
Automatic1111 for Apple metal, 40% speed up sd1.5
Automatic1111 runs slower on Apple hardware compared to expectations, prompting a search for performance improvements. A five-step DPM++ SDE method on an M3 Pro reduces processing time from 8-10 seconds to 3-7 seconds.
therad.ninja
13 min
8/12/2026
No more articles to load