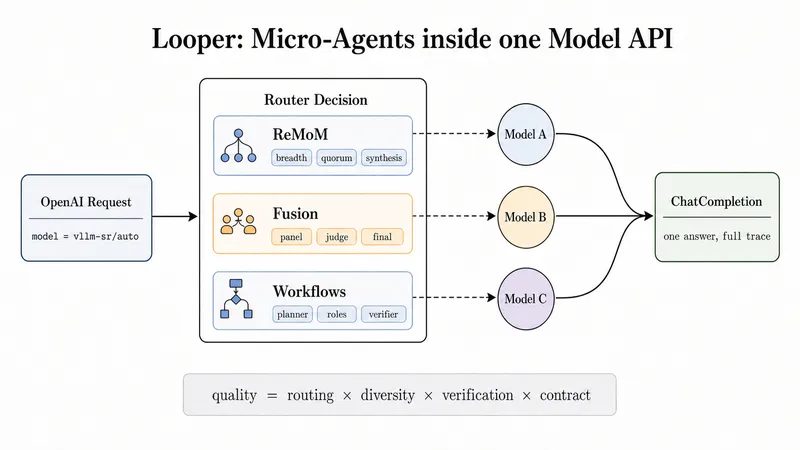
Micro-Agent: Beat Frontier Models with Collaboration Inside Model API
Micro-Agent enables collaboration within model APIs to enhance AI inference efficiency. Routers serve as the control plane, optimizing requests by directing them to appropriate models, thereby reducing costs associated with using frontier models versus open-source or local alternatives.
vllm.ai
9 min
6/29/2026
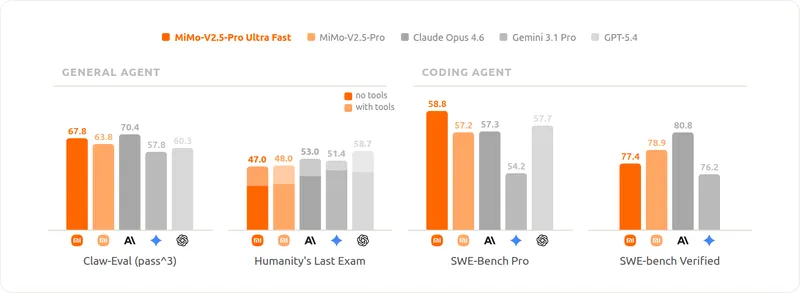
MiMo-v2.5-Pro-UltraSpeed: 1T model with 1000 tokens per second
Xiaomi has released the MiMo-V2.5-Pro-UltraSpeed, capable of generating 1 trillion parameter models at a speed of 1000 transactions per second (TPS). This advancement enhances real-time AI reasoning and collaboration, making it more responsive and integrated into human thought processes.
mimo.xiaomi.com
8 min
6/8/2026
Run a 1T parameter model on a 32gb Mac by streaming tensors from NVMe
Hypura is a storage-tier-aware LLM inference scheduler designed for Apple Silicon, allowing users to run large models that exceed their Mac's memory. It optimally distributes model tensors across GPU, RAM, and NVMe storage based on access patterns and hardware capabilities to prevent system crashes.
github.com
6 min
3/24/2026
Micro-Agent: Beat Frontier Models with Collaboration Inside Model API
Micro-Agent enables collaboration within model APIs to enhance AI inference efficiency. Routers serve as the control plane, optimizing requests by directing them to appropriate models, thereby reducing costs associated with using frontier models versus open-source or local alternatives.
vllm.ai
9 min
6/29/2026
MiMo-v2.5-Pro-UltraSpeed: 1T model with 1000 tokens per second
Xiaomi has released the MiMo-V2.5-Pro-UltraSpeed, capable of generating 1 trillion parameter models at a speed of 1000 transactions per second (TPS). This advancement enhances real-time AI reasoning and collaboration, making it more responsive and integrated into human thought processes.
mimo.xiaomi.com
8 min
6/8/2026
Run a 1T parameter model on a 32gb Mac by streaming tensors from NVMe
Hypura is a storage-tier-aware LLM inference scheduler designed for Apple Silicon, allowing users to run large models that exceed their Mac's memory. It optimally distributes model tensors across GPU, RAM, and NVMe storage based on access patterns and hardware capabilities to prevent system crashes.
github.com
6 min
3/24/2026
Micro-Agent: Beat Frontier Models with Collaboration Inside Model API
Micro-Agent enables collaboration within model APIs to enhance AI inference efficiency. Routers serve as the control plane, optimizing requests by directing them to appropriate models, thereby reducing costs associated with using frontier models versus open-source or local alternatives.
vllm.ai
9 min
6/29/2026
Run a 1T parameter model on a 32gb Mac by streaming tensors from NVMe
Hypura is a storage-tier-aware LLM inference scheduler designed for Apple Silicon, allowing users to run large models that exceed their Mac's memory. It optimally distributes model tensors across GPU, RAM, and NVMe storage based on access patterns and hardware capabilities to prevent system crashes.
github.com
6 min
3/24/2026
MiMo-v2.5-Pro-UltraSpeed: 1T model with 1000 tokens per second
Xiaomi has released the MiMo-V2.5-Pro-UltraSpeed, capable of generating 1 trillion parameter models at a speed of 1000 transactions per second (TPS). This advancement enhances real-time AI reasoning and collaboration, making it more responsive and integrated into human thought processes.
mimo.xiaomi.com
8 min
6/8/2026
No more articles to load