TorchTPU: Running PyTorch Natively on TPUs at Google Scale
TorchTPU enables running PyTorch natively on Google’s Tensor Processing Units (TPUs), enhancing performance and hardware portability for large-scale machine learning models. It addresses the challenges of distributed systems by supporting clusters of up to 100,000 chips.
developers.googleblog.com
7 min
4/23/2026
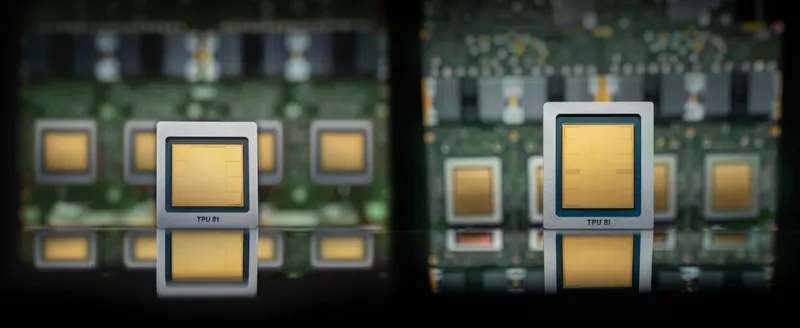
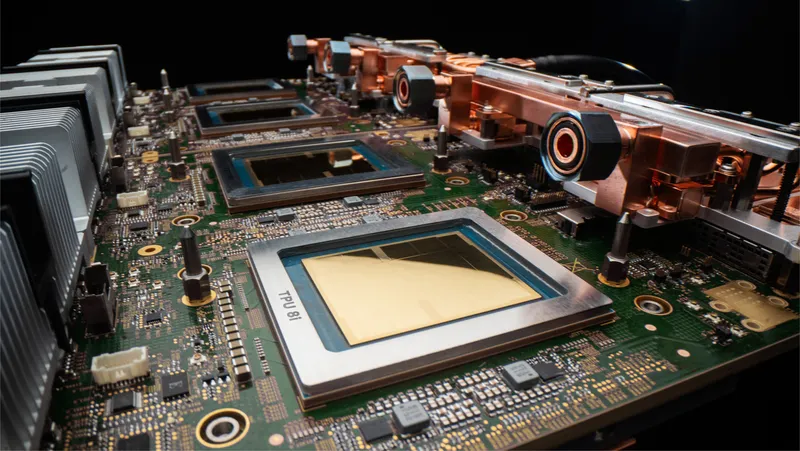
Our eighth generation TPUs: two chips for the agentic era
Google Cloud has introduced the eighth generation of Tensor Processing Units (TPUs), featuring two distinct architectures: TPU 8t for training and TPU 8i for inference. These chips are designed to enhance custom-built supercomputers, facilitating advanced model training, agent development, and large-scale inference workloads.
blog.google
7 min
4/22/2026
TorchTPU: Running PyTorch Natively on TPUs at Google Scale
TorchTPU enables running PyTorch natively on Google’s Tensor Processing Units (TPUs), enhancing performance and hardware portability for large-scale machine learning models. It addresses the challenges of distributed systems by supporting clusters of up to 100,000 chips.
developers.googleblog.com
7 min
4/23/2026
Our eighth generation TPUs: two chips for the agentic era
Google Cloud has introduced the eighth generation of Tensor Processing Units (TPUs), featuring two distinct architectures: TPU 8t for training and TPU 8i for inference. These chips are designed to enhance custom-built supercomputers, facilitating advanced model training, agent development, and large-scale inference workloads.
blog.google
7 min
4/22/2026
No more articles to load