Qwen 3.8 27B is excellent, but it defaults to overthinking things
Qwen 3.8 27B is a vision-capable language model with 27 billion parameters, released under the Apache 2 license by Alibaba's Qwen research lab. Self-reported benchmarks indicate significant performance improvements over its predecessor, Qwen 3.6 27B.
simonwillison.net
10 min
8/16/2026
Qwen3.8-27B
We promised open weights for Qwen3.8. Now, time to meet them! 🎉 ⚡ Qwen3.8-27B: - A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows. - 262K native context, easily extendable to 1M tokens via YaRN. - Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0. 🚀 The open weights for ...
twitter.com
1 min
8/14/2026
Qwen3.8 is launching and going open-weight soon
Qwen3.8 is launching and going open-weight soon!🌐 With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5. You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very f...
twitter.com
1 min
7/19/2026
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
Rio-3.5-Open-397B is a 397B model that combines weights from Nex-N2_pro and Qwen3.5-397B-A17B in a ratio of 0.6 to 0.4. There is no evidence of independent training for this model, indicating it is a direct merge of existing models.
github.com
1 min
6/14/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Qwen3.6-Plus: Towards real world agents
Qwen Chat provides extensive capabilities, including chatbot functionality, image and video comprehension, image generation, document processing, web search integration, and tool utilization. The platform also supports the handling of various artifacts.
qwen.ai
1 min
4/2/2026
Qwen 3.8 27B is excellent, but it defaults to overthinking things
Qwen 3.8 27B is a vision-capable language model with 27 billion parameters, released under the Apache 2 license by Alibaba's Qwen research lab. Self-reported benchmarks indicate significant performance improvements over its predecessor, Qwen 3.6 27B.
simonwillison.net
10 min
8/16/2026
Qwen/Qwen3.8-2.4T-A95B
Qwen/Qwen3.8-2.4T-A95B can be utilized with the Transformers library for text generation tasks. Users can implement a high-level pipeline for model interaction by importing the pipeline function and providing message inputs.
huggingface.co
12 min
8/12/2026
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Qwen3.6-Plus: Towards real world agents
Qwen Chat provides extensive capabilities, including chatbot functionality, image and video comprehension, image generation, document processing, web search integration, and tool utilization. The platform also supports the handling of various artifacts.
qwen.ai
1 min
4/2/2026
Qwen3.8-27B
We promised open weights for Qwen3.8. Now, time to meet them! 🎉 ⚡ Qwen3.8-27B: - A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows. - 262K native context, easily extendable to 1M tokens via YaRN. - Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0. 🚀 The open weights for ...
twitter.com
1 min
8/14/2026
Qwen3.8 is launching and going open-weight soon
Qwen3.8 is launching and going open-weight soon!🌐 With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5. You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very f...
twitter.com
1 min
7/19/2026
Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
Rio-3.5-Open-397B is a 397B model that combines weights from Nex-N2_pro and Qwen3.5-397B-A17B in a ratio of 0.6 to 0.4. There is no evidence of independent training for this model, indicating it is a direct merge of existing models.
github.com
1 min
6/14/2026
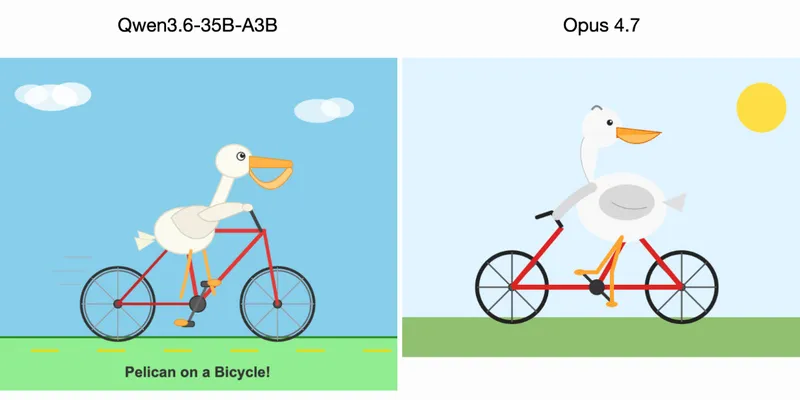
Qwen3.6-35B-A3B on my laptop drew me a better pelican than Claude Opus 4.7
Qwen3.6-35B-A3B generated a superior image of a pelican compared to Claude Opus 4.7. The Qwen model was run on a MacBook Pro M5 using LM Studio.
simonwillison.net
2 min
4/16/2026
Qwen 3.8 27B is excellent, but it defaults to overthinking things
Qwen 3.8 27B is a vision-capable language model with 27 billion parameters, released under the Apache 2 license by Alibaba's Qwen research lab. Self-reported benchmarks indicate significant performance improvements over its predecessor, Qwen 3.6 27B.
simonwillison.net
10 min
8/16/2026
Qwen3.8 is launching and going open-weight soon
Qwen3.8 is launching and going open-weight soon!🌐 With a massive 2.4T parameters, this model is continuously evolving. We believe it’s one of the most powerful model available today, compatible to leading frontier AI models , second only to Fable 5. You don't have to wait to test it. Just now, the Qwen3.8-Max-Preview made its debut on Alibaba’s Token Plan, Qoder, and QoderWork. Be among the very f...
twitter.com
1 min
7/19/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Qwen3.8-27B
We promised open weights for Qwen3.8. Now, time to meet them! 🎉 ⚡ Qwen3.8-27B: - A native multimodal dense model. With just 27B parameters, it outperforms Qwen3.7-Plus overall and shines in real-world coding & office workflows. - 262K native context, easily extendable to 1M tokens via YaRN. - Built for builders. Highly efficient, high-quality, and licensed under Apache 2.0. 🚀 The open weights for ...
twitter.com
1 min
8/14/2026
Qwen 3.6 27B is the sweet spot for local development
Qwen 3.6 27B is a dense local model recommended for its powerful performance in general intelligence tasks. It is slower than the mixture-of-experts variant Qwen 3.6 35B A3B but is considered more effective for local development.
quesma.com
6 min
6/29/2026
Qwen/Qwen3.8-2.4T-A95B
Qwen/Qwen3.8-2.4T-A95B can be utilized with the Transformers library for text generation tasks. Users can implement a high-level pipeline for model interaction by importing the pipeline function and providing message inputs.
huggingface.co
12 min
8/12/2026
Rio de Janeiro's "homegrown" LLM appears to be a merge of an existing model
Rio-3.5-Open-397B is a 397B model that combines weights from Nex-N2_pro and Qwen3.5-397B-A17B in a ratio of 0.6 to 0.4. There is no evidence of independent training for this model, indicating it is a direct merge of existing models.
github.com
1 min
6/14/2026
Qwen3.6-Plus: Towards real world agents
Qwen Chat provides extensive capabilities, including chatbot functionality, image and video comprehension, image generation, document processing, web search integration, and tool utilization. The platform also supports the handling of various artifacts.
qwen.ai
1 min
4/2/2026