LibreOffice 26.8 Released with Many Nice Improvements
The Document Foundation’s wiki is using Anubis, a proof-of-work challenge system, to protect its server from aggressive web scraping by AI companies. The site says large-scale scraping can cause downtime and make its resources inaccessible to other users. Anubis uses a proof-of-work scheme modeled on Hashcash, which was proposed to reduce email spam. The system is intended to impose negligible additional computing work on individual visitors while making high-volume scraping more expensive. The site describes Anubis as a temporary measure while work continues on identifying headless browsers, including through signals such as font rendering, so that likely legitimate users may avoid proof-of-work challenges. Anubis requires modern JavaScript features. The site says browser extensions such as JShelter can disable required features and instructs visitors to disable JShelter or similar plugins for the domain.
wiki.documentfoundation.org
1 min
8/26/2026

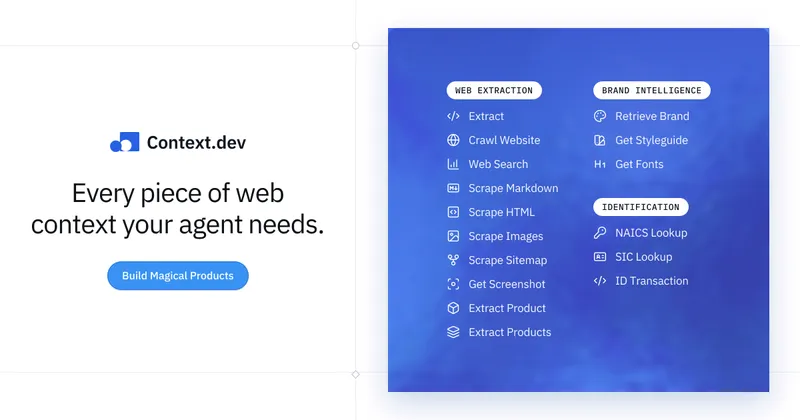
Launch HN: Context.dev (YC S26) – API to get structured data from any website
Context.dev provides a web scraping and crawl API that enables AI agents to extract structured data from any website using JSON schema. Mintlify utilized Context.dev to transform GitHub repository URLs into fully branded documentation sites in under 10 minutes.
context.dev
5 min
7/9/2026
Launch HN: Intuned (YC S22) – Build and run reliable browser automations as code
Intuned Agent generates production-ready Playwright code for web scraping, deploying it and adapting to site changes automatically. It allows users to extract data from various websites with built-in features for stealth, authentication, scheduling, and scalability.
intunedhq.com
10 min
6/8/2026
Miasma: A tool to trap AI web scrapers in an endless poison pit
Miasma is a tool designed to trap AI web scrapers by redirecting malicious traffic to a server that delivers poisoned training data and self-referential links. It aims to protect public websites from unauthorized data scraping by overwhelming scrapers with irrelevant information.
github.com
3 min
3/29/2026

Amazon wins court order to block Perplexity's AI shopping agent
A federal judge granted Amazon a temporary order blocking Perplexity's Comet AI browser from accessing its site. Amazon's lawsuit claims Perplexity concealed its AI agents to scrape the website without permission.
cnbc.com
2 min
3/10/2026
LibreOffice 26.8 Released with Many Nice Improvements
The Document Foundation’s wiki is using Anubis, a proof-of-work challenge system, to protect its server from aggressive web scraping by AI companies. The site says large-scale scraping can cause downtime and make its resources inaccessible to other users. Anubis uses a proof-of-work scheme modeled on Hashcash, which was proposed to reduce email spam. The system is intended to impose negligible additional computing work on individual visitors while making high-volume scraping more expensive. The site describes Anubis as a temporary measure while work continues on identifying headless browsers, including through signals such as font rendering, so that likely legitimate users may avoid proof-of-work challenges. Anubis requires modern JavaScript features. The site says browser extensions such as JShelter can disable required features and instructs visitors to disable JShelter or similar plugins for the domain.
wiki.documentfoundation.org
1 min
8/26/2026
Launch HN: Context.dev (YC S26) – API to get structured data from any website
Context.dev provides a web scraping and crawl API that enables AI agents to extract structured data from any website using JSON schema. Mintlify utilized Context.dev to transform GitHub repository URLs into fully branded documentation sites in under 10 minutes.
context.dev
5 min
7/9/2026
Miasma: A tool to trap AI web scrapers in an endless poison pit
Miasma is a tool designed to trap AI web scrapers by redirecting malicious traffic to a server that delivers poisoned training data and self-referential links. It aims to protect public websites from unauthorized data scraping by overwhelming scrapers with irrelevant information.
github.com
3 min
3/29/2026
99% of My Website Traffic Is Bots
99% of traffic on the PatronView website consists of bots. The site owner has implemented various firewall rules to combat scrapers and has shared insights from a year of battling automated traffic.
patronview.com
17 min
8/7/2026
Launch HN: Intuned (YC S22) – Build and run reliable browser automations as code
Intuned Agent generates production-ready Playwright code for web scraping, deploying it and adapting to site changes automatically. It allows users to extract data from various websites with built-in features for stealth, authentication, scheduling, and scalability.
intunedhq.com
10 min
6/8/2026
Amazon wins court order to block Perplexity's AI shopping agent
A federal judge granted Amazon a temporary order blocking Perplexity's Comet AI browser from accessing its site. Amazon's lawsuit claims Perplexity concealed its AI agents to scrape the website without permission.
cnbc.com
2 min
3/10/2026
LibreOffice 26.8 Released with Many Nice Improvements
The Document Foundation’s wiki is using Anubis, a proof-of-work challenge system, to protect its server from aggressive web scraping by AI companies. The site says large-scale scraping can cause downtime and make its resources inaccessible to other users. Anubis uses a proof-of-work scheme modeled on Hashcash, which was proposed to reduce email spam. The system is intended to impose negligible additional computing work on individual visitors while making high-volume scraping more expensive. The site describes Anubis as a temporary measure while work continues on identifying headless browsers, including through signals such as font rendering, so that likely legitimate users may avoid proof-of-work challenges. Anubis requires modern JavaScript features. The site says browser extensions such as JShelter can disable required features and instructs visitors to disable JShelter or similar plugins for the domain.
wiki.documentfoundation.org
1 min
8/26/2026
Launch HN: Intuned (YC S22) – Build and run reliable browser automations as code
Intuned Agent generates production-ready Playwright code for web scraping, deploying it and adapting to site changes automatically. It allows users to extract data from various websites with built-in features for stealth, authentication, scheduling, and scalability.
intunedhq.com
10 min
6/8/2026
99% of My Website Traffic Is Bots
99% of traffic on the PatronView website consists of bots. The site owner has implemented various firewall rules to combat scrapers and has shared insights from a year of battling automated traffic.
patronview.com
17 min
8/7/2026
Miasma: A tool to trap AI web scrapers in an endless poison pit
Miasma is a tool designed to trap AI web scrapers by redirecting malicious traffic to a server that delivers poisoned training data and self-referential links. It aims to protect public websites from unauthorized data scraping by overwhelming scrapers with irrelevant information.
github.com
3 min
3/29/2026
Launch HN: Context.dev (YC S26) – API to get structured data from any website
Context.dev provides a web scraping and crawl API that enables AI agents to extract structured data from any website using JSON schema. Mintlify utilized Context.dev to transform GitHub repository URLs into fully branded documentation sites in under 10 minutes.
context.dev
5 min
7/9/2026
Amazon wins court order to block Perplexity's AI shopping agent
A federal judge granted Amazon a temporary order blocking Perplexity's Comet AI browser from accessing its site. Amazon's lawsuit claims Perplexity concealed its AI agents to scrape the website without permission.
cnbc.com
2 min
3/10/2026
No more articles to load