AMD Strix Halo RDMA Cluster Setup Guide
github.com
June 28, 2026
10 min read
59/100
Summary
This guide provides instructions for configuring a two-node AMD Strix Halo cluster using Intel E810 (RoCE v2) for distributed vLLM inference with Tensor Parallelism. It covers hardware prerequisites, host configuration for Fedora 43, toolbox installation, network verification, cluster operation, and troubleshooting steps.
Key Takeaways
- The guide provides instructions for configuring a two-node AMD Strix Halo cluster using Intel E810 (RoCE v2) for distributed vLLM inference with Tensor Parallelism.
- Key components include vLLM for high-performance inference, Ray for cluster orchestration, and RCCL for fast synchronization of tensor data between GPUs.
- RDMA over Converged Ethernet (RoCE v2) reduces latency from approximately 70-100µs to about 5µs, significantly improving performance for interactive token generation.
- The recommended host configuration includes Fedora 43, specific kernel versions, and static IP assignments for both nodes.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- The combination of 128GB RAM and RDMA in smaller setups significantly enhances memory bandwidth for local AI applications, making advanced computing more accessible.
- Antirez's work on DS4 with 4-bit quantization shows promise for improving model performance, potentially making local AI more practical for users.
- The Strix Halo's memory bandwidth is a game changer for homelab setups, allowing enthusiasts to achieve near-provider level performance with prosumer hardware.
- The excitement around RDMA bridging the gap between consumer GPUs and higher memory capacities indicates a growing interest in accessible AI infrastructure.
Concerns
- The high costs of consumer hardware from tech companies remain a significant barrier, limiting access to advanced AI capabilities for many users.
- Concerns about the reliability of 100GbE connections in compact setups suggest potential overheating issues, which could hinder performance under load.
Related Articles
Jamesob's guide to running SOTA LLMs locally
Jul 3, 2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
Jun 13, 2026
Apple ML Research: Muse Spark Open with MLX on Mac Studio
Oct 16, 2026
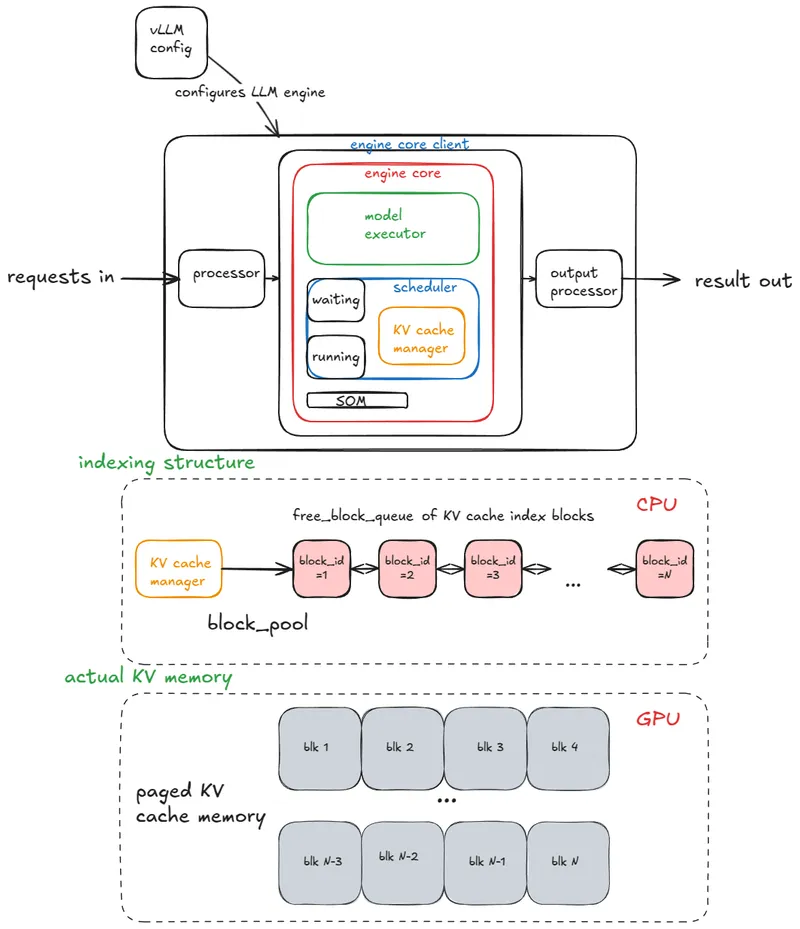
Inside vLLM: Anatomy of a High-Throughput LLM Inference System (2025)
Aug 6, 2026
Mesh LLM: distributed AI computing on iroh
Jul 11, 2026