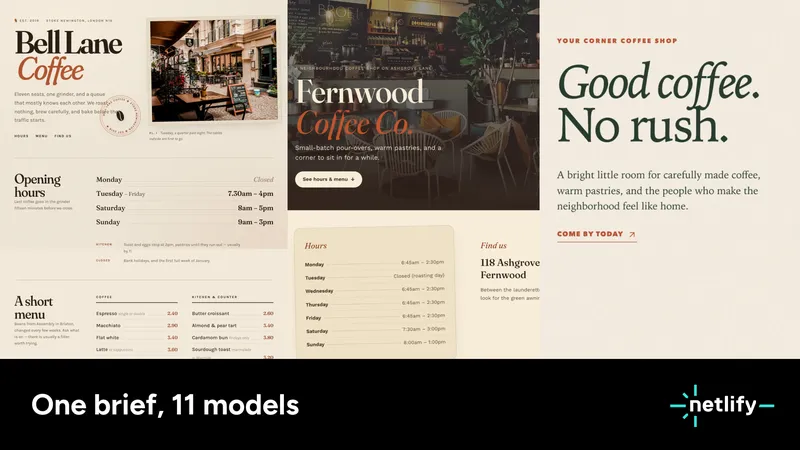
Choosing an AI model: one prompt, 11 models, different results
netlify.com
August 13, 2026
15 min read
59/100
Summary
A partnership with OpenRouter allows access to a wider selection of AI models through an AI Gateway, enabling web apps to utilize various models for AI inference-based features. Additionally, the selection of frontier coding models is being expanded for use via Agent Runners within Netlify.
Key Takeaways
- Netlify launched a partnership with OpenRouter, allowing users to access a wider selection of AI models through its AI Gateway.
- The Agent Runners feature now includes new open models such as Kimi K3, GLM 5.2, and DeepSeek V4, alongside previously supported models like Claude Agent and OpenAI Codex.
- Netlify uses an open-sourced tool called AXIS to evaluate AI models based on their performance in generating functional websites for various use cases.
- The evaluation process focuses on ensuring that generated sites meet specific functional requirements, such as proper database usage, rather than design aesthetics.
Coverage & discussions
Hacker News · netlify.com
Community discussions
Community Sentiment
Positives
- The model personalities are fascinating, especially how they evolve and develop distinct design sensibilities — it sparks curiosity about the training influences behind them.
- Some commenters are impressed with the GPT Sol and Luna models, noting their aesthetic appeal, which shows that design choices in AI-generated content do matter.
- There's a recognition that model output can be surprisingly similar across different architectures, highlighting a potential convergence in AI capabilities.
- The variance in token usage across models indicates a deeper level of complexity in model behavior that could lead to more tailored applications.
Concerns
- Many users feel that the evaluation methods used in the article are not representative of real-world development workflows, making the results less meaningful.
- There's skepticism about the usefulness of one-shot evaluations, as they don't reflect the nuanced, detailed prompts typically used in serious AI applications.
- Comments suggest that the similarity in model outputs can be quite disappointing, leading to concerns about a lack of creativity or differentiation among models.
- Some believe that generic benchmarks are outdated and that more tailored evaluations are needed to truly assess model capabilities in real scenarios.
Related Articles
We made Grok 4.5, GPT-5.5, and Claude build the same apps
Jul 8, 2026
Migrating a production AI agent to GPT-5.6: 2.2x faster, 27% cheaper
Jul 12, 2026
Local Qwen isn't a worse Opus, it's a different tool
Jun 18, 2026

The real prices of frontier models
Jul 13, 2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Jul 29, 2026