Decision trees – the unreasonable power of nested decision rules
mlu-explain.github.io
March 1, 2026
6 min read
🔥🔥🔥🔥🔥
68/100
Summary
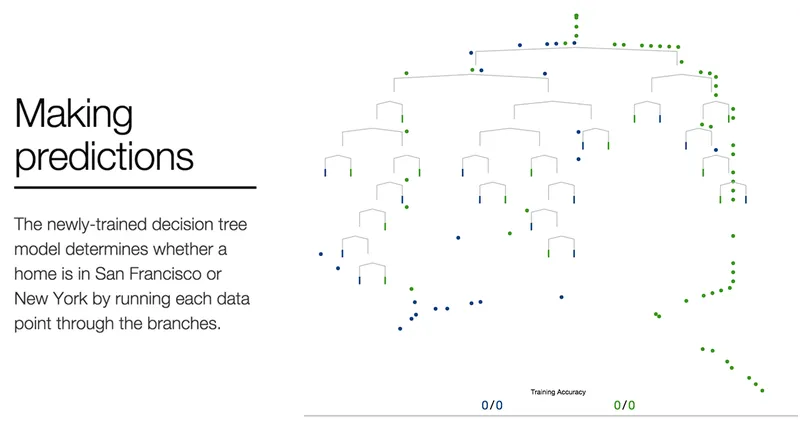
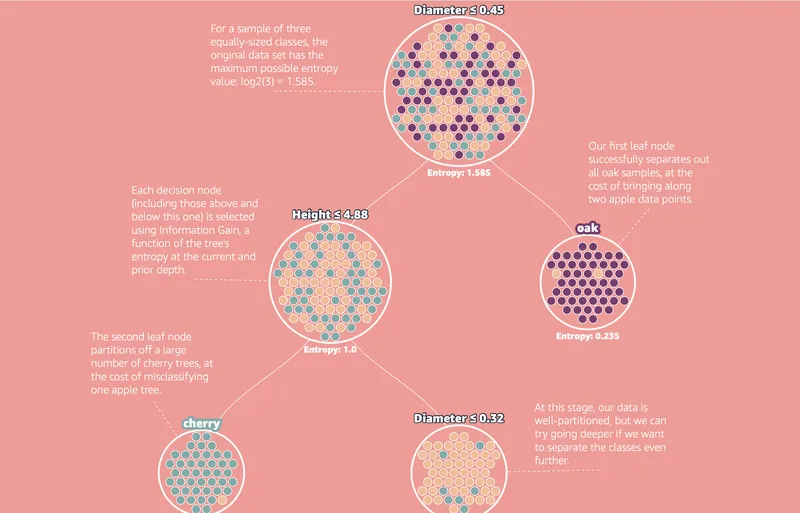
Decision Trees create sequential rules that split data into distinct regions for classification. Entropy is used to measure information and identify regions with significant data separation.
Key Takeaways
- Decision Trees classify data by creating a series of rules that partition the feature space into distinct regions based on conditional criteria.
- Entropy is used in Decision Trees to measure the purity of data samples, with pure samples having zero entropy and impure samples having higher entropy values.
- The ID3 algorithm utilizes entropy to determine the best rules for partitioning data, optimizing for information gain.
- Decision Trees are easy to interpret and fast to train but are unstable and sensitive to small changes in the training data.
Coverage & discussions
Hacker News · mlu-explain.github.io
Community discussions
Community Sentiment
Positives
- The ability to model complex decision-making with simple decision trees highlights their effectiveness, challenging the notion that more complex methods are always superior.
- Decision trees are celebrated as a powerful classical machine learning algorithm, showcasing their versatility and effectiveness in various applications.
Concerns
- There is a lack of understanding regarding when to effectively compile neural networks into decision trees, indicating a gap in knowledge that could limit their application.