GPT-5.2 and GPT-5.2-Codex are now 40% faster
twitter.com
February 4, 2026
1 min read
🔥🔥🔥🔥🔥
45/100
Summary
GPT-5.2 and GPT-5.2-Codex are now 40% faster due to optimizations in the inference stack for all API customers. The models maintain the same architecture and weights while offering lower latency.
Key Takeaways
- GPT-5.2 and GPT-5.2-Codex are now 40% faster than previous versions.
- OpenAI has optimized its inference stack for all API customers, resulting in lower latency.
- The model architecture and weights remain unchanged despite the performance improvements.
Coverage & discussions
Hacker News · twitter.com
Community discussions
Community Sentiment
Positives
- The 40% faster inference in GPT-5.2 significantly boosts productivity, with users reporting up to 3x improvement in their workflow.
- OpenAI's introduction of subagents and a better multi-agent interface enhances the usability of Codex, making it more effective for developers.
Concerns
- There are concerns that OpenAI may sacrifice model quality for speed, leading to skepticism about the reliability of their performance claims.
- The perception that initial model performance is artificially inflated raises doubts about the long-term effectiveness of the new features.
Related Articles
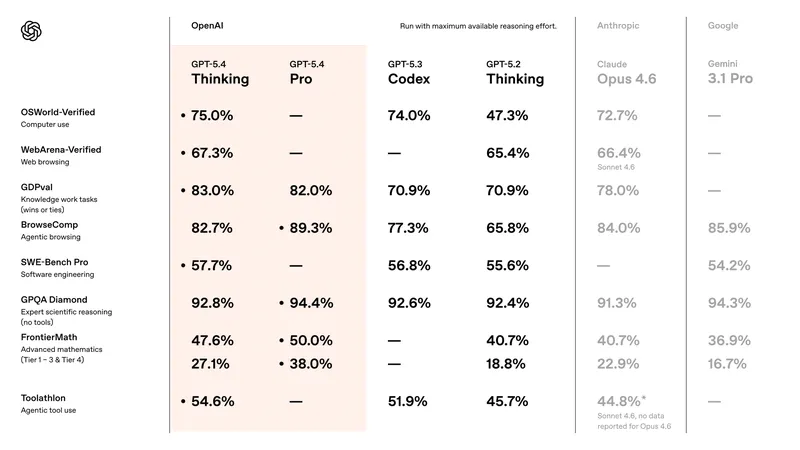
GPT-5.4 Thinking and GPT-5.4 Pro
Mar 5, 2026
OpenAI: GPT 5.6 Sol price reduction (until at least Nov 21)
Aug 24, 2026
Codex on AWS bedrock bug causing 10x charges
Aug 21, 2026
Launch HN: Tokenless (YC S26) – Automatic model switching to save money
Jul 29, 2026
Don't ask an LLM for a confidence score
Jul 28, 2026