Hamilton-Jacobi-Bellman Equation: Reinforcement Learning and Diffusion Models
dani2442.github.io
March 30, 2026
16 min read
56/100
Summary
Richard Bellman's 1952 paper established the foundation for optimal control and reinforcement learning. His later work in the 1950s connected continuous-time systems to a previously published physical result from the 1840s, formulating the optimal condition as a partial differential equation (PDE).
Key Takeaways
- Richard Bellman published a foundational paper on dynamic programming in 1952, which laid the groundwork for optimal control and reinforcement learning.
- The Hamilton-Jacobi-Bellman (HJB) equation, derived from Bellman's work, has the same mathematical structure as the Hamilton-Jacobi equation from classical mechanics.
- Continuous-time reinforcement learning and diffusion models can be interpreted through the lens of stochastic optimal control, utilizing the principles established by Bellman.
- The value function in reinforcement learning satisfies the Bellman equation, which maximizes immediate rewards plus continuation value.
Coverage & discussions
Hacker News · dani2442.github.io
Community discussions
Historical count: 3 · 3 saved in sample · Historical sample
Awaiting analysis
Related Articles
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Aug 19, 2026

Kimi Linear: An Expressive, Efficient Attention Architecture
Jul 28, 2026
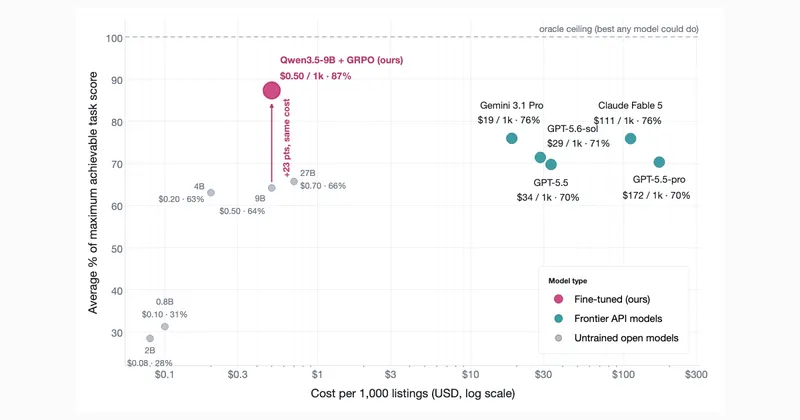
A $500 RL fine-tune of a 9B open model beat frontier models on catalog review
Jul 28, 2026
The Little Book of Reinforcement Learning
Jul 16, 2026
Ring-Zero: Scaling Zero RL to a Trillion Parameters for Emergent Reasoning
Jul 16, 2026