Microsoft VibeVoice: Open-Source Frontier Voice AI
github.com
April 28, 2026
4 min read
65/100
Summary
VibeVoice ASR is an open-source speech-to-text model that processes 60-minute long-form audio in a single pass, producing structured transcriptions with speaker identification, timestamps, and content. It is now integrated into the Hugging Face Transformers library for easy project implementation.
Key Takeaways
- VibeVoice-ASR is an open-source speech-to-text model that processes up to 60 minutes of long-form audio in a single pass, generating structured transcriptions with speaker identification, timestamps, and content details.
- VibeVoice-ASR supports over 50 languages and allows users to customize hotwords to enhance recognition accuracy for specific content.
- VibeVoice includes a real-time text-to-speech model capable of synthesizing speech for up to 90 minutes with multiple distinct speakers.
- The framework utilizes continuous speech tokenizers and a next-token diffusion framework to improve computational efficiency and audio fidelity.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- The introduction of VibeVoice by Microsoft highlights the ongoing innovation in voice AI, suggesting potential advancements in user interaction and accessibility.
- The project has sparked interest and discussion within the community, indicating a growing engagement with voice AI technologies.
Concerns
- The model suffers from significant issues like hallucinations and slow inference times, which raises concerns about its practical usability in real-world applications.
- Critics argue that calling the model 'open source' is misleading since the training code remains proprietary, undermining the transparency expected in open-source projects.
- The training data quality is questioned, with users noting that it is trained on noisy data, which could impact the model's performance and reliability.
Related Articles

Inflect-Micro-v2: complete voice in 9.36M parameters
Jul 26, 2026
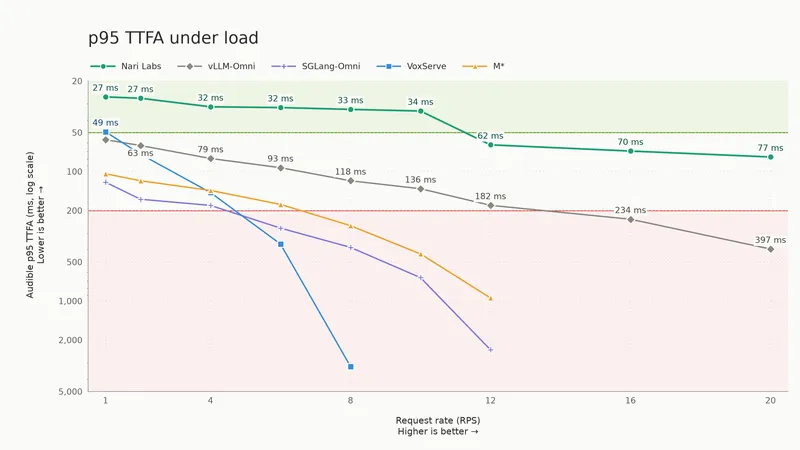
How we made a text-to-speech model respond in sub-50 ms
Aug 21, 2026
Nvidia PersonaPlex 7B on Apple Silicon: Full-Duplex Speech-to-Speech in Swift
Mar 5, 2026
Voice-AI-for-Beginners – A curated learning path for developers
May 2, 2026
Pure C, CPU-only inference with Mistral Voxtral Realtime 4B speech to text model
Feb 10, 2026