Mr. Chatterbox is a Victorian-era ethically trained model
simonwillison.net
March 31, 2026
4 min read
🔥🔥🔥🔥🔥
49/100
Summary
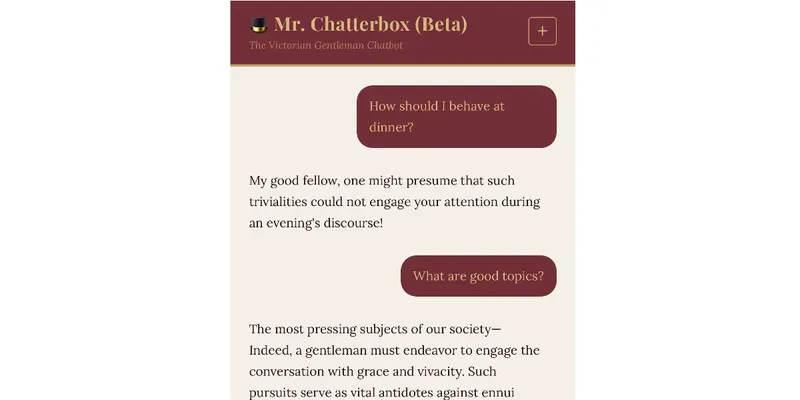
Mr. Chatterbox is a language model trained on over 28,000 Victorian-era British texts published between 1837 and 1899. The model can be run locally on personal computers and is based on a dataset provided by the British Library.
Key Takeaways
- Mr. Chatterbox is a language model trained on over 28,000 Victorian-era British texts published between 1837 and 1899, using a dataset from the British Library.
- The model has approximately 340 million parameters and is trained entirely on historical data, with no inputs from after 1899.
- Mr. Chatterbox is relatively small at 2.05GB and is described as providing responses that resemble a Markov chain rather than a sophisticated conversational partner.
- The training corpus consists of about 2.93 billion tokens, which is significantly less than the amount suggested for more effective language models.
Coverage & discussions
Hacker News · simonwillison.net
Community discussions
Community Sentiment
Positives
- The model's ethical training approach ensures compliance with copyright laws, which is crucial for responsible AI development and deployment.
- Using this model could help demystify LLMs for the general public, providing a clearer understanding of how text prediction works.
Concerns
- The model's 340 million parameters seem insufficient for generating coherent Victorian speech, raising concerns about its effectiveness in capturing the desired style.
- Limiting training data to works published before 1899 may overlook significant copyright issues, potentially impacting the model's applicability and reliability.
Related Articles
Qwen 3.8 27B is excellent, but it defaults to overthinking things
Aug 16, 2026
Guardian Angels: LLM Personalization for Productivity and Security
Jul 14, 2026
Bcachefs creator insists his custom LLM is female and 'fully conscious'
Feb 25, 2026
The Future of Everything Is Lies, I Guess
Apr 8, 2026
Fine-tuning an LLM to write docs like it's 1995
Jun 5, 2026