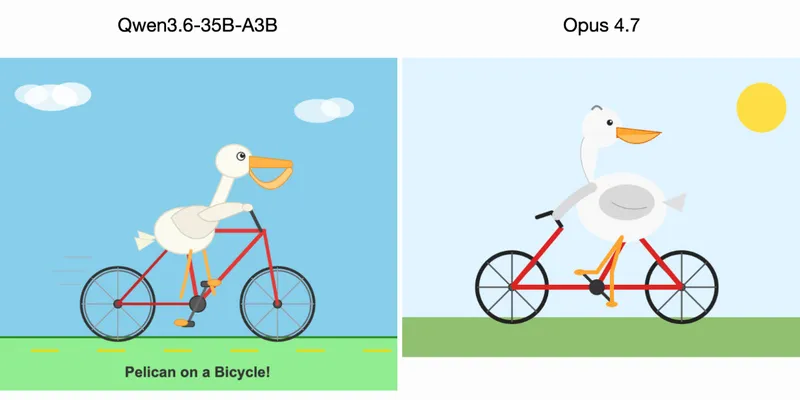
Qwen3.6-35B-A3B on my laptop drew me a better pelican than Claude Opus 4.7
simonwillison.net
April 16, 2026
2 min read
🔥🔥🔥🔥🔥
67/100
Summary
Qwen3.6-35B-A3B generated a superior image of a pelican compared to Claude Opus 4.7. The Qwen model was run on a MacBook Pro M5 using LM Studio.
Key Takeaways
- Qwen3.6-35B-A3B produced a better illustration of a pelican riding a bicycle than Claude Opus 4.7.
- The pelican benchmark, originally intended as a joke, has shown a correlation between the quality of generated images and the overall usefulness of AI models.
- Qwen3.6-35B-A3B is currently more effective for generating specific SVG illustrations compared to Claude Opus 4.7.
- The performance of Qwen3.6-35B-A3B does not necessarily indicate it is more powerful or useful than Anthropic's Claude Opus 4.7.
Coverage & discussions
Hacker News · simonwillison.net
Community discussions
Community Sentiment
Positives
- Qwen 3.6-35B-A3B demonstrated notable creativity in generating unique and imaginative outputs, suggesting potential for artistic applications in AI.
- The slight improvement in coding tasks performance indicates ongoing advancements in model capabilities, even if marginal.
Concerns
- Despite its creative outputs, Qwen 3.6-35B-A3B struggles with physical plausibility, raising concerns about its practical applications in real-world scenarios.
- The performance gap between Qwen and more established models like Opus 4.6 highlights significant limitations in Qwen's capabilities, particularly in benchmark tasks.
Related Articles
Kimi K3, and what we can still learn from the pelican benchmark
Jul 17, 2026

Are AI Labs Pelicanmaxxing?
Jul 22, 2026
Qwen 3.8 27B is excellent, but it defaults to overthinking things
Aug 16, 2026
Tmux and Claude Code: Sessions, Send-Keys, and the Ceiling
Oct 19, 2026
Superlite: A Faster Alternatie to Superpowers
Oct 19, 2026