The Rise and Fall of Jev
blog.alexewerlof.com
October 23, 2026
16 min read
48/100
Summary
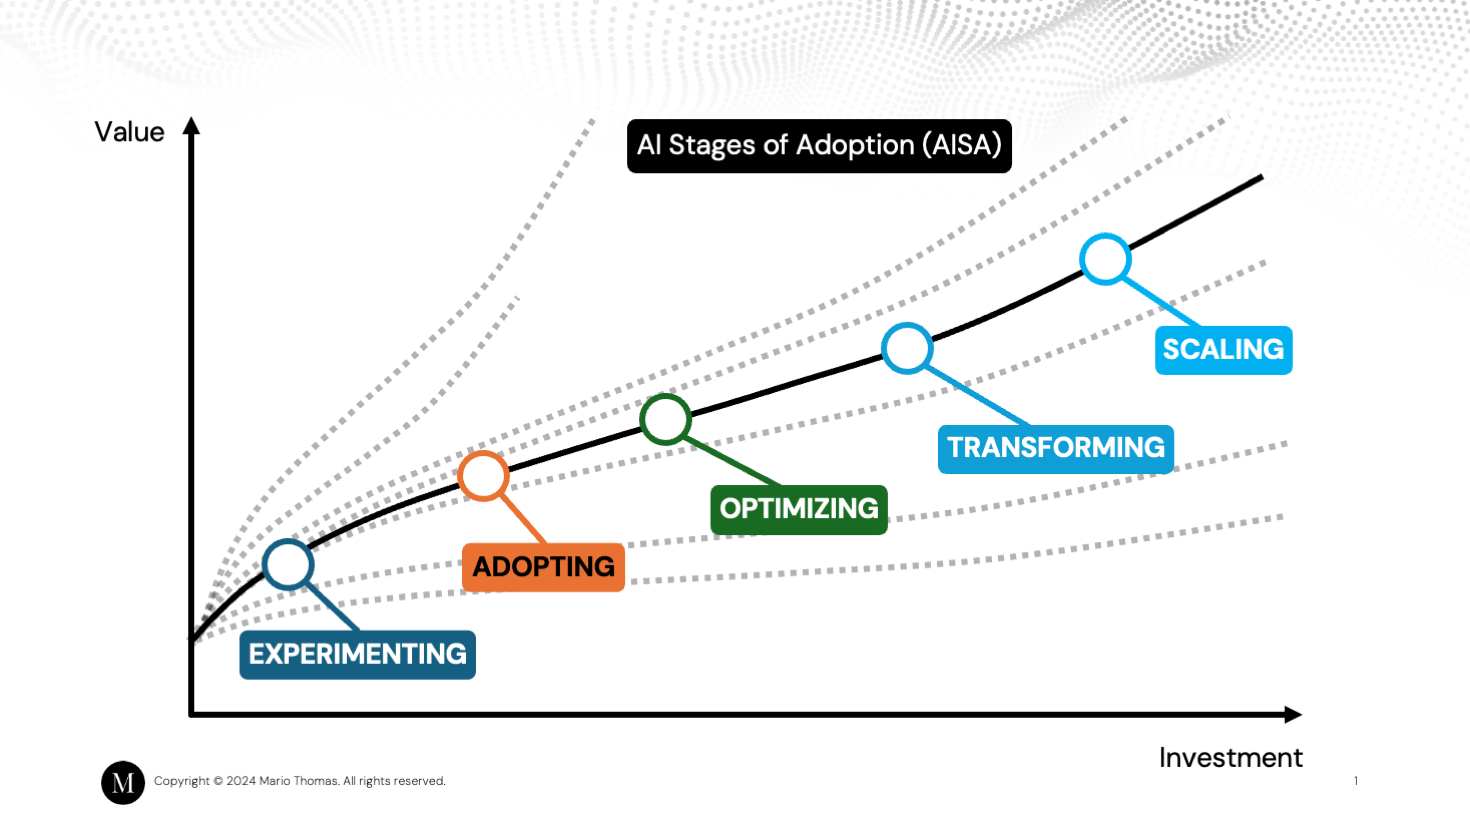
TypeSafe AI’s Jev is presented as a fast, low-cost general-purpose classifier that can produce outputs matching a specified schema without extensive task-specific training. Its launch 33 days earlier drew attention through claims of a “System One Model,” Reinforcement Learning for Calibrated Decisions (RLCD), and outputs that “cannot hallucinate.” The author argues that this claim means schema-conforming output rather than logically correct output, and says Jev can still be wrong. The author also says Jev’s hype declined rapidly as users assessed its limits, while open-weight alternatives may offer better performance-to-cost ratios for some tasks. Jev can reportedly run locally at the edge with quality comparable to frontier LLMs in some uses. The author characterizes recent AI progress as a series of incremental advances: instruction tuning, function calling, coding tools, agents, larger context windows, multimodal models, tool protocols, orchestration, web access, memory systems, and verification loops. The author argues that major unresolved problems include abstract reasoning, continuous real-time learning, capable embodied robotics, and the energy and infrastructure costs of operating AI at scale. Current AI systems paired with tools and automation can still cause harm without reaching artificial general intelligence, the author says, citing potential uses in surveillance, cyber intrusion, warfare, and disease generation. The author urges skepticism toward marketing based on name-dropping, jargon, ambiguous technical disclosures, isolated benchmarks, and emotionally charged publicity.
Key Takeaways
- TypeSafe AI’s Jev is marketed as a fast, inexpensive model for calibrated, schema-conforming decisions rather than a conventional LLM.
- The author says Jev’s claim that it cannot hallucinate refers to structured outputs matching a schema, not a guarantee that its answers are correct.
- The author says open-weight models can outperform Jev on performance-to-cost ratio for some tasks, while Jev can run locally at the edge with comparable quality in some cases.
- The author identifies abstract reasoning, continuous learning, embodied robotics, and AI operating economics as major unsolved challenges.
- Tool-enabled AI systems can create significant security and societal risks without achieving AGI, according to the author.
What the discussion said
Commenters mostly rejected the article’s framing that Jev has already risen and fallen. Their core objection was simple: social-media attention is a dreadful proxy for infrastructure software’s health. Several people reported it running in live products, where it continues to classify or extract data quickly and cheaply enough that its absence would create an operational problem immediately. Others pointed to revenue claims and model-ranking visibility as stronger evidence than whether it remains a recurring topic of conversation. The practical discussion centered on Jev as a specialized classifier rather than a general AI assistant. Users argued that it beats LLM-based alternatives on latency and, in some cases, on real-world output quality, especially for multilingual data. They see its value in replacing expensive, slow general models for narrow decisions that classifiers are built to make. That success, they argue, helped trigger a wave of competing decision and extraction models. There was still skepticism about the launch narrative. Some agreed that marketing inflated Jev into a broader AI event than the technology justified, while others said open-weight alternatives cover many tasks. A few stressed that no universal winner exists: benchmark claims and leaderboard positions cannot settle performance for a particular dataset, deployment environment, or edge use case. The prevailing mood was that Jev may be unglamorous now, but production utility matters far more than hype-cycle visibility.
Where opinion split
The sharpest dispute is whether Jev’s disappearance from AI chatter signals a genuine decline. Skeptics say the initial buzz outran a technically modest classifier product, with open-weight rivals handling much of the same work. Defenders argue that deployed reliability, speed, cost, and strong task-specific quality are the only meaningful test, and those measures show a durable product rather than a dead fad.
Coverage & discussions
Hacker News · blog.alexewerlof.com
Community discussions
Community Sentiment
Positives
- Jev is reportedly carrying real production workloads, which makes its quiet presence more meaningful than the absence of fresh social-media excitement.
- For classification and extraction, users describe Jev as fast, inexpensive, and reliable enough to outperform slower LLM-based pipelines where response time is a product constraint.
- Several testers say competing decision models lose on the combined quality, latency, and cost tradeoff, suggesting specialized training is harder to copy than a launch-week clone implies.
- Jev helped refocus attention on classifiers as a better fit than general LLMs for many narrow product decisions, spurring a competitive wave of extraction tools.
Concerns
- The launch appears to have been marketed as a much larger AI moment than a specialized classifier warranted, leaving the product exposed to a predictable backlash once novelty faded.
- Open-weight rivals may already satisfy the majority of common classifier use cases, weakening any claim that Jev is an indispensable default.
- Claims that Jev is universally best are challenged because benchmark results and leaderboards do not capture the dataset, language mix, latency budget, and deployment constraints of a real application.
- Some commenters view the underlying idea as commercially well-timed rather than technically exceptional: a useful packaging of classifier workflows that others could eventually reproduce.