Ultrafast machine learning on FPGAs via Kolmogorov-Arnold Networks
aarushgupta.io
June 9, 2026
13 min read
🔥🔥🔥🔥🔥
61/100
Summary
Ultrafast inference and online learning can be achieved using hardware architectures designed for Kolmogorov-Arnold Networks (KAN) on FPGAs. The research focuses on optimizing these architectures to enhance machine learning performance.
Key Takeaways
- The Kolmogorov-Arnold Network (KAN) architecture is designed for ultrafast inference and online learning on FPGAs.
- FPGAs are more suitable than GPUs for applications requiring ultra-low latency and high hardware efficiency in machine learning tasks.
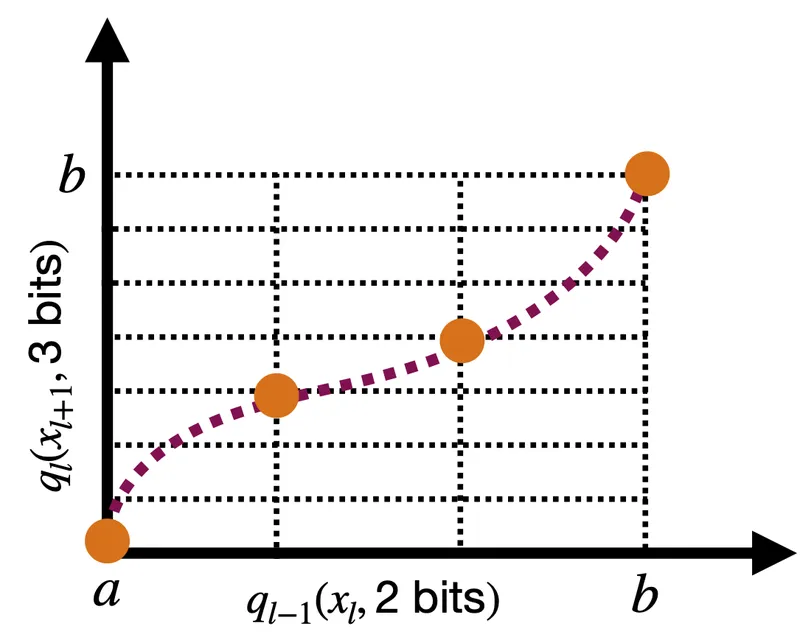
- Fixed-point quantization is used in FPGAs to represent real numbers as bitstrings, enabling efficient arithmetic operations in neural networks.
- The custom hardware accelerators provided by FPGAs allow for the implementation of neural networks directly as digital logic, improving performance for specialized workloads.
Coverage & discussions
Hacker News · aarushgupta.io
Community discussions
Community Sentiment
Positives
- The focus on ultrafast learning for small models opens up possibilities for real-time applications in fields like high-energy physics and quantum computing, which require low latency.
- The ongoing development of Kolmogorov-Arnold Networks (KANs) suggests a promising future for specialized machine learning architectures, particularly in niche applications.
Concerns
- The limitation to small models and the focus on latency rather than throughput raises concerns about the applicability of this approach for larger, more complex AI tasks like LLM inference.
- The inability to accelerate LLM inference indicates that this technology may not meet the demands of current AI applications that require high throughput.
Related Articles
Qwen 3.8-Flash-Next releasing tomorrow (125B a6B)
Aug 25, 2026
Seed: Minimal, self-modifying agent harness
Aug 21, 2026
Google buys crashed airline Spirit's data at auction, because AI
Aug 18, 2026
Nvidia's Risky Business
Aug 11, 2026
DeepMind's WeatherNext model achieves breakthrough forecasting cyclones
Aug 8, 2026