Kimi Linear: An Expressive, Efficient Attention Architecture
Kimi Linear is a hybrid linear attention architecture that outperforms full attention in short-context, long-context, and reinforcement learning scenarios. It utilizes Kimi Delta Attention to achieve this efficiency.
arxiv.org
2 min
7/28/2026
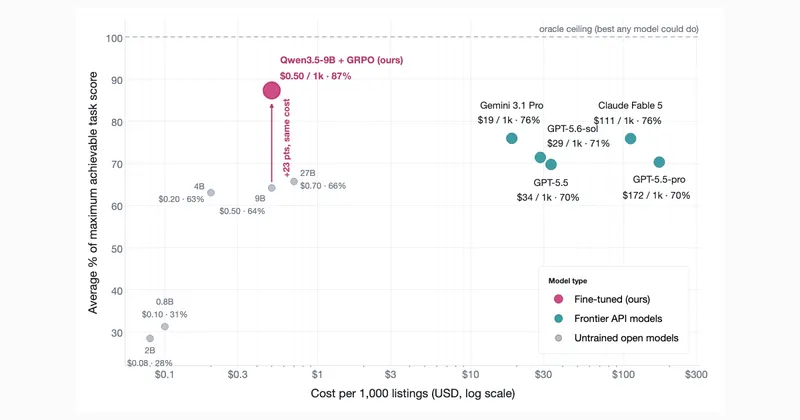
A $500 RL fine-tune of a 9B open model beat frontier models on catalog review
An open-source model combined with proprietary task data and reinforcement learning has been implemented in various real-world scenarios. Bridgewater Associates utilizes AI to analyze a continuous influx of documents to determine their relevance to investment strategies.
fermisense.com
2 min
7/28/2026
Ring-Zero: Scaling Zero RL to a Trillion Parameters for Emergent Reasoning
Ring-Zero scales zero reinforcement learning (RL) to a trillion parameters, enabling emergent reasoning capabilities. This advancement addresses computational constraints that have limited previous studies in zero RL, which utilizes verifiable rewards without human-annotated data.
arxiv.org
2 min
7/16/2026
Is One Layer Enough? A Single Transformer Layer Matches Full-Parameter RL Train
Training a single transformer layer can achieve performance comparable to full-parameter reinforcement learning (RL) training. This finding suggests that RL adaptation may not require uniform updates across all layers of large language models.
arxiv.org
2 min
7/2/2026
Hamilton-Jacobi-Bellman Equation: Reinforcement Learning and Diffusion Models
Richard Bellman's 1952 paper established the foundation for optimal control and reinforcement learning. His later work in the 1950s connected continuous-time systems to a previously published physical result from the 1840s, formulating the optimal condition as a partial differential equation (PDE).
dani2442.github.io
16 min
3/30/2026
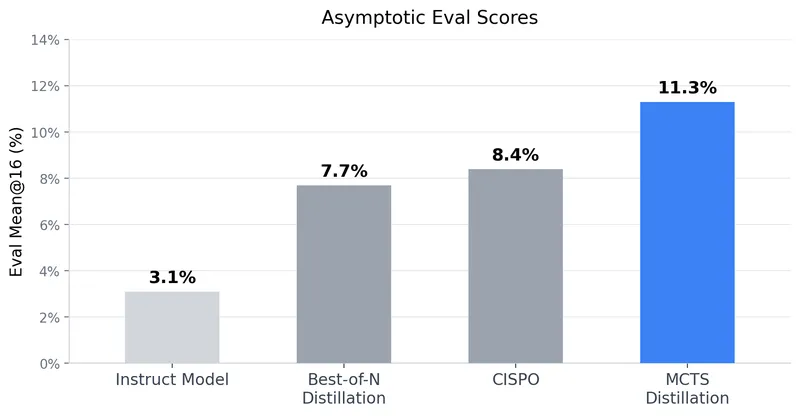
Tree Search Distillation for Language Models Using PPO
Tree Search Distillation utilizes Proximal Policy Optimization (PPO) to enhance language models by integrating a test-time search mechanism similar to that used in game-playing neural networks like AlphaZero. The method aims to distill a stronger, augmented policy back into the language model, addressing the limitations observed in previous attempts with Monte Carlo Tree Search (MCTS).
ayushtambde.com
10 min
3/15/2026
Chess engines do weird stuff
Chess engines like AlphaZero and lc0 use reinforcement learning by having the engine play itself multiple times to train the model on game outcomes. A combination of a weaker model and strong search capabilities can outperform a stronger model alone, as the search can significantly enhance performance.
girl.surgery
4 min
2/17/2026
Kimi Linear: An Expressive, Efficient Attention Architecture
Kimi Linear is a hybrid linear attention architecture that outperforms full attention in short-context, long-context, and reinforcement learning scenarios. It utilizes Kimi Delta Attention to achieve this efficiency.
arxiv.org
2 min
7/28/2026
Ring-Zero: Scaling Zero RL to a Trillion Parameters for Emergent Reasoning
Ring-Zero scales zero reinforcement learning (RL) to a trillion parameters, enabling emergent reasoning capabilities. This advancement addresses computational constraints that have limited previous studies in zero RL, which utilizes verifiable rewards without human-annotated data.
arxiv.org
2 min
7/16/2026
Maxproof
MaxProof is a framework designed for population-level test-time scaling in mathematical proof, specifically within the MiniMax-M3 series. It trains three key capabilities: proof generation, proof verification, and critique-conditioned proof repair.
arxiv.org
2 min
6/12/2026
Tree Search Distillation for Language Models Using PPO
Tree Search Distillation utilizes Proximal Policy Optimization (PPO) to enhance language models by integrating a test-time search mechanism similar to that used in game-playing neural networks like AlphaZero. The method aims to distill a stronger, augmented policy back into the language model, addressing the limitations observed in previous attempts with Monte Carlo Tree Search (MCTS).
ayushtambde.com
10 min
3/15/2026
A $500 RL fine-tune of a 9B open model beat frontier models on catalog review
An open-source model combined with proprietary task data and reinforcement learning has been implemented in various real-world scenarios. Bridgewater Associates utilizes AI to analyze a continuous influx of documents to determine their relevance to investment strategies.
fermisense.com
2 min
7/28/2026
Is One Layer Enough? A Single Transformer Layer Matches Full-Parameter RL Train
Training a single transformer layer can achieve performance comparable to full-parameter reinforcement learning (RL) training. This finding suggests that RL adaptation may not require uniform updates across all layers of large language models.
arxiv.org
2 min
7/2/2026
Hamilton-Jacobi-Bellman Equation: Reinforcement Learning and Diffusion Models
Richard Bellman's 1952 paper established the foundation for optimal control and reinforcement learning. His later work in the 1950s connected continuous-time systems to a previously published physical result from the 1840s, formulating the optimal condition as a partial differential equation (PDE).
dani2442.github.io
16 min
3/30/2026
Chess engines do weird stuff
Chess engines like AlphaZero and lc0 use reinforcement learning by having the engine play itself multiple times to train the model on game outcomes. A combination of a weaker model and strong search capabilities can outperform a stronger model alone, as the search can significantly enhance performance.
girl.surgery
4 min
2/17/2026
Kimi Linear: An Expressive, Efficient Attention Architecture
Kimi Linear is a hybrid linear attention architecture that outperforms full attention in short-context, long-context, and reinforcement learning scenarios. It utilizes Kimi Delta Attention to achieve this efficiency.
arxiv.org
2 min
7/28/2026
Is One Layer Enough? A Single Transformer Layer Matches Full-Parameter RL Train
Training a single transformer layer can achieve performance comparable to full-parameter reinforcement learning (RL) training. This finding suggests that RL adaptation may not require uniform updates across all layers of large language models.
arxiv.org
2 min
7/2/2026
Tree Search Distillation for Language Models Using PPO
Tree Search Distillation utilizes Proximal Policy Optimization (PPO) to enhance language models by integrating a test-time search mechanism similar to that used in game-playing neural networks like AlphaZero. The method aims to distill a stronger, augmented policy back into the language model, addressing the limitations observed in previous attempts with Monte Carlo Tree Search (MCTS).
ayushtambde.com
10 min
3/15/2026
A $500 RL fine-tune of a 9B open model beat frontier models on catalog review
An open-source model combined with proprietary task data and reinforcement learning has been implemented in various real-world scenarios. Bridgewater Associates utilizes AI to analyze a continuous influx of documents to determine their relevance to investment strategies.
fermisense.com
2 min
7/28/2026
Maxproof
MaxProof is a framework designed for population-level test-time scaling in mathematical proof, specifically within the MiniMax-M3 series. It trains three key capabilities: proof generation, proof verification, and critique-conditioned proof repair.
arxiv.org
2 min
6/12/2026
Chess engines do weird stuff
Chess engines like AlphaZero and lc0 use reinforcement learning by having the engine play itself multiple times to train the model on game outcomes. A combination of a weaker model and strong search capabilities can outperform a stronger model alone, as the search can significantly enhance performance.
girl.surgery
4 min
2/17/2026
Ring-Zero: Scaling Zero RL to a Trillion Parameters for Emergent Reasoning
Ring-Zero scales zero reinforcement learning (RL) to a trillion parameters, enabling emergent reasoning capabilities. This advancement addresses computational constraints that have limited previous studies in zero RL, which utilizes verifiable rewards without human-annotated data.
arxiv.org
2 min
7/16/2026
Hamilton-Jacobi-Bellman Equation: Reinforcement Learning and Diffusion Models
Richard Bellman's 1952 paper established the foundation for optimal control and reinforcement learning. His later work in the 1950s connected continuous-time systems to a previously published physical result from the 1840s, formulating the optimal condition as a partial differential equation (PDE).
dani2442.github.io
16 min
3/30/2026
No more articles to load