Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
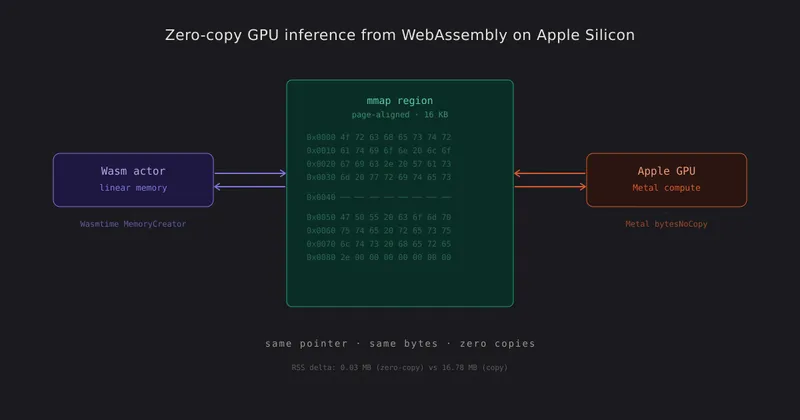
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Kimi K3 requires an 8ÃB300 node with 288GB of HBM per GPU due to its 1.4TB weight, exceeding the memory capacity of the 8ÃB200 node. This configuration results in approximately 20% higher hardware costs while supporting 16 concurrent sessions.
aistack.imec-int.com
25 min
7/29/2026
A CPU that runs entirely on GPU
nCPU is a CPU architecture that operates entirely on GPU, utilizing tensors for registers, memory, flags, and the program counter. All arithmetic operations, including addition, multiplication, bitwise operations, and shifts, are performed through trained neural networks, with specific methods like Kogge-Stone carry-lookahead for addition and learned byte-pair lookup tables for multiplication.
github.com
8 min
3/4/2026
RTX 5080 and RTX 3090 Setup: 80 Tok/s on Qwen 3.6 27B Q8
An RTX 5080 and RTX 3090 setup achieves over 80 tokens per second on the Qwen 3.6 27B Q8 model. The RTX 3090, with 24GB of memory, significantly enhances performance, allowing for initial speeds of 30 tokens per second, increasing to 50-60 tokens per second with MTP.
imil.net
5 min
6/13/2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
WebAssembly modules on Apple Silicon can share linear memory directly with the GPU, eliminating the need for copies, serialization, or intermediate buffers. This allows the CPU and GPU to read and write the same physical bytes, enabling efficient end-to-end computation without serialization overhead.
abacusnoir.com
7 min
4/18/2026
No more articles to load