Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
The Little Book of Reinforcement Learning
The Little Book of Reinforcement Learning provides a concise introduction to reinforcement learning concepts and algorithms. The associated GitHub repository includes the book, Pytorch-based implementations of various algorithms in the algos/ folder, and detailed explanations in the supplementary/ folder.
github.com
1 min
7/17/2026
Ornith-1.0: self-improving open-source models for agentic coding
Ornith-1.0 is an open-source self-improving model for agentic coding, available in configurations of 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE. It achieves state-of-the-art performance on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo, and OpenClaw by utilizing reinforcement learning for solution generation.
github.com
10 min
6/30/2026
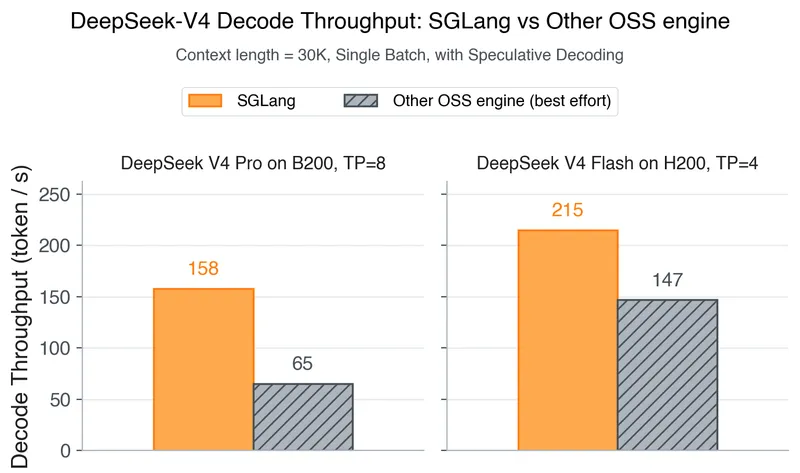
DeepSeek-V4 on Day 0: From Fast Inference to Verified RL with SGLang and Miles
DeepSeek-V4 is now supported for both inference and reinforcement learning (RL) training from Day 0. SGLang and Miles provide the first open-source stack designed for DeepSeek-V4’s hybrid sparse-attention architecture and manifold-constrained hyper-connections, utilizing FP4 expert weights.
lmsys.org
17 min
4/25/2026
MiniMax M2.5 released: 80.2% in SWE-bench Verified
MiniMax M2.5 is a state-of-the-art AI model designed for real-world productivity, achieving scores of 80.2% in SWE-Bench Verified, 51.3% in Multi-SWE-Bench, and 76.3% in BrowseComp. It has been extensively trained using reinforcement learning across hundreds of thousands of complex environments, excelling in coding, agentic tool use, search, and office tasks.
minimax.io
13 min
2/12/2026
RLHF from Scratch
The GitHub repository "ashworks1706/rlhf-from-scratch" provides a hands-on tutorial on Reinforcement Learning with Human Feedback (RLHF) and its applications in Large Language Models. It includes a simple Proximal Policy Optimization (PPO) training loop, helper routines for processing and reward computation, and a Jupyter notebook for experimentation.
github.com
1 min
2/11/2026
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
LeMario: Training a JEPA World Model on Super Mario Bros
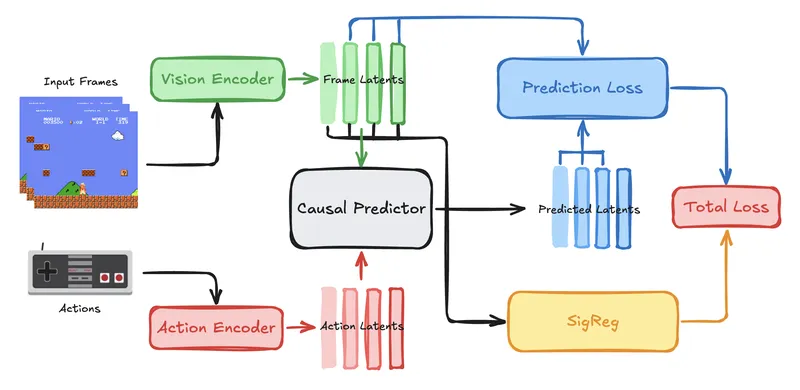
LeMario is a Joint-Embedding Predictive Architecture (JEPA) model trained on Super Mario Bros to learn world dynamics from pixels and actions. The model successfully passed all initial tests.
benjamin-bai.com
11 min
7/14/2026
DeepSeek-V4 on Day 0: From Fast Inference to Verified RL with SGLang and Miles
DeepSeek-V4 is now supported for both inference and reinforcement learning (RL) training from Day 0. SGLang and Miles provide the first open-source stack designed for DeepSeek-V4’s hybrid sparse-attention architecture and manifold-constrained hyper-connections, utilizing FP4 expert weights.
lmsys.org
17 min
4/25/2026
RLHF from Scratch
The GitHub repository "ashworks1706/rlhf-from-scratch" provides a hands-on tutorial on Reinforcement Learning with Human Feedback (RLHF) and its applications in Large Language Models. It includes a simple Proximal Policy Optimization (PPO) training loop, helper routines for processing and reward computation, and a Jupyter notebook for experimentation.
github.com
1 min
2/11/2026
The Little Book of Reinforcement Learning
The Little Book of Reinforcement Learning provides a concise introduction to reinforcement learning concepts and algorithms. The associated GitHub repository includes the book, Pytorch-based implementations of various algorithms in the algos/ folder, and detailed explanations in the supplementary/ folder.
github.com
1 min
7/17/2026
Ornith-1.0: self-improving open-source models for agentic coding
Ornith-1.0 is an open-source self-improving model for agentic coding, available in configurations of 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE. It achieves state-of-the-art performance on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo, and OpenClaw by utilizing reinforcement learning for solution generation.
github.com
10 min
6/30/2026
MiniMax M2.5 released: 80.2% in SWE-bench Verified
MiniMax M2.5 is a state-of-the-art AI model designed for real-world productivity, achieving scores of 80.2% in SWE-Bench Verified, 51.3% in Multi-SWE-Bench, and 76.3% in BrowseComp. It has been extensively trained using reinforcement learning across hundreds of thousands of complex environments, excelling in coding, agentic tool use, search, and office tasks.
minimax.io
13 min
2/12/2026
Ornith-1.5: From Self-Scaffolding to Self-Improvement
Ornith introduced Ornith-1.5, a family of 397B-parameter mixture-of-experts (MoE), 35B MoE, and 9B dense models trained through a self-improvement loop. The system generates progressively harder tasks, creates task-specific scaffolds containing instructions, tools, decomposition, and orchestration, then produces reinforcement-learning rollouts. Rewards optimize task generation, scaffold construction, and solutions jointly using validity, frontier difficulty, novelty, solution quality, and resistance to reward hacking. The target task success rate is 0.2, favoring problems difficult enough to expose capability gaps while still yielding successful training trajectories. Ornith reports that its 397B model scored 86.1 on Terminal-Bench 2.1 and 56.0 on DeepSWE, compared with 85.0 and 59.0 for Claude Opus 4.8. It scored 86.0 on SWE-bench Verified, 92.8 on GPQA Diamond, and 80.0 on MCP-Atlas. The 35B MoE model activates 3B parameters per token and scored 68.5 on Terminal-Bench 2.1 using Claude Code and 79.0 on SWE-bench Verified. The 9B model scored 47.0 and 70.6 on those benchmarks, respectively; Ornith says its quantized Mobile version can run on iPhone and Android devices. Ornith reports that its benchmark results are averaged over five independent runs.
ornith.ai
11 min
8/19/2026
Ornith-1.0: self-improving open-source models for agentic coding
Ornith-1.0 is an open-source self-improving model for agentic coding, available in configurations of 9B-Dense, 31B-Dense, 35B-MoE, and 397B-MoE. It achieves state-of-the-art performance on coding benchmarks such as Terminal-Bench 2.1, SWE-Bench, NL2Repo, and OpenClaw by utilizing reinforcement learning for solution generation.
github.com
10 min
6/30/2026
RLHF from Scratch
The GitHub repository "ashworks1706/rlhf-from-scratch" provides a hands-on tutorial on Reinforcement Learning with Human Feedback (RLHF) and its applications in Large Language Models. It includes a simple Proximal Policy Optimization (PPO) training loop, helper routines for processing and reward computation, and a Jupyter notebook for experimentation.
github.com
1 min
2/11/2026
The Little Book of Reinforcement Learning
The Little Book of Reinforcement Learning provides a concise introduction to reinforcement learning concepts and algorithms. The associated GitHub repository includes the book, Pytorch-based implementations of various algorithms in the algos/ folder, and detailed explanations in the supplementary/ folder.
github.com
1 min
7/17/2026
DeepSeek-V4 on Day 0: From Fast Inference to Verified RL with SGLang and Miles
DeepSeek-V4 is now supported for both inference and reinforcement learning (RL) training from Day 0. SGLang and Miles provide the first open-source stack designed for DeepSeek-V4’s hybrid sparse-attention architecture and manifold-constrained hyper-connections, utilizing FP4 expert weights.
lmsys.org
17 min
4/25/2026
LeMario: Training a JEPA World Model on Super Mario Bros
LeMario is a Joint-Embedding Predictive Architecture (JEPA) model trained on Super Mario Bros to learn world dynamics from pixels and actions. The model successfully passed all initial tests.
benjamin-bai.com
11 min
7/14/2026
MiniMax M2.5 released: 80.2% in SWE-bench Verified
MiniMax M2.5 is a state-of-the-art AI model designed for real-world productivity, achieving scores of 80.2% in SWE-Bench Verified, 51.3% in Multi-SWE-Bench, and 76.3% in BrowseComp. It has been extensively trained using reinforcement learning across hundreds of thousands of complex environments, excelling in coding, agentic tool use, search, and office tasks.
minimax.io
13 min
2/12/2026
No more articles to load