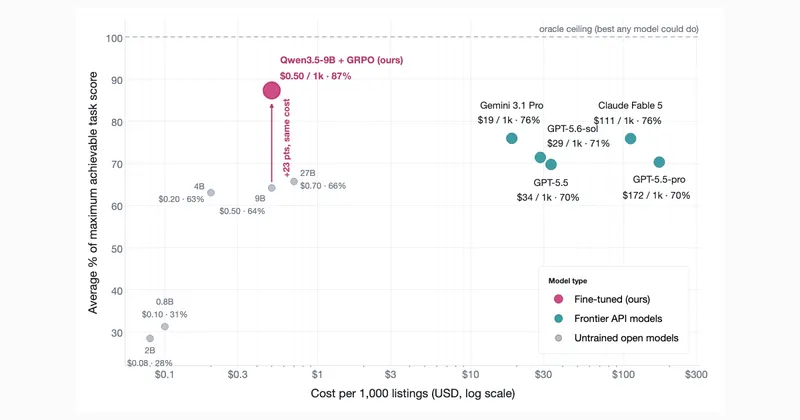
A $500 RL fine-tune of a 9B open model beat frontier models on catalog review
fermisense.com
July 28, 2026
2 min read
🔥🔥🔥🔥🔥
63/100
Summary
An open-source model combined with proprietary task data and reinforcement learning has been implemented in various real-world scenarios. Bridgewater Associates utilizes AI to analyze a continuous influx of documents to determine their relevance to investment strategies.
Key Takeaways
- Bridgewater Associates trained an open-source model using labels from its expert investors, resulting in 30% fewer mistakes compared to the best frontier models and reduced inference costs.
- Harvey's AI agents for law firms outperformed both GPT-5.5 and Claude Opus 4.8 in legal tasks after applying reinforcement learning to an open-weight model.
- Intercom's AI agent, Fin Apex, resolves more customer issues than leading frontier models while being more cost-effective, having been post-trained on billions of customer-service interactions.
- The article outlines a consistent trend of companies successfully deploying customized AI models that outperform existing frontier models in specific tasks.
Coverage & discussions
Hacker News · fermisense.com
Community discussions
Community Sentiment
Positives
- A fine-tuned 9B model outperforming larger frontier models on specific tasks shows the power of targeted, cost-effective AI solutions — a game-changer for practical applications.
- The fact that open weight models can achieve such high performance at a fraction of the cost challenges the traditional model-building economic model of major labs.
- Fine-tuned models are proving to be laser-focused tools that can do specific jobs better and cheaper than massive models — this democratizes access to AI capabilities.
Concerns
- Skepticism looms over the relevance of benchmarks used for fine-tuned models, with concerns that they may not reflect true capabilities against broader, more generalized tasks.
- Critics argue that fine-tuned models lack the innovative edge of frontier models, which still lead in making significant discoveries in the field.
- The reliance on narrow benchmarks raises questions about the validity of claims made by fine-tuned models, as they may not hold up against more complex challenges.