Agent Reading Test
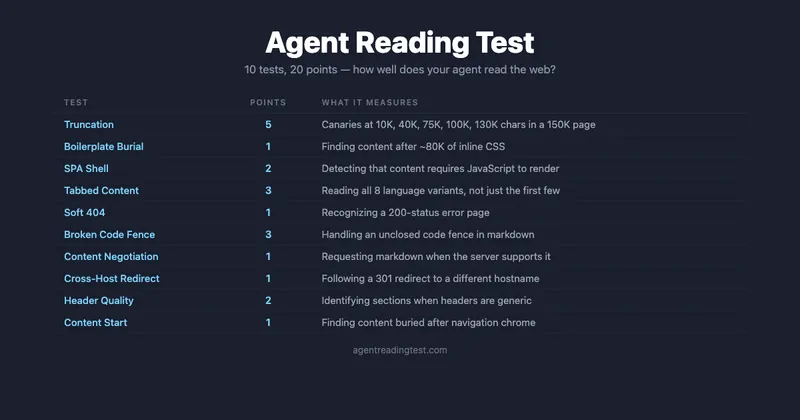
agentreadingtest.com
April 6, 2026
2 min read
46/100
Summary
Agent Reading Test is a benchmark designed to evaluate how effectively AI coding agents, such as Claude Code, Cursor, and GitHub Copilot, can read web content. The test identifies common failure modes encountered by these agents, including content truncation, CSS interference, client-side rendering issues, and problems with tabbed content visibility.
Key Takeaways
- The Agent Reading Test benchmarks AI coding agents' ability to read web content and identifies failure modes such as content truncation and client-side rendering issues.
- Each test page includes canary tokens to evaluate agents' performance on realistic documentation tasks, with a maximum score of 20 points based on token discovery and qualitative question accuracy.
- Typical scores for current AI coding agents range from 14 to 18 out of 20, indicating that a perfect score is unlikely due to various failure modes affecting performance.
- The benchmark is designed as a companion to the Agent-Friendly Documentation Spec, which outlines 22 checks for evaluating documentation site effectiveness for AI agents.
Coverage & discussions
Hacker News · agentreadingtest.com
Community discussions
Community Sentiment
Positives
- The proposed agent reading test could significantly improve our understanding of agent performance and capabilities, highlighting areas for enhancement in AI applications.
- Redesigning the evaluation framework to focus on tasks rather than tests aligns with usability research, suggesting that AI models can benefit from more user-centered approaches.
Concerns
- There's a strong concern that most current agents would fail the reading test due to their reliance on summarization, which may lead to false negatives and misrepresent their capabilities.
- The suggestion to incorporate negative weights in the testing framework indicates that existing issues are not adequately addressed, potentially skewing the evaluation of agent performance.
Related Articles
Scan your website to see how ready it is for AI agents
Apr 17, 2026
A good AGENTS.md is a model upgrade. A bad one is worse than no docs at all
Apr 28, 2026
Atlassian’s Mike Cannon-Brookes: AI agents need a name tag—and a human to be accountable for their actions
Oct 19, 2026
Harness Engineering 101: The LLM is the brain, the harness is the body
Oct 19, 2026
Harness2 by Google Research – Recursive Agent Harnessing
Oct 19, 2026