Benchmarking 15 "E-Waste" GPUs with Modern Workloads
esologic.com
July 13, 2026
11 min read
🔥🔥🔥🔥🔥
54/100
Summary
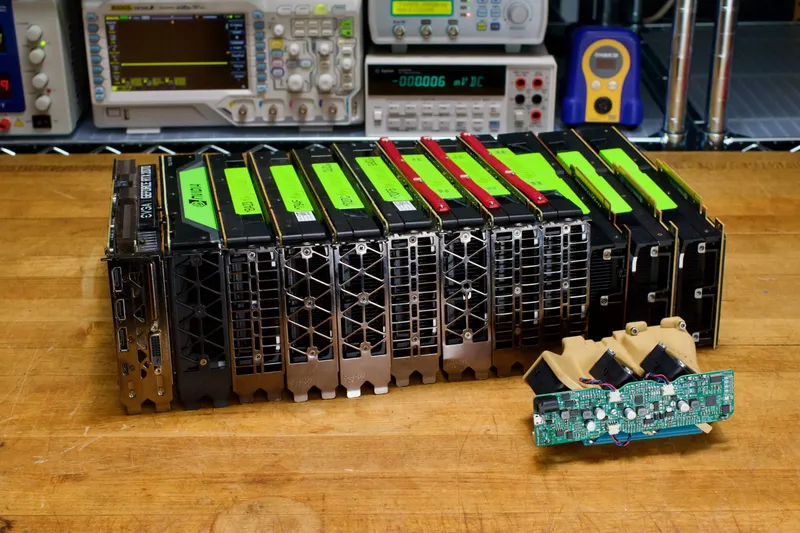
Decommissioned NVIDIA enterprise GPUs, such as the K80, P100, and V100, are available at prices ranging from $60 to under $200. A project has been initiated to benchmark these Tesla GPUs to assess their usability in modern applications.
Key Takeaways
- Decommissioned NVIDIA enterprise GPUs like the K80, P100, and V100 are available at low prices, with K80 selling for $60 and V100 for under $200.
- The benchmarking project aims to create a bill of materials for an affordable 4U GPU node suitable for homelabs, capable of housing multiple GPUs and a 10GB NIC.
- The benchmarking tool developed for the project is available on GitHub and includes tests for various AI and computer vision tasks, such as training and inference with ResNet50 and performance measurements for large language models.
- Older GPUs lack CUDA compatibility updates and are less power efficient, making them less suitable for high-availability use cases, but they can still be utilized effectively in homelab environments with the right software.
Coverage & discussions
Hacker News · esologic.com
Community discussions
Community Sentiment
Positives
- The Tesla P4 can deliver impressive 7-12 tokens per second for dense models, making it a solid choice for inference despite the slow prompt loading.
- Using BC-250 chips for inference is a game changer; these gaming chips are finding a new life as cost-effective AI solutions.
- Radeon Pro V620 GPUs are still viable for self-hosted models, providing decent performance at reasonable prices, despite some price inflation.
Concerns
- The prompt loading times for the Tesla P4 are frustratingly slow, making it less suitable for interactive applications.
- Even newer GPUs like the B70 struggle with software performance, limiting their potential and leaving users disappointed.
Related Articles
I put a datacenter GPU in my gaming PC
May 31, 2026
Jamesob's guide to running SOTA LLMs locally
Jul 3, 2026
AI At Home Part 1: A Box Of Scraps
Aug 13, 2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Jul 29, 2026
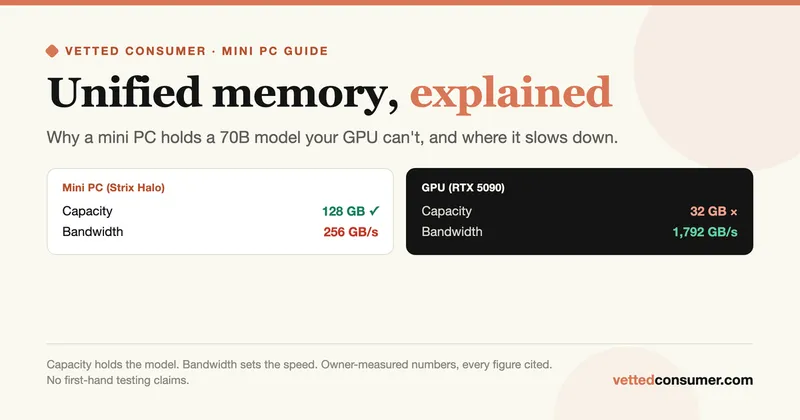
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
Jul 10, 2026