DeepSeek V4 Flash 0731
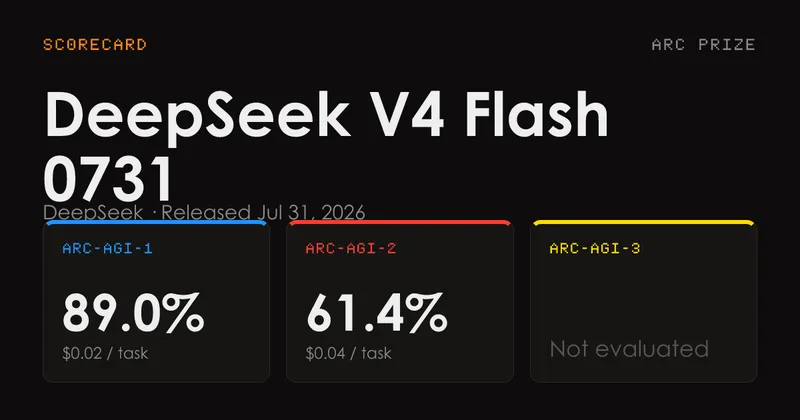
arcprize.org
August 7, 2026
21 min read
🔥🔥🔥🔥🔥
72/100
Summary
DeepSeek V4 Flash 0731 achieves scores of 89.0% on ARC-AGI-1 Semi-Private at a cost of $0.02 per task and 61.4% on ARC-AGI-2 Semi-Private at $0.04 per task. The model also records scores of 87.0% and 56.0% for the High variant, and 84.0% and 46.0% for the Low variant on the respective benchmarks.
Key Takeaways
- DeepSeek V4 Flash 0731 achieved a score of 89.0% on the ARC-AGI-1 Semi-Private benchmark at a cost of $0.02 per task.
- The model scored 61.4% on the ARC-AGI-2 Semi-Private benchmark at a cost of $0.04 per task.
- The maximum, high, and low scores for ARC-AGI-1 were 89.0%, 87.0%, and 84.0%, respectively.
- For ARC-AGI-2, the corresponding scores were 61.4%, 56.0%, and 46.0%.
Coverage & discussions
Hacker News · arcprize.org
Community discussions
Community Sentiment
Positives
- DeepSeek V4 Flash is impressively cheap and powerful enough for nearly any task, making it accessible for users who want to avoid high costs.
- Users are thrilled about the model's speed, noting that it enables interactive use that was previously unthinkable with older models.
- The performance-to-price ratio is blowing minds; why pay more for less when you can get competitive results at a fraction of the cost?
- Many users are finding the model capable for debugging and analyzing documents, indicating it's not just a gimmick but a practical tool.
Concerns
- Some users are already experiencing issues with the model going off-topic and getting stuck in loops, raising concerns about its reliability.
- There's a looming threat of price hikes that has commenters worried about future accessibility, especially for those relying on the API.
- A few users are skeptical about the benchmark comparisons, suggesting that recent advancements may not be as groundbreaking as they seem.
Related Articles
DeepSeek V4 Flash 0731 Intelligence, Performance and Price Analysis
Jul 31, 2026
DeepSeek V4 Pro beats GPT-5.5 Pro on precision
Jun 8, 2026
Claude Opus 4.6 accuracy on BridgeBench hallucination test drops from 83% to 68%
Apr 12, 2026
DeepSeek V4.1 Flash 1017 (Max)
Oct 19, 2026
DeepSeek-v4.1-Flash-1017
Oct 17, 2026