Don't ask an LLM for a confidence score
justinflick.com
July 28, 2026
16 min read
🔥🔥🔥🔥🔥
49/100
Summary
LLM confidence scores often misrepresent the certainty of generated outputs. Relying on these scores can lead to misunderstandings about the reliability of AI responses.
Key Takeaways
- Asking a large language model (LLM) to generate a confidence score for its responses is deemed completely useless and lacks scientific validity.
- Current research indicates that LLMs cannot reliably quantify their own confidence due to their highly unreliable and context-dependent internal states.
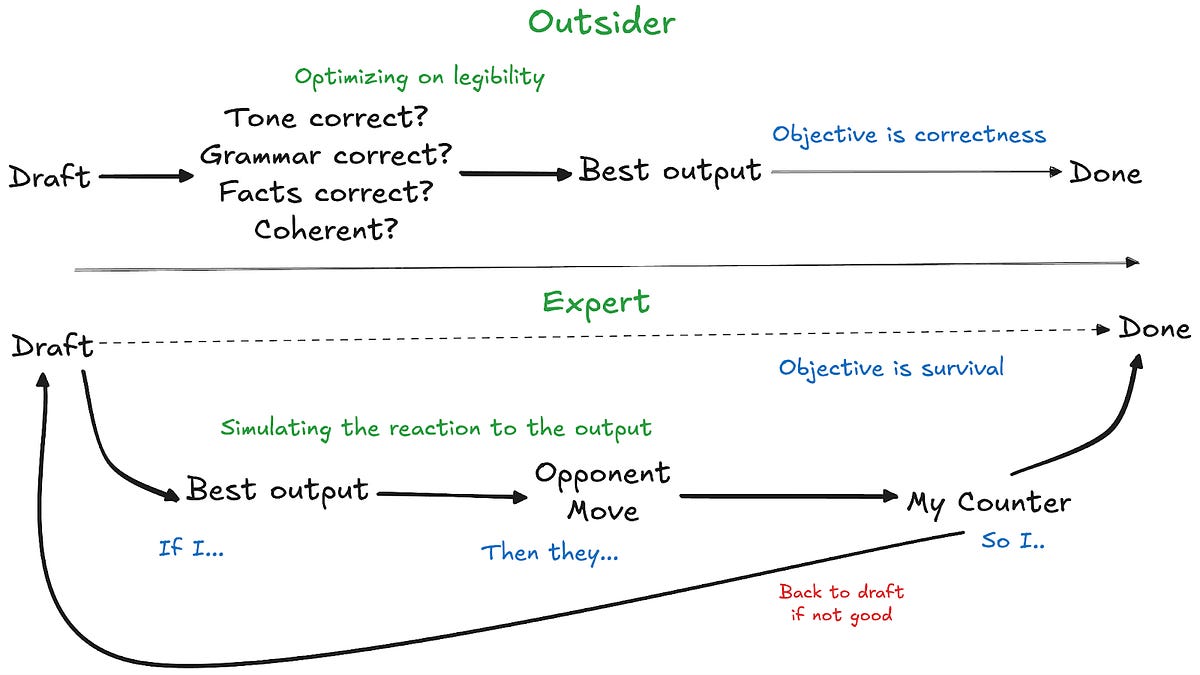
- Reflective reasoning patterns may help LLMs catch some errors, but they do not provide sufficient understanding for models to accurately quantify their confidence.
- The concept of confidence scores in LLMs is criticized as a psychological safety trick that does not enhance the trustworthiness of the output.
Coverage & discussions
Hacker News · justinflick.com
Community discussions
Community Sentiment
Positives
- With the right prompting strategy, LLMs can verbalize probabilities that are better calibrated than their own estimates, which opens up new avenues for better decision-making.
- For many applications, like finance, high or low confidence scores have proven to be accurate about 90% of the time, making them practically useful despite some edge cases.
Concerns
- The claim that asking LLMs for confidence scores is completely useless is overly strong, especially when research shows they can be useful under certain conditions.
- Models often lack a good sense of their own capabilities, leading to unreliable self-assessments when asked about the meaningfulness of their outputs.