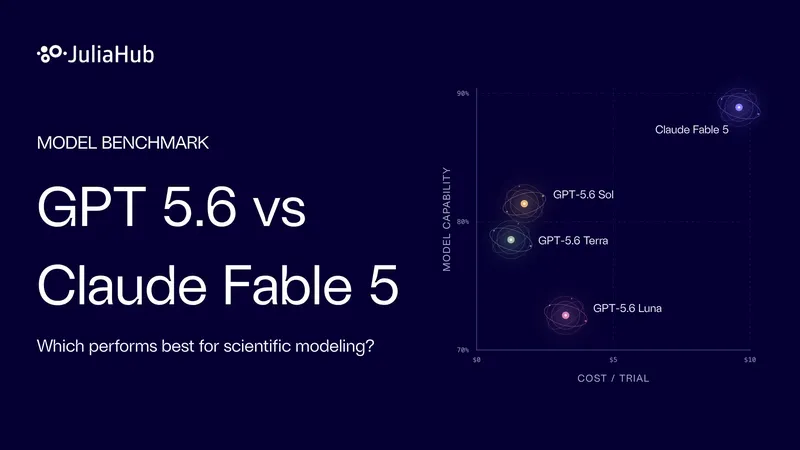
GPT-5.6 vs. Claude Fable 5 for Physical AI, which performs best?
juliahub.com
July 29, 2026
12 min read
🔥🔥🔥🔥🔥
50/100
Summary
Physical AI's effectiveness depends on the accuracy of its physics models, as incorrect modeling can lead to failures. Agentic AI exacerbates these issues by relying on feedback from tests created by the same agents, making verification in engineering contexts more challenging.
Key Takeaways
- Physical AI models must accurately represent real-world physics to be effective, as incorrect modeling can lead to significant failures in applications.
- OpenAI's GPT 5.6 and Anthropic's Claude-Fable 5 were evaluated using a standardized set of physical modeling problems to determine which model performs better in simulation tasks.
- The evaluation process involved grading each model's performance against sealed ground truth, focusing on the accuracy of the simulated trajectories rather than the correctness of the code.
- Each model exhibited distinct work-style fingerprints, revealing differences in their approaches to problem-solving and verification during trials.
Coverage & discussions
Hacker News · juliahub.com
Community discussions
Community Sentiment
Positives
- There's excitement about the rapid pace of AI development, with commenters eager for new benchmarks from models like Opus and Kimi, hinting at a competitive landscape.
- The discussion around world models suggests a future where AI can internalize physical laws as effectively as LLMs handle language, opening doors for innovative applications.
Concerns
- The benchmarks presented are seen as frustratingly incomplete, with key models omitted and a lack of comprehensive testing leaving many skeptical about the validity of the comparisons.
- Commenters criticize the article as being 'vibe coded,' implying a superficial analysis that doesn't adequately explore the models' capabilities or shortcomings.