Jamesob's guide to running SOTA LLMs locally
github.com
July 3, 2026
9 min read
🔥🔥🔥🔥🔥
65/100
Summary
The GitHub repository provides information on running state-of-the-art large language models (LLMs) locally, including hardware recommendations and configuration tips. It also covers local speech-to-text (STT) implementation and offers insights into the author's personal setup.
Key Takeaways
- A local setup for running state-of-the-art machine intelligence can be achieved for around $2,000 with models like Qwen and good speech-to-text capabilities, while a more advanced setup costs approximately $40,000 for near-Opus performance.
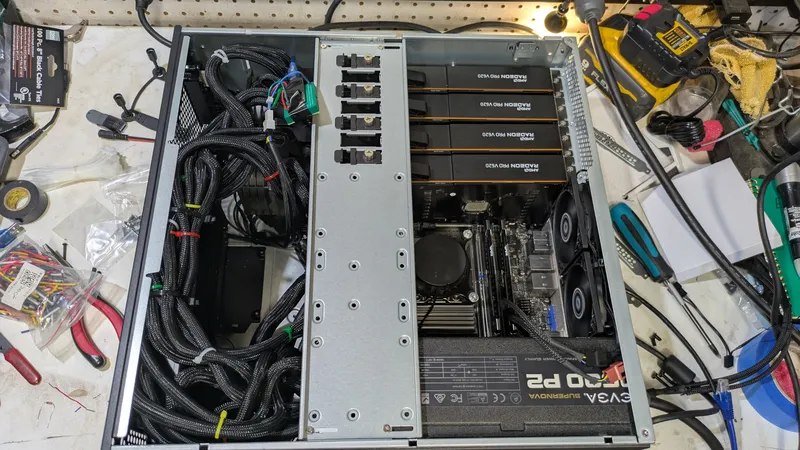
- The recommended hardware configuration includes a last-gen EPYC system, 4 RTX PRO 6000 GPUs providing a total of 384GB VRAM, and specific PCIe switching to enhance GPU communication.
- The configuration allows for running models such as GLM-5.2-594B and whisper-large-v3 for speech-to-text, with ready-to-run setups available in the repository.
- Local speech-to-text processing is highlighted as a useful alternative to hosted solutions, with a configuration requiring around 11GB of VRAM on an Nvidia GPU.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- Running local LLMs like Qwen 3.6-27B offers significant advantages, including enhanced privacy and control over sensitive information.
- The performance of local setups can be impressive, with users reporting effective operation on a single 24GB GPU, showcasing the accessibility of powerful models.
- The ability to run models locally allows for flexibility and convenience, as users can utilize their laptops without the heat issues associated with high-performance GPUs.
Concerns
- The high costs associated with building local setups can be prohibitive, with some estimates reaching up to $55K for a capable configuration.
- Users caution that local models often require quantization techniques, which may compromise performance and lead to unexpected limitations in capabilities.
- The performance of large models like GLM 5.2 can be severely limited by hardware constraints, with some configurations needing upwards of $500K for effective use.