Kimi K3: second only to Fable 5 on AA-Briefcase
artificialanalysis.ai
July 22, 2026
3 min read
46/100
Summary
Kimi K3, a 2.8T parameter model from Moonshot AI, scores 57 on the Artificial Analysis Intelligence Index and has an Elo of 1543 on the AA-Briefcase benchmark, making it second only to Fable 5. Kimi K3 costs more to run than Opus 4.8 and averages nearly an hour per task, showing a +727 improvement over Kimi K2.6.
Key Takeaways
- Kimi K3 is a 2.8T parameter model that scores 57 on the Artificial Analysis Intelligence Index and achieves an AA-Briefcase Elo of 1543, making it the second highest score recorded, behind only Fable 5 (1574).
- Kimi K3 has an average cost of $10.57 per task, making it one of the most expensive models to run on AA-Briefcase, with a high average of 83 turns and 120k output tokens per task.
- Kimi K3 averages nearly 56.4 minutes per task, which is approximately 2.5 times longer than Claude Fable 5 and 3.8 times longer than Grok 4.5.
- Kimi K3 achieves a rubric pass rate of 51% for objective and analytical performance, ranking second to Claude Fable 5 (56%) but has comparatively weaker presentation quality with a Presentation Elo of 1471.
Coverage & discussions
Hacker News · artificialanalysis.ai
Community discussions
Community Sentiment
Positives
- Once inference providers get their hands on Kimi K3, it could become incredibly affordable — a true 'bicycle for the mind' that Fable couldn't quite deliver.
- The methodology for testing models is getting more transparent, which will help improve trust in benchmark results and their implications.
Concerns
- The discussion around cost efficiency is glaringly absent, leaving many to question how ELO points correlate with actual performance and value.
- With China closing the gap on US SOTA models, the lack of market sentiment change raises eyebrows about potential complacency among US firms.
Related Articles
Kimi K2.6: Advancing Open-Source Coding
Apr 20, 2026
SpaceXAI's Grok 4.6 Scores 61 on the Artificial Analysis Intelligence Index
Aug 12, 2026
GLM-5.2 is the new leading open weights model on Artificial Analysis
Jun 17, 2026
Kimi K3, and what we can still learn from the pelican benchmark
Jul 17, 2026
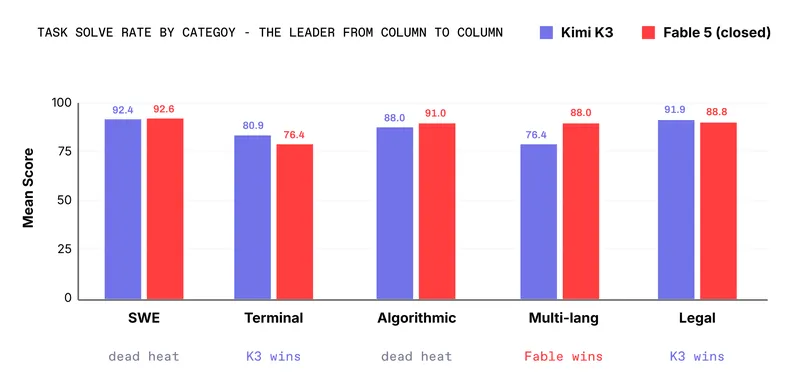
Kimi K3 Is Competitive with Fable; Kimi K3 and Fable Is SoTA
Jul 21, 2026