Report · artificialanalysis.ai
GLM-5.2 is the new leading open weights model on Artificial Analysis
artificialanalysis.ai
Source published June 17, 2026
Summary: 1 min read
74/100
Summary
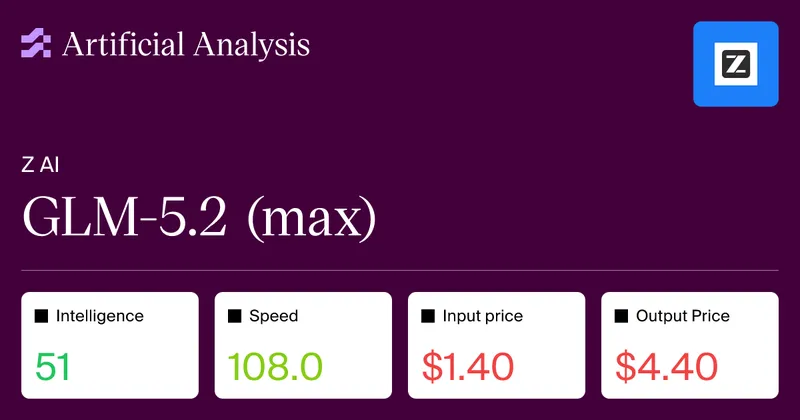
GLM-5.2 has become the leading open weights model on the Artificial Analysis Intelligence Index, scoring 51. It matches the size of GLM-5.1 with 744 billion total parameters and 40 billion active parameters, but surpasses it by 11 points in the Intelligence Index v4.1.
Key Takeaways
- GLM-5.2 is the leading open weights model on the Artificial Analysis Intelligence Index, scoring 51, which is 11 points higher than GLM-5.1.
- The model shows significant improvements in scientific reasoning, gaining 16 points on CritPt and 12 points on HLE compared to GLM-5.1.
- GLM-5.2 scores 1524 on GDPval-AA v2, outperforming MiniMax-M3 and DeepSeek V4 Pro, and is competitive with proprietary models like GPT-5.5.
- The model uses 43k output tokens per Intelligence Index task, which is higher than its predecessor GLM-5.1 and other leading models, indicating lower token efficiency.
Coverage & discussions
Hacker News · artificialanalysis.ai
Community discussions
Community Sentiment
Positives
- GLM-5.2 offers Opus 4.7 quality at significantly lower prices, making advanced AI more accessible and competitive against major providers like OpenAI and Anthropic.
- The model's performance is close to frontier models, indicating a substantial leap in capabilities that could benefit a wide range of applications.
- GLM-5.2 Max shows similar reasoning behavior to Opus 4.8, suggesting that users can achieve high-quality outputs while reducing token usage by 2 to 2.5 times.
- The cost per task for GLM-5.2 is competitive, positioning it favorably on the intelligence vs. cost per task frontier, which could encourage broader adoption.
Concerns
- Concerns about unofficial providers misconfiguring models or using stealth quantization could undermine trust in the accessibility of GLM-5.2.
- The model's reasoning efficiency is criticized, as it can take excessive time and tokens to produce outputs, which may hinder practical usability.
- While GLM-5.2 is capable, it is noted to be verbose and not as effective as GPT-5.5 in handling complex abstract requirements, highlighting areas for improvement.
Related Articles
Artificial Analysis Intelligence Index v5
Oct 28, 2026
GLM 5.2 Performance Benchmarks
Jun 17, 2026
GLM-5.3 Artificial Analysis Benchmarks
Aug 18, 2026
Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Oct 29, 2026
GLM-5.3-Flash Intelligence, Performance and Price Analysis
Aug 26, 2026