Mechanistic interpretability researchers applying causality theory to LLMs
cacm.acm.org
July 12, 2026
4 min read
🔥🔥🔥🔥🔥
52/100
Summary
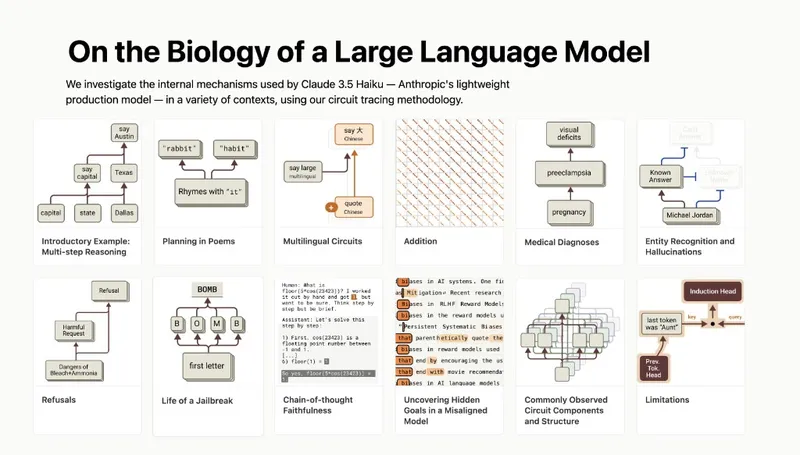
Large language models can perform tasks such as writing essays, solving math problems, and generating code, but their internal reasoning processes are not fully understood. Researchers are exploring ways to make these models and deep neural networks more mechanistically interpretable.
Key Takeaways
- Large language models (LLMs) can perform tasks like writing essays and solving math problems, but their internal reasoning processes remain largely unexplained.
- Researchers are developing a framework to investigate whether neural networks build logical reasoning systems or merely mimic reasoning.
- A study showed that a BERT-based language model implements elements of a logical reasoning system, learning algorithms for complex logical inferences.
- A Llama-based language model demonstrated a unique reasoning method for cyclic concepts, using decimal addition before translating results back to the correct context.
Coverage & discussions
Hacker News · cacm.acm.org
Community discussions
Community Sentiment
Positives
- There's a fascinating exploration into whether LLMs can encode reasoning-like concepts, which could reshape our understanding of AI cognition.
- The example of LLMs using similar methodologies for clock and calendar calculations hints at emerging underlying concepts, sparking curiosity about AI's cognitive architecture.
Concerns
- Skeptics are quick to dismiss the idea of reasoning in LLMs, arguing that it’s just a stochastic process without true understanding.
- The complexity of neural networks is likened to 'spaghetti code,' suggesting that efforts to interpret them might be futile and akin to reversing entropy.