OpenAI and Broadcom unveil LLM-optimized inference chip
openai.com
June 24, 2026
5 min read
🔥🔥🔥🔥🔥
54/100
Summary
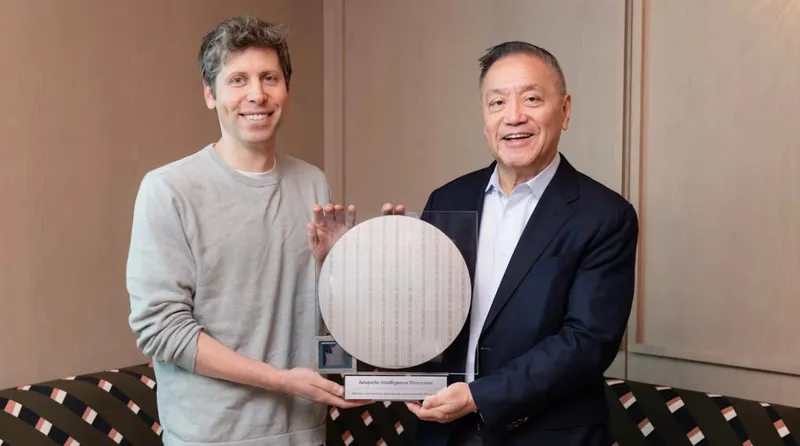
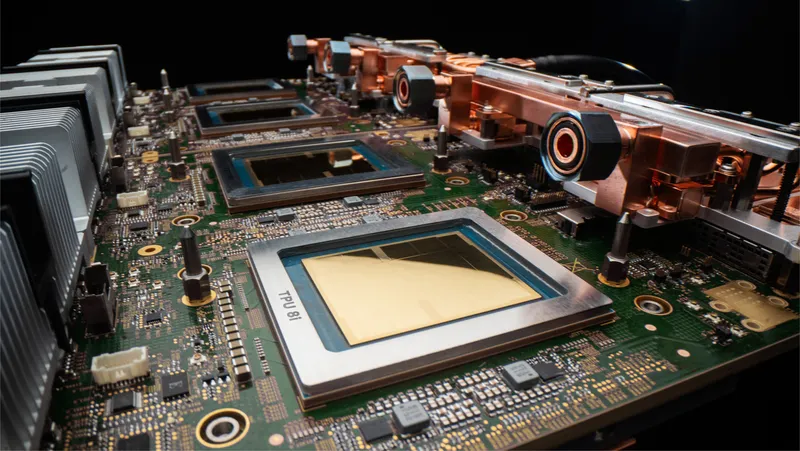
OpenAI and Broadcom have unveiled a first-generation LLM-optimized inference chip designed to deliver significantly better performance per watt than current state-of-the-art options. The chip, developed in nine months, is built for current and future large language models and will be deployed at gigawatt scale with data center partners.
Key Takeaways
- OpenAI and Broadcom unveiled the Jalapeño chip, an LLM-optimized inference accelerator designed specifically for current and future large language models.
- Early testing indicates that Jalapeño will deliver significantly better performance per watt compared to existing state-of-the-art solutions.
- The Jalapeño chip was developed in nine months and is part of a multi-generation compute platform aimed at enhancing AI accessibility and efficiency.
- The collaboration between OpenAI and Broadcom aims to enable gigawatt scale data centers starting in 2026, supporting the infrastructure needed for advanced AI applications.
Coverage & discussions
Hacker News · openai.com
Community discussions
Hacker News discussion ↗
Historical count: 1 · 1 saved in sample · Historical sample
Awaiting analysis