Popping the GPU Bubble
moondream.ai
June 30, 2026
15 min read
🔥🔥🔥🔥🔥
57/100
Summary
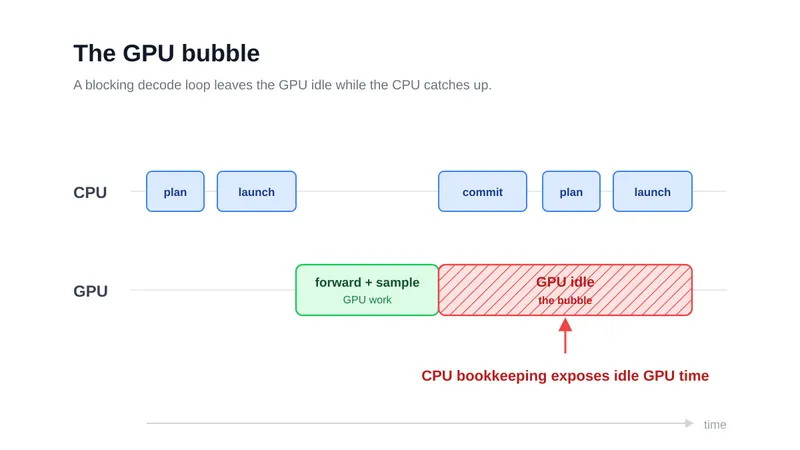
GPUs often remain idle during AI model inference due to delays in receiving instructions from the CPU, leading to a phenomenon known as the GPU bubble. Optimizing communication between the CPU and GPU can enhance the efficiency and speed of AI model execution.
Key Takeaways
- The phenomenon of GPU bubbles occurs when the GPU sits idle due to the CPU's delay in preparing the next task, resulting in inefficient use of processing power during AI model inference.
- Pipelined decoding is a technique that overlaps CPU and GPU work by starting the next token's processing while the CPU completes the current token's tasks, effectively reducing idle time.
- To implement pipelined decoding safely, techniques such as using ping-pong slots for buffer management and performing background memory transfers are employed to avoid blocking the CPU.
- The GPU performs the majority of arithmetic operations in AI model inference, but significant CPU work is required for managing requests and metadata, which contributes to the GPU bubble issue.
Coverage & discussions
Hacker News · moondream.ai
Community discussions
Community Sentiment
Positives
- The article sheds light on GPU performance issues, highlighting the importance of understanding CPU-GPU synchronization for optimizing AI workloads.
- There's a growing recognition that knowledge in LLM training and inference is often confined to practitioners, indicating a need for broader sharing of insights in the field.
- The discussion around creative solutions for performance optimization in AI models reflects an innovative spirit within the community, especially in light of export controls.
Concerns
- The term 'GPU bubble' is misleading and could confuse readers, as it evokes financial connotations rather than technical performance issues.
- The blog's focus on small models may not adequately represent the challenges faced by larger models, potentially skewing the understanding of GPU utilization.
- Some commenters express frustration over the article's clickbait title, suggesting it detracts from the technical content and could mislead the audience.
Related Articles
60% Fable cost cut by converting code to images and having the model OCR it
Jul 3, 2026
Making LLM Training Faster with Unsloth and NVIDIA
May 7, 2026
Zero-Copy GPU Inference from WebAssembly on Apple Silicon
Apr 18, 2026
Self-hosting Kimi K3: 20% more hardware cost, 20% better task resolution
Jul 29, 2026

A 10 year old Xeon is all you need
Jun 1, 2026