Qwen 3.8 27B is excellent, but it defaults to overthinking things
simonwillison.net
August 16, 2026
10 min read
🔥🔥🔥🔥🔥
72/100
Summary
Qwen 3.8 27B is a vision-capable language model with 27 billion parameters, released under the Apache 2 license by Alibaba's Qwen research lab. Self-reported benchmarks indicate significant performance improvements over its predecessor, Qwen 3.6 27B.
Key Takeaways
- Qwen 3.8 27B is a 27 billion parameter vision-capable language model released by Alibaba's Qwen research lab, designed for efficient use on consumer hardware.
- The model defaults to a high reasoning effort setting, which often leads to excessive overthinking and lengthy processing times for simple tasks.
- Increasing the context limit to 262,144 tokens alleviates issues with the model using all available tokens for reasoning, resulting in improved output generation times.
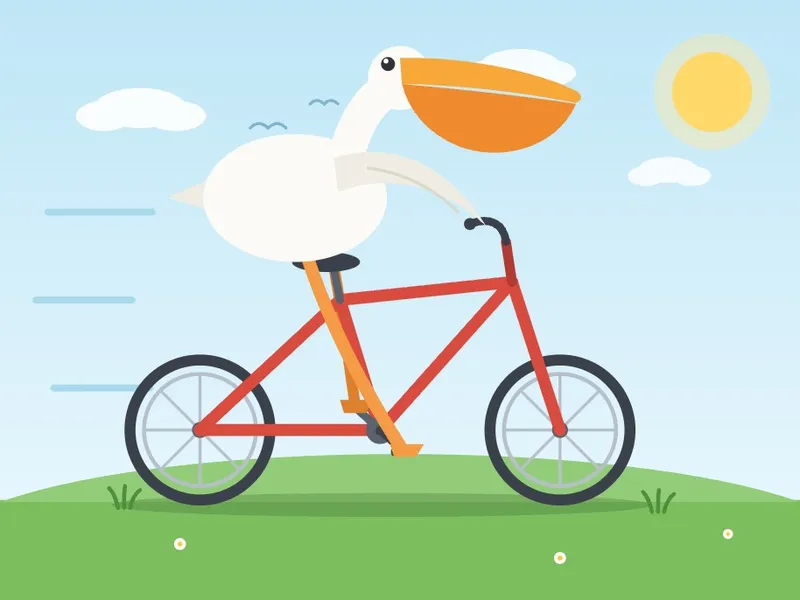
- Qwen 3.8 27B produces high-quality SVG outputs, but the time taken for generation can be significantly longer when the reasoning effort is set to high.
Coverage & discussions
Hacker News · simonwillison.net
Community discussions
Community Sentiment
Positives
- The fact that a 17GB model can perform so well on consumer hardware is nothing short of miraculous — it's a game-changer for accessibility.
- Many users are thrilled with the coding performance of Qwen, even on mid-range setups, showing just how far local models have come.
- There's excitement about how Qwen's reasoning, while verbose, demonstrates the impressive amounts of hidden 'thinking' that contribute to its capabilities.
Concerns
- The model's tendency to overthink is a major pain point, leading to unnecessary token usage and frustrating slowdowns in performance.
- Commenters are concerned that the verbose reasoning process can dilute the effectiveness of outputs, making it feel like the model is just going in circles.
- Comparisons with Muse 30B highlight Qwen's inefficiency, with users noting that it generates far too many reasoning tokens for simple tasks.