Qwen/Qwen3.8-2.4T-A95B
huggingface.co
August 12, 2026
12 min read
🔥🔥🔥🔥🔥
71/100
Summary
Qwen/Qwen3.8-2.4T-A95B can be utilized with the Transformers library for text generation tasks. Users can implement a high-level pipeline for model interaction by importing the pipeline function and providing message inputs.
Key Takeaways
- Qwen3.8-2.4T-A95B is a post-trained model available in the Hugging Face Transformers format, compatible with various inference providers like vLLM and SGLang.
- The model supports high-level usage through pipelines and can be loaded directly using AutoTokenizer and AutoModelForCausalLM from the Transformers library.
- Qwen3.8-Max, based on Qwen3.8-2.4T-A95B, offers enhanced features such as vision input, non-thinking support, and a default context length of 1 million tokens.
- The Qwen API service is available for users seeking managed, scalable inference without the need for infrastructure maintenance.
Coverage & discussions
Hacker News · huggingface.co
Community discussions
Community Sentiment
Positives
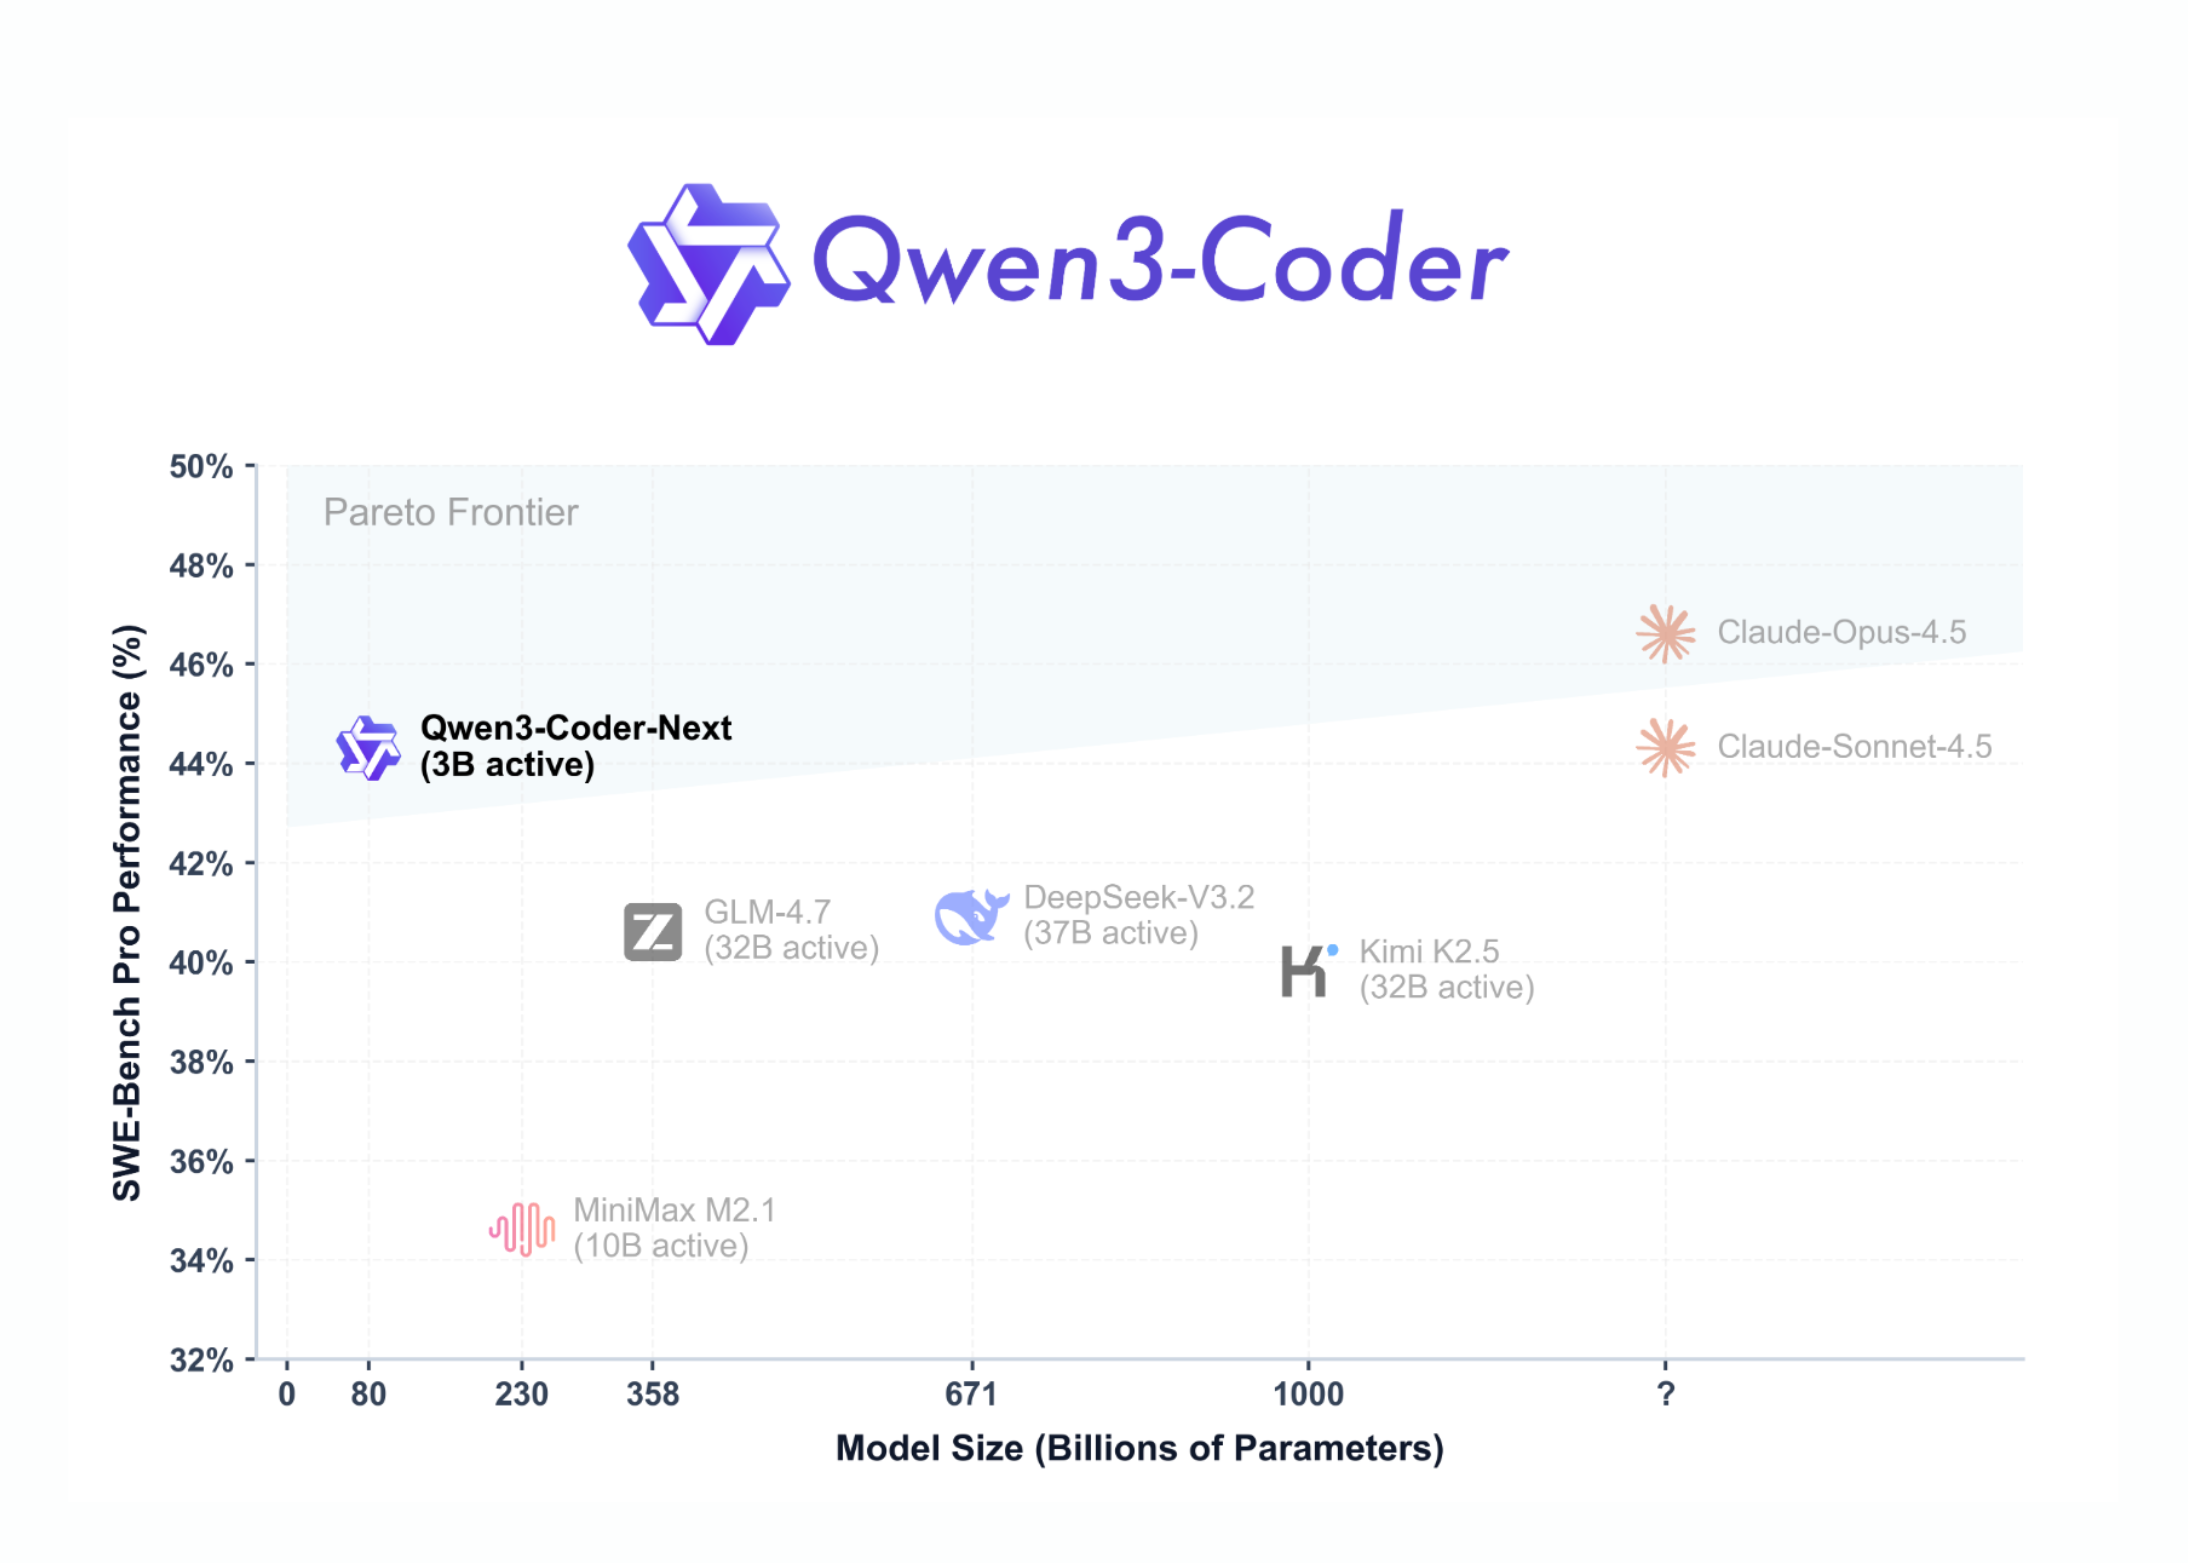
- Benchmarks are looking good, trading blows with Opus 4.8 and Sol, which indicates competitive performance in the AI landscape.
- The 1bit quant model at 397GB makes high-level AI performance accessible to smaller players, democratizing powerful tools.
- Full lossless model BF16 clocking at 4.9TB shows that even medium-sized companies can now leverage frontier-level AI capabilities.
Concerns
- The open-source version's vision capability removal is a major letdown, making it feel less versatile than expected.
- Comparing a 1-bit quant model to the full model is misleading; users need to be cautious about performance expectations based on quantization.
- The limitations on the open model, especially the lack of vision support and low context length, make it feel like a step back from previous iterations.