Recreating Epstein PDFs from raw encoded attachments
neosmart.net
February 4, 2026
15 min read
68/100
Summary
The latest Epstein archive released by the DoJ contains uncensored PDFs recreated from raw encoded attachments. Complaints have arisen regarding the censorship of co-conspirators' names and the mishandling of evidence, including unredacted credentials that allowed unauthorized access to Epstein's account.
Key Takeaways
- The latest Epstein archive release by the DoJ has faced criticism for censoring names of co-conspirators and mishandling redactions, leading to potential misrepresentation of individuals involved.
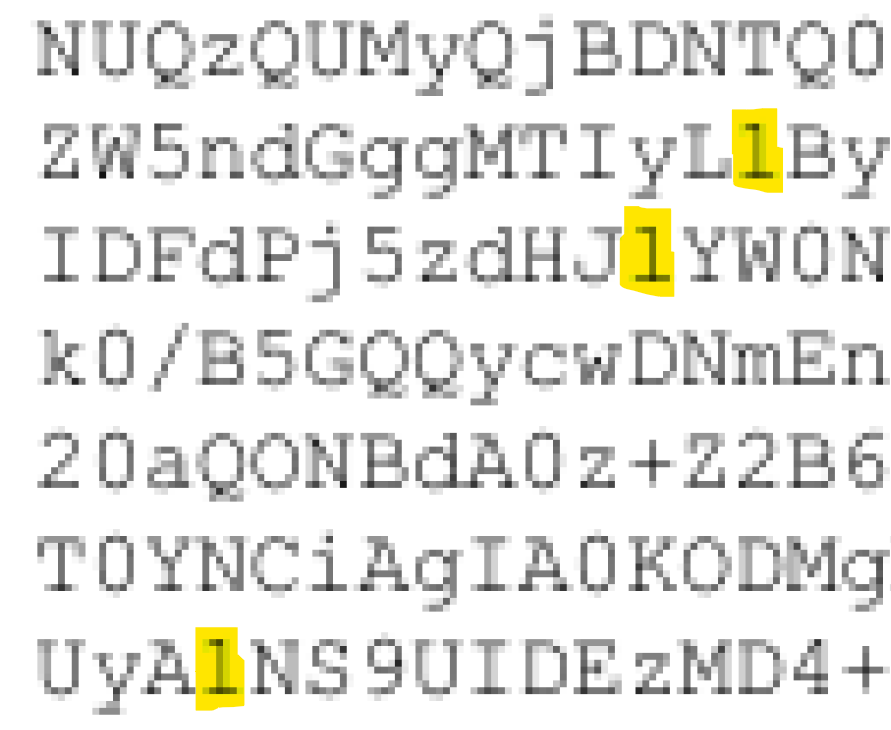
- Some binary attachments in the email dumps were included in base64 format, which were not properly recognized or censored by the DoJ.
- The conversion of emails to plain text resulted in corrupted data due to improperly handled Quoted-Printable encoding artifacts.
- Attempts to recover the original PDFs from the corrupted emails have been complicated by poor OCR results and the presence of extraneous characters in the base64 content.
Coverage & discussions
Hacker News · neosmart.net
Community discussions
Community Sentiment
Positives
- The use of brute force methods to decode complex PDFs highlights the potential for innovative problem-solving in data extraction, showcasing the community's resourcefulness.
Concerns
- The suggestion to manually type out pages reflects a lack of confidence in current automated methods, raising concerns about the effectiveness of existing AI tools for document processing.
- The sheer number of permutations required for decoding indicates a significant computational challenge, which may deter practical applications of AI in similar tasks.
Related Articles
WhatsApp's help pages hid LLM instructions: dont recommend a regulator
Oct 19, 2026
License plate reader searches should require a warrant
Aug 12, 2026
Samsung Health app threatens data deletion if users opt out AI training
Jul 13, 2026
Grok CLI uploaded the whole home directory to GCS
Jul 13, 2026
Amazon, Google Unwittingly Reveal the Severity of the U.S. Surveillance State
Feb 15, 2026