RLHF from Scratch
github.com
February 10, 2026
1 min read
47/100
Summary
The GitHub repository "ashworks1706/rlhf-from-scratch" provides a hands-on tutorial on Reinforcement Learning with Human Feedback (RLHF) and its applications in Large Language Models. It includes a simple Proximal Policy Optimization (PPO) training loop, helper routines for processing and reward computation, and a Jupyter notebook for experimentation.
Key Takeaways
- The GitHub repository provides a hands-on tutorial for Reinforcement Learning with Human Feedback (RLHF) focused on teaching the main steps with minimal code examples.
- The code includes a simple Proximal Policy Optimization (PPO) training loop for updating a language model policy and helper routines for processing and reward computation.
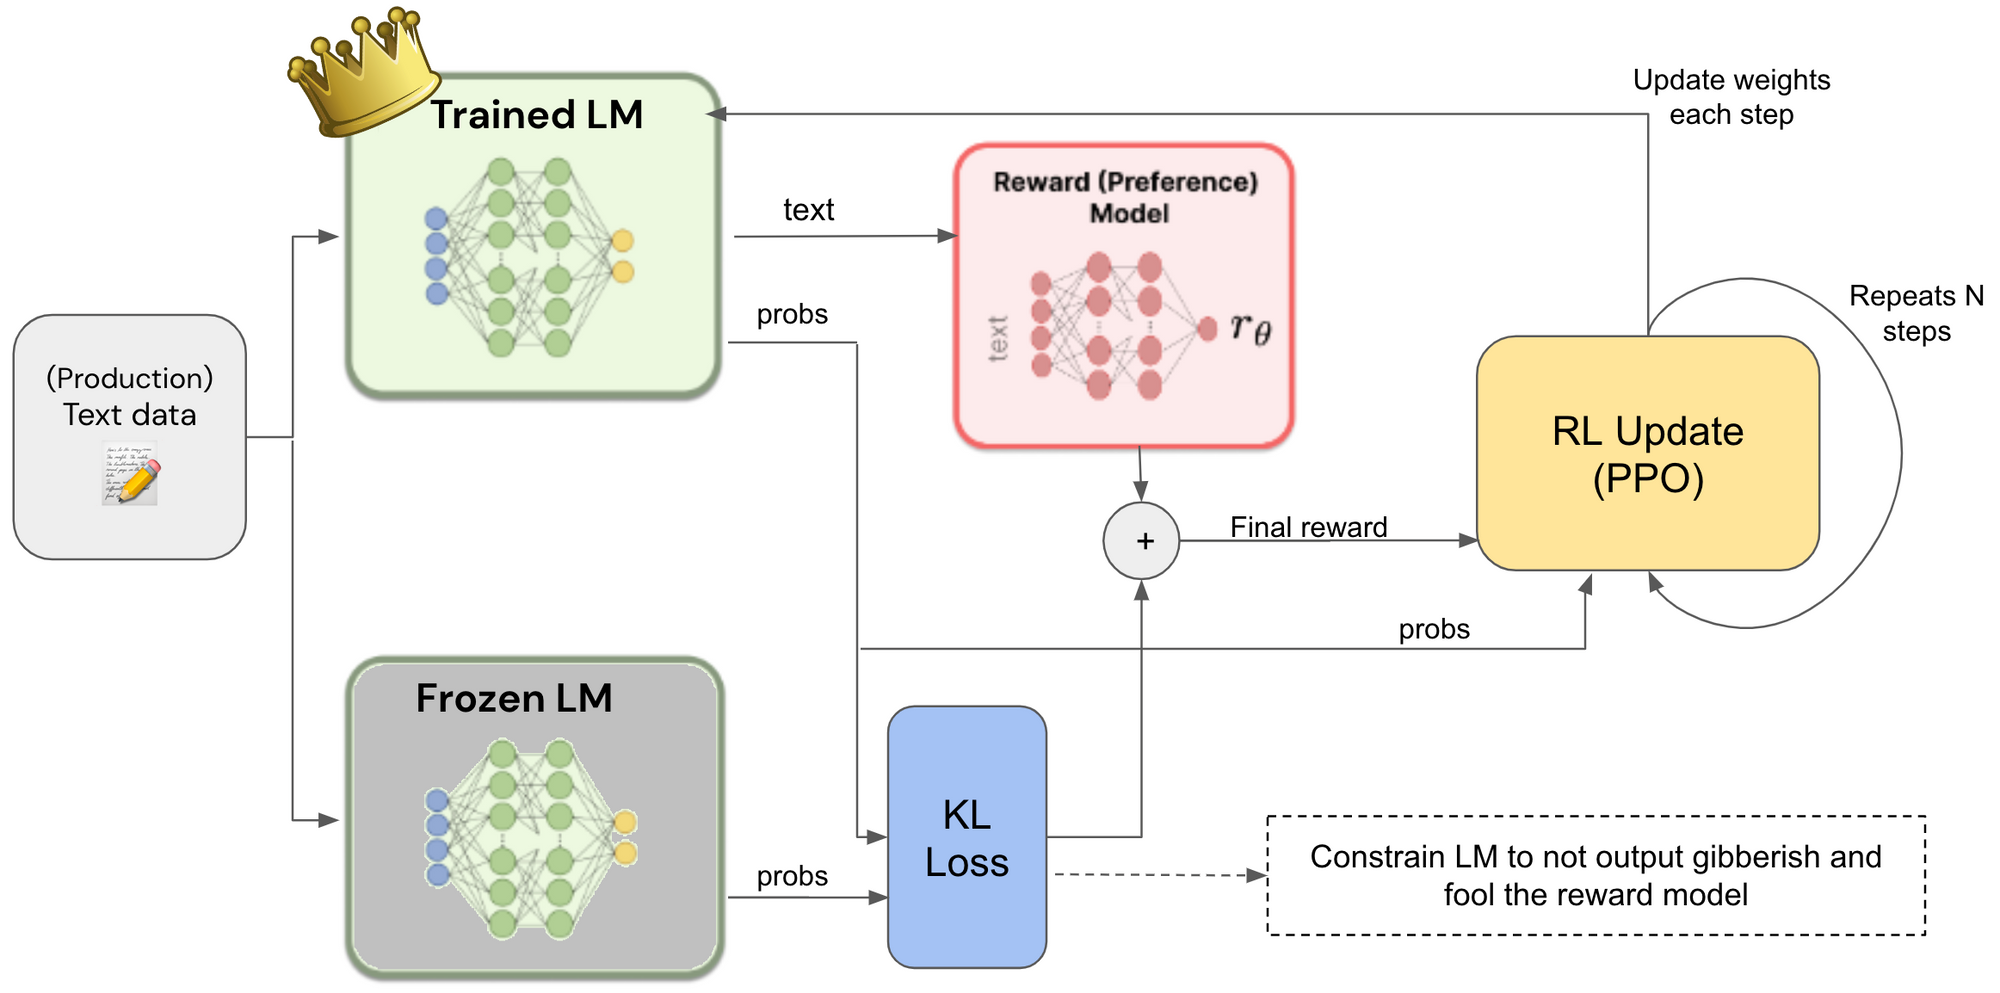
- The tutorial notebook covers the RLHF pipeline, including preference data, reward modeling, and policy optimization, along with runnable code snippets for toy experiments.
- Users can interactively run the tutorial in Jupyter and explore the source code to understand the implementation details.
Coverage & discussions
Hacker News · github.com
Community discussions
Historical count: 2 · 2 saved in sample · Historical sample
Awaiting analysis
Related Articles
Reinforcement Learning from Human Feedback
Feb 7, 2026
Harness Engineering 101: The LLM is the brain, the harness is the body
Oct 19, 2026
If you don't run your own LLM proxy, how do you know whats going on?
Oct 18, 2026

Hybrid Reasoning Agents: LLM agents that think in latent space, act through text
Oct 18, 2026
Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
Oct 16, 2026