TorchTPU: Running PyTorch Natively on TPUs at Google Scale
developers.googleblog.com
April 23, 2026
7 min read
🔥🔥🔥🔥🔥
58/100
Summary
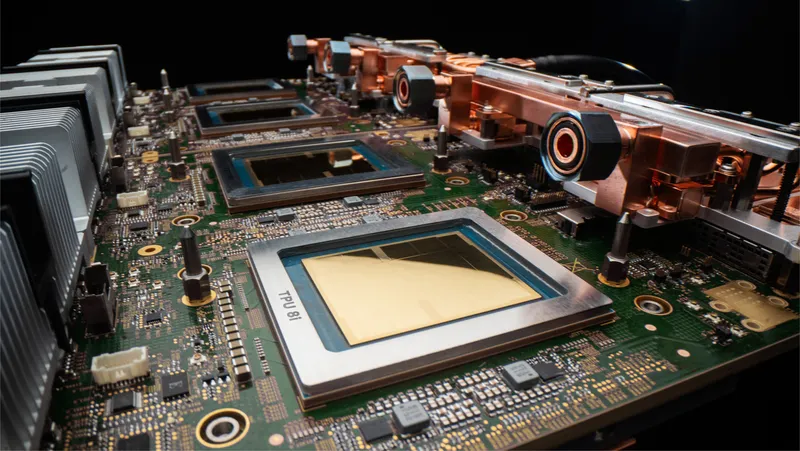
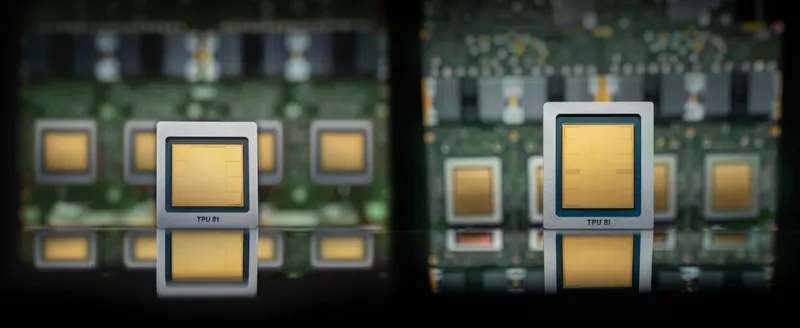
TorchTPU enables running PyTorch natively on Google’s Tensor Processing Units (TPUs), enhancing performance and hardware portability for large-scale machine learning models. It addresses the challenges of distributed systems by supporting clusters of up to 100,000 chips.
Key Takeaways
- TorchTPU enables PyTorch to run natively on Google’s Tensor Processing Units (TPUs) with minimal code changes required from developers.
- The TPU architecture features a highly efficient Inter-Chip Interconnect (ICI) that supports massive scaling without traditional networking bottlenecks.
- TorchTPU implements an "Eager First" philosophy, allowing developers to use familiar PyTorch Tensors on TPUs without needing to modify their core logic.
- Three distinct eager modes—Debug Eager, Strict Eager, and Fused Eager—are designed to support different stages of the development lifecycle in PyTorch on TPUs.
Coverage & discussions
Hacker News · developers.googleblog.com
Community discussions
Community Sentiment
Positives
- TorchTPU's new backend promises improved usability and performance for running PyTorch on TPUs, which could enhance developer experience and model deployment efficiency.
- The use of PrivateUse1 for hardware support in PyTorch allows for convenient integration of new hardware, fostering innovation and flexibility in AI applications.
Concerns
- There are concerns that TorchTPU is a response to previous failures with PyTorch/XLA on TPUs, indicating a lack of trust in the toolchain for production ML.
- The initial lack of support for all operations in TorchTPU raises questions about its readiness for widespread adoption and the potential for compatibility issues.