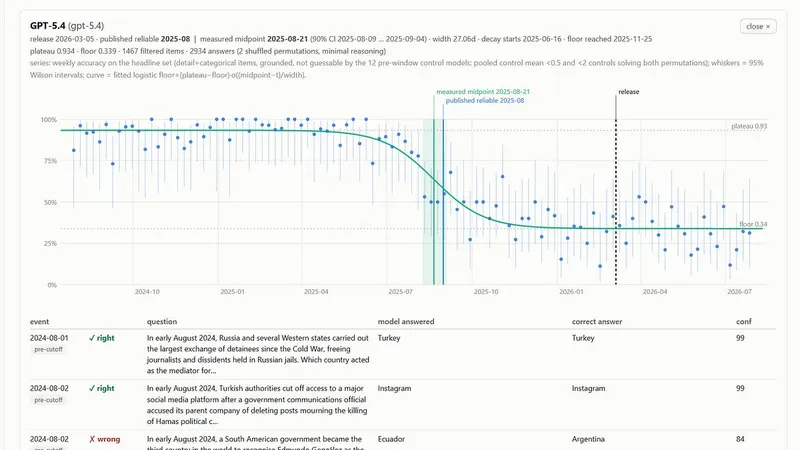
Exploring Claude/GPT Knowledge Cutoffs and Pre-Training Timelines
Probing models like Claude and GPT with curated requests reveals insights into their training processes and knowledge cutoffs. Techniques such as "Incompressible Knowledge Probes" help estimate model parameters and analyze dataset mixtures by measuring token breakdowns.
blog.sshh.io
6 min
8/10/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
Exploring Claude/GPT Knowledge Cutoffs and Pre-Training Timelines
Probing models like Claude and GPT with curated requests reveals insights into their training processes and knowledge cutoffs. Techniques such as "Incompressible Knowledge Probes" help estimate model parameters and analyze dataset mixtures by measuring token breakdowns.
blog.sshh.io
6 min
8/10/2026
MegaTrain: Full Precision Training of 100B+ Parameter LLMs on a Single GPU
MegaTrain is a memory-centric system that enables the full precision training of large language models with over 100 billion parameters on a single GPU. It utilizes host memory to store parameters and optimizer states, treating GPUs as transient computation units.
arxiv.org
2 min
4/8/2026
No more articles to load