14× faster embeddings: how we rebuilt the ONNX path in Manticore
manticoresearch.com
July 3, 2026
14 min read
🔥🔥🔥🔥🔥
48/100
Summary
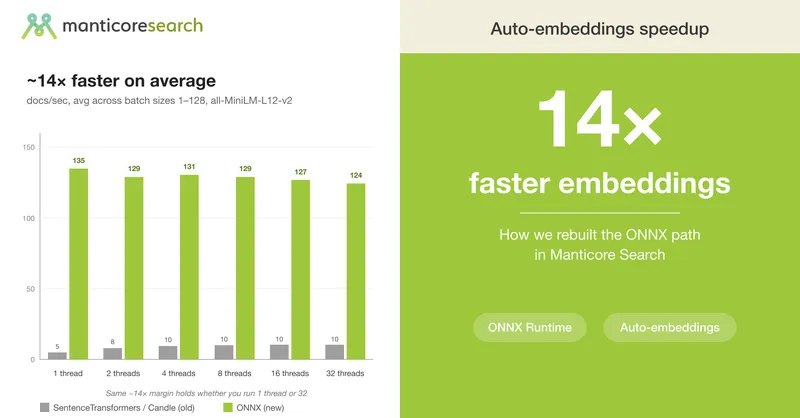
Manticore has rebuilt the ONNX path for Auto Embeddings, achieving a 14× increase in speed for converting text columns into vectors. The previous method using SentenceTransformers and Candle limited throughput, resulting in low document processing rates and serialized concurrent calls.
Key Takeaways
- The new ONNX Runtime backend in Manticore Search 27.1.5 is approximately 14× faster than the previous SentenceTransformers/Candle path for embedding models.
- The ONNX path achieves document processing speeds ranging from 70 to 230 docs/sec, compared to the previous range of 5 to 11 docs/sec.
- Single-insert latency with the new backend is around 14 ms for a single client and 56 ms under 8-way concurrent load, significantly lower than the 200+ ms latency of the old path.
- The new backend allows for improved performance tuning options, enabling users to achieve higher throughput by adjusting batch sizes and concurrency.
Related Articles
RAG Is Simpler Than You Think
Aug 26, 2026
LLM Neuroanatomy II: Modern LLM Hacking and Hints of a Universal Language?
Mar 24, 2026
Fixed three bugs that made Qwen3.5-122B a daily driver on Mac Studio
Jul 11, 2026
Qwen 3.6 27B is the sweet spot for local development
Jun 29, 2026
Unified Memory, Explained: Why Mini PCs Can Run 70B Models a Big GPU Can't
Jul 10, 2026