Attention at Constant Cost per Token via Symmetry-Aware Taylor Approximation
arxiv.org
February 4, 2026
2 min read
55/100
Summary
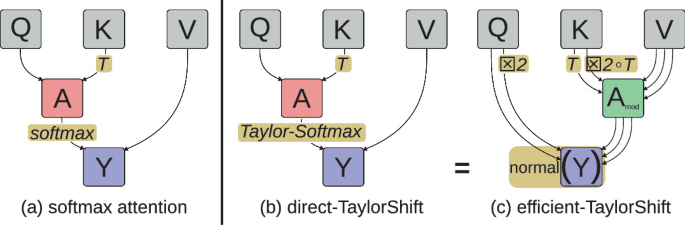
Self-attention mechanisms in Transformers typically incur costs that increase with context length, leading to higher demands for storage, compute, and energy. A new method using symmetry-aware Taylor approximation aims to maintain constant cost per token for self-attention, potentially alleviating these resource demands.
Key Takeaways
- Self-attention can be computed with constant cost per token, achieving significant reductions in memory use and computation.
- The new formulation allows for unbounded token generation at a modest fixed cost, reducing infrastructure and energy demands for large-scale Transformer models.
- The method utilizes symmetry in tensor products to efficiently map queries and keys, enabling a greater number of heads per token than previously feasible.
- The mathematical techniques introduced in the study have independent significance beyond the self-attention context.
Coverage & discussions
Hacker News · arxiv.org
Community discussions
Community Sentiment
Concerns
- The pursuit of linear time attention is fundamentally flawed, as it contradicts established principles of attention mechanisms, suggesting a dead-end in research efforts.
- There are significant concerns that approximating attention may diminish its effectiveness, particularly in scenarios requiring sharp focus on critical information.
- The paper's approach may not adequately address the region of convergence, raising doubts about its mathematical soundness and practical applicability.
Related Articles
Fast KV Compaction via Attention Matching
Feb 20, 2026
A sleep-like consolidation mechanism for LLMs
May 26, 2026

Agentic Context Management: Memory and Cost as Architecture Problems
Aug 26, 2026
Towards Autonomous Mathematics Research
Feb 15, 2026
Do transformers need three projections? Systematic study of QKV variants
Jun 4, 2026