Claw Compactor: compress LLM tokens 54% with zero dependencies
github.com
March 18, 2026
6 min read
50/100
Summary
Claw Compactor is an open-source LLM token compression engine that reduces AI agent token costs by up to 97% using a 14-stage Fusion Pipeline. It features 54% average compression, zero LLM inference cost, and is designed for prompt compression and context window optimization without requiring an LLM.
Key Takeaways
- Claw Compactor achieves an average token compression rate of 54% with zero LLM inference cost.
- The tool utilizes a 14-stage Fusion Pipeline for specialized compression techniques, including AST-aware code analysis and semantic deduplication.
- Claw Compactor allows for reversible compression, enabling retrieval of original content through a hash-addressed storage system.
- The compression rates for various content types, such as JSON and Python source code, show significant improvements over legacy methods, with some achieving over 80% compression.
Coverage & discussions
Hacker News · github.com
Community discussions
Historical count: 2 · 2 saved in sample · Historical sample
Awaiting analysis
Related Articles
60% Fable cost cut by converting code to images and having the model OCR it
Jul 3, 2026
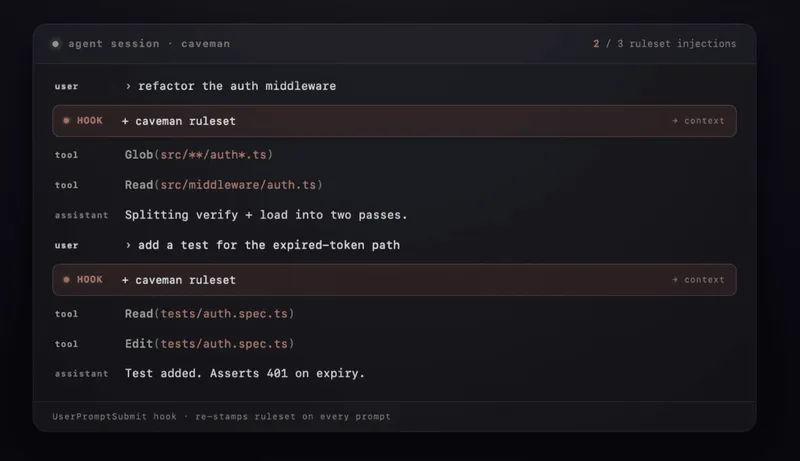
I benchmarked Claude Code's caveman plugin against "be brief."
Apr 29, 2026
GigaToken: ~1000x faster Language model tokenization
Jul 22, 2026
Turbovec – Google's TurboQuant for vector search in Rust
Aug 18, 2026
Run Kimi K3 using 29 GB of RAM at 0.50 tok/s
Jul 31, 2026