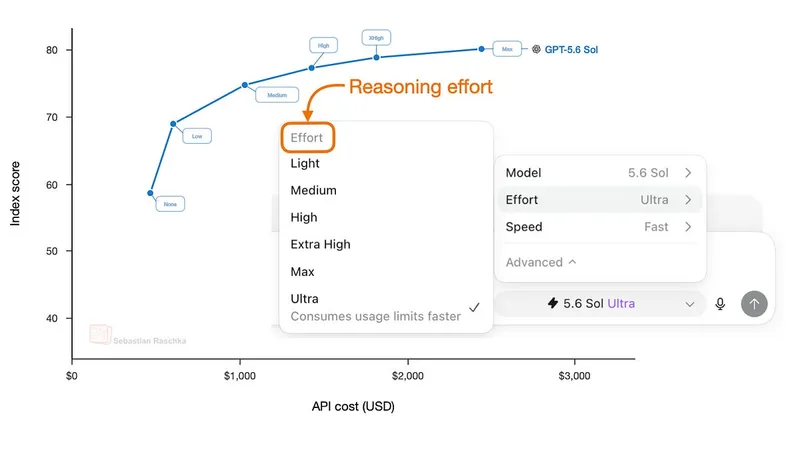
Controlling Reasoning Effort in LLMs
magazine.sebastianraschka.com
July 20, 2026
28 min read
🔥🔥🔥🔥🔥
48/100
Summary
OpenAI released the GPT-5.6 model family, which includes three sizes designed to enhance reasoning capabilities. This model builds on previous advancements in LLM-based reasoning, including the o1 model and DeepSeek-R1, which utilized reinforcement learning with verifiable rewards for training.
Key Takeaways
- OpenAI released the GPT-5.6 model family, which includes three sizes and offers five or six reasoning-effort settings.
- Reasoning models output intermediate reasoning traces that work through tasks step by step, rather than reasoning like humans.
- The DeepSeek-R1 model uses reinforcement learning with verifiable rewards (RLVR) to improve reasoning task performance through training scaling.
- "Aha" moments occur when models self-correct after realizing mistakes during reasoning tasks.
Coverage & discussions
Hacker News · magazine.sebastianraschka.com
Community discussions
Hacker News discussion ↗
Historical count: 2 · 2 saved in sample · Historical sample
Awaiting analysis