DeepSWE: A contamination-free benchmark for long-horizon coding agents
deepswe.datacurve.ai
May 26, 2026
20 min read
🔥🔥🔥🔥🔥
45/100
Summary
DeepSWE is a long-horizon software engineering benchmark designed to evaluate coding agents on original engineering tasks. It features contamination-free tasks, high diversity across 91 repositories in five programming languages, and real-world applicability.
Key Takeaways
- DeepSWE is a long-horizon software engineering benchmark that features contamination-free tasks written from scratch, ensuring no model has seen the solutions during pretraining.
- The benchmark spans 113 tasks across 91 repositories and 5 programming languages, providing high diversity and a realistic assessment of coding agents.
- DeepSWE tasks require significantly more code and output tokens compared to existing benchmarks, reflecting real-world software engineering complexity.
- Each task in DeepSWE is original and not adapted from existing sources, allowing for a more accurate evaluation of an agent's problem-solving capabilities.
Coverage & discussions
Hacker News · deepswe.datacurve.ai
Community discussions
Community Sentiment
Positives
- The normalization of the harness to mini-swe-agent is a significant improvement, allowing models to generalize better across different tools, which is crucial for practical applications.
- The initiative to create a contamination-free benchmark is commendable, as it aims to provide a clearer evaluation of long-horizon coding agents.
Concerns
- The benchmark's 'contamination-free' label may only be valid for its initial release, as it still suffers from fundamental design issues common to benchmarks, such as a focus on single correct answers.
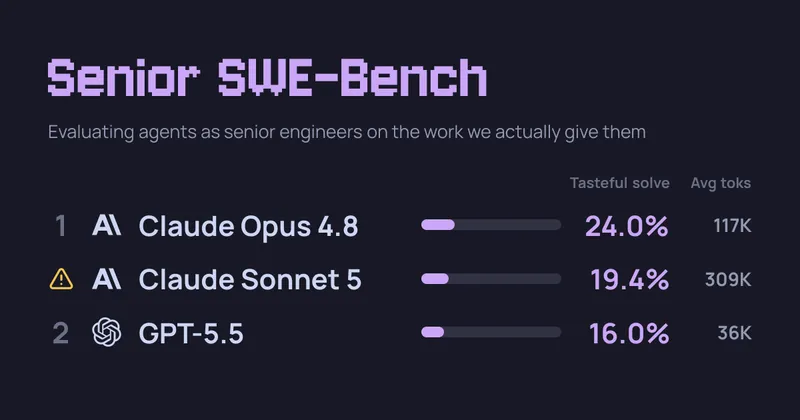
- The saturation of scores at launch suggests that the benchmark may not effectively differentiate between the capabilities of models like Claude and GPT-5.5, raising concerns about its utility.
- The lack of checks for code quality and maintainability in the verifier highlights a significant gap in evaluating the true effectiveness of coding models, which often struggle with code 'taste'.