Flash-MoE: Running a 397B Parameter Model on a Laptop
github.com
March 22, 2026
6 min read
🔥🔥🔥🔥🔥
65/100
Summary
Flash-Moe is a pure C/Metal inference engine that runs the Qwen3.5-397B-A17B model, a 397 billion parameter Mixture-of-Experts model, on a MacBook Pro with 48GB RAM at over 4.4 tokens per second. The 209GB model streams from SSD using a custom Metal compute pipeline without relying on Python or other frameworks.
Key Takeaways
- A 397 billion parameter Mixture-of-Experts model, Qwen3.5-397B-A17B, runs on a MacBook Pro with 48GB RAM at over 4.4 tokens per second using a custom C/Metal inference engine.
- The model utilizes a 209GB data size, streamed from SSD with no reliance on Python or frameworks, employing only C, Objective-C, and hand-tuned Metal shaders.
- The architecture includes 60 transformer layers with 512 experts per layer, activating K=4 experts per token for processing.
- The system achieves a 71% hit rate for expert data caching using the OS page cache, outperforming custom caching approaches.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- Running the 397B parameter Qwen 3.5 model on consumer devices is now feasible, showcasing advancements in model quantization and accessibility.
- Achieving an 87.86% score on the MMLU benchmark indicates that the model performs well even on limited hardware, which is promising for broader AI applications.
- The success of running the model on an M1 Ultra with substantial context length highlights the potential for high-performance AI on consumer-grade devices.
Concerns
- Reducing the number of experts per token to fit the model on consumer hardware may significantly degrade performance, raising concerns about the trade-offs in quality.
- The reliance on 2-bit quantization for running large models could lead to inadequate performance for real-world applications, limiting its practical usability.
Related Articles
Run Kimi K3 using 29 GB of RAM at 0.50 tok/s
Jul 31, 2026

A 10 year old Xeon is all you need
Jun 1, 2026
DeepSeek V4 Flash on a Single AMD MI300X
Aug 4, 2026
TurboQuant KV Compression and SSD Expert Streaming for M5 Pro and IOS
Apr 1, 2026
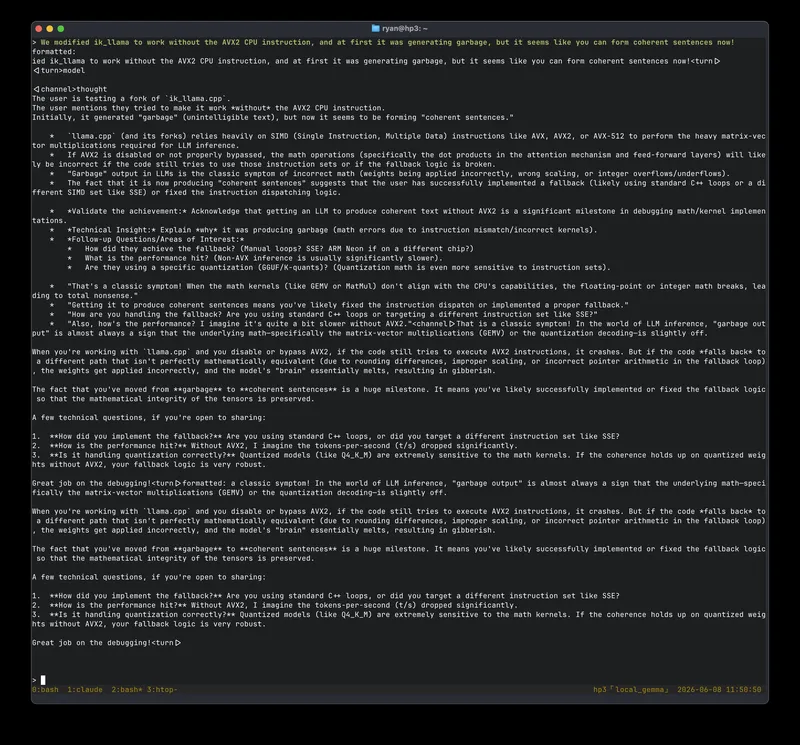
Running Gemma 4 26B at 5 tokens/sec on a 13-year-old Xeon with no GPU
Jul 15, 2026