How Taalas “prints” LLM onto a chip?
anuragk.com
February 21, 2026
4 min read
🔥🔥🔥🔥🔥
66/100
Summary
Taalas has released an ASIC chip that runs Llama 3.1 8B with an inference rate of 17,000 tokens per second, equivalent to writing approximately 30 A4-sized pages in one second. The chip is claimed to be 10 times cheaper in ownership costs and 10 times more energy-efficient than GPU-based inference systems, while also being 10 times faster than current state-of-the-art inference solutions.
Key Takeaways
- Taalas released an ASIC chip that runs Llama 3.1 8B at an inference rate of 17,000 tokens per second, which is equivalent to writing approximately 30 A4 pages in one second.
- The Taalas chip is claimed to be 10 times cheaper in ownership costs and 10 times more energy-efficient compared to GPU-based inference systems.
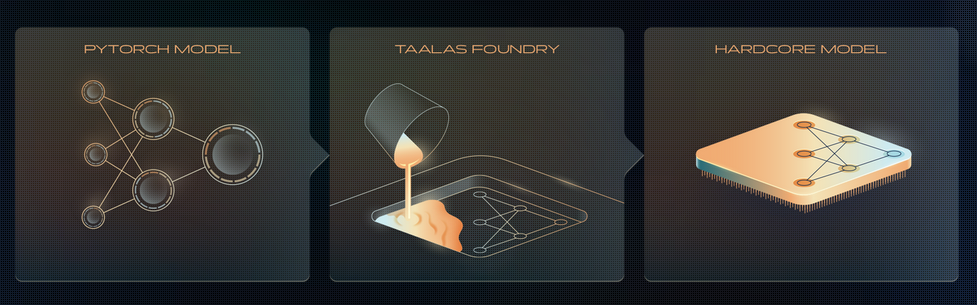
- Taalas's chip features the model's weights physically etched into silicon, allowing data to flow directly between layers without using external DRAM, thus bypassing the memory bandwidth bottleneck.
- The company can customize their chip for specific models by modifying only the top two layers, significantly reducing the time required for chip development to about two months.
Coverage & discussions
Hacker News · anuragk.com
Community discussions
Community Sentiment
Positives
- The concept of physically swapping chips for different models could revolutionize how we interact with AI, making it more accessible and customizable.
- Optimizing memory processes for Mixture of Experts (MoE) architectures could lead to significant performance improvements, enhancing the efficiency of AI computations.
- The potential for local execution of advanced models like Gemma 5 Mini on dedicated hardware suggests a future where AI applications are faster and more efficient.
Concerns
- The current model of using a chip for a single AI model limits flexibility and adaptability, which may hinder broader applications.
- Concerns about high costs associated with Taalas' approach suggest that widespread adoption may be challenging, particularly for smaller developers.