Inside vLLM: Anatomy of a High-Throughput LLM Inference System (2025)
aleksagordic.com
August 6, 2026
36 min read
🔥🔥🔥🔥🔥
54/100
Summary
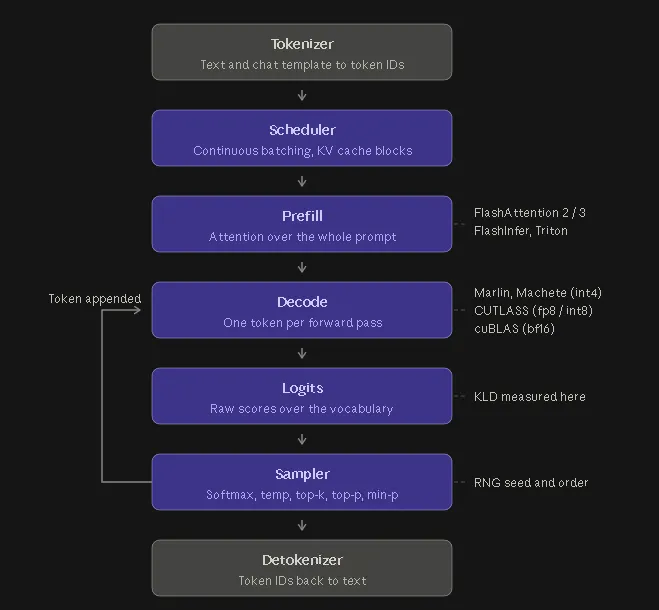
vLLM is a high-throughput LLM inference system that utilizes components such as paged attention, continuous batching, prefix caching, and specdec. It supports multi-GPU and multi-node dynamic serving to enhance performance at scale.
Key Takeaways
- vLLM is a high-throughput LLM inference system that utilizes components like paged attention, continuous batching, and prefix caching to enhance performance.
- The LLM engine serves as the core building block of vLLM, enabling high-throughput inference in offline settings before transitioning to online, multi-GPU, multi-node configurations.
- Key features of vLLM include chunked prefill, guided and speculative decoding, and a distributed serving layer for concurrent web access.
- The system is designed for scalability, evolving from single-GPU execution to more complex multi-GPU and multi-node setups.
Coverage & discussions
Hacker News · aleksagordic.com
Community discussions
Hacker News discussion ↗
Historical count: 3 · 3 saved in sample · Historical sample
Awaiting analysis