Talk like caveman
github.com
April 5, 2026
2 min read
🔥🔥🔥🔥🔥
74/100
Summary
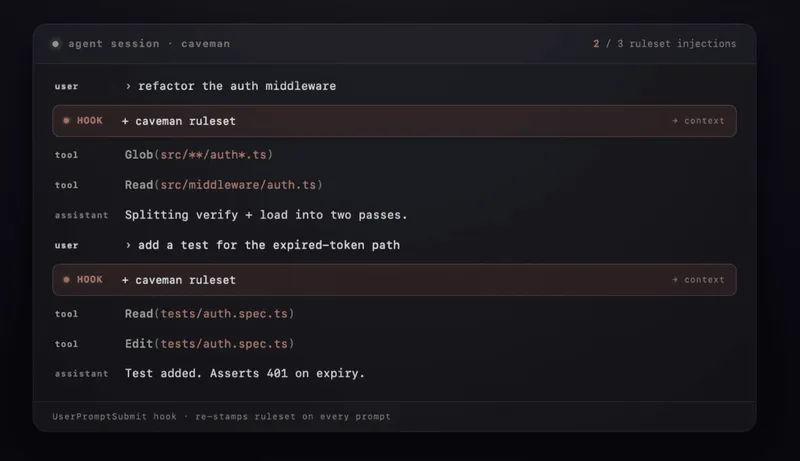
Claude Code's caveman skill reduces token usage by approximately 75% while maintaining technical accuracy. Users can install it via a one-line command or through the Claude Code plugin system.
Key Takeaways
- The Claude Code skill "caveman" reduces token usage by approximately 75% while maintaining full technical accuracy.
- Users can install the "caveman" skill with a one-line command, enabling a simplified communication style that eliminates filler words.
- The implementation of "caveman" mode results in faster response times, achieving nearly three times the speed of standard outputs.
- The use of "caveman" can lead to significant cost savings due to reduced token consumption.
Coverage & discussions
Hacker News · github.com
Community discussions
Community Sentiment
Positives
- The ability to control verbosity in API responses allows developers to tailor outputs for specific use cases, enhancing the flexibility of LLM applications.
- Experimenting with concise communication styles can lead to interesting insights about how LLMs process and generate language, potentially improving user interaction.
Concerns
- Forcing LLMs to be concise can limit their computational capacity, leading to poorer responses as the model struggles to generate quality answers within token constraints.
- Users report that using fewer words often results in misunderstandings and less effective communication, indicating that context is crucial for LLM performance.